Bayesian inference for the information gain model
Related Experiment Video
Updated: Jun 4, 2026
Quantification of Information Encoded by Gene Expression Levels During Lifespan Modulation Under Broad-range Dietary Restriction in C. elegans
Published on: August 16, 2017
Sven Stringer1, Denny Borsboom, Eric-Jan Wagenmakers
1Department of Psychology, University of Amsterdam, Roetersstraat 15, 1018 Amsterdam, The Netherlands.

Abstract:
One of the most popular paradigms to use for studying human reasoning involves the Wason card selection task. In this task, the participant is presented with four cards and a conditional rule (e.g., "If there is an A on one side of the card, there is always a 2 on the other side"). Participants are asked which cards should be turned to verify whether or not the rule holds. In this simple task, participants consistently provide answers that are incorrect according to formal logic. To account for these errors, several models have been proposed, one of the most prominent being the information gain model (Oaksford & Chater, Psychological Review, 101, 608-631, 1994). This model is based on the assumption that people independently select cards based on the expected information gain of turning a particular card. In this article, we present two estimation methods to fit the information gain model: a maximum likelihood procedure (programmed in R) and a bayesian procedure (programmed in WinBUGS). We compare the two procedures and illustrate the flexibility of the bayesian hierarchical procedure by applying it to data from a meta-analysis of the Wason task (Oaksford & Chater, Psychological Review, 101, 608-631, 1994). We also show that the goodness of fit of the information gain model can be assessed by inspecting the posterior predictives of the model. These bayesian procedures make it easy to apply the information gain model to empirical data. Supplemental materials may be downloaded along with this article from www.springerlink.com.

Related Concept Videos
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance, comparing...
 01:15
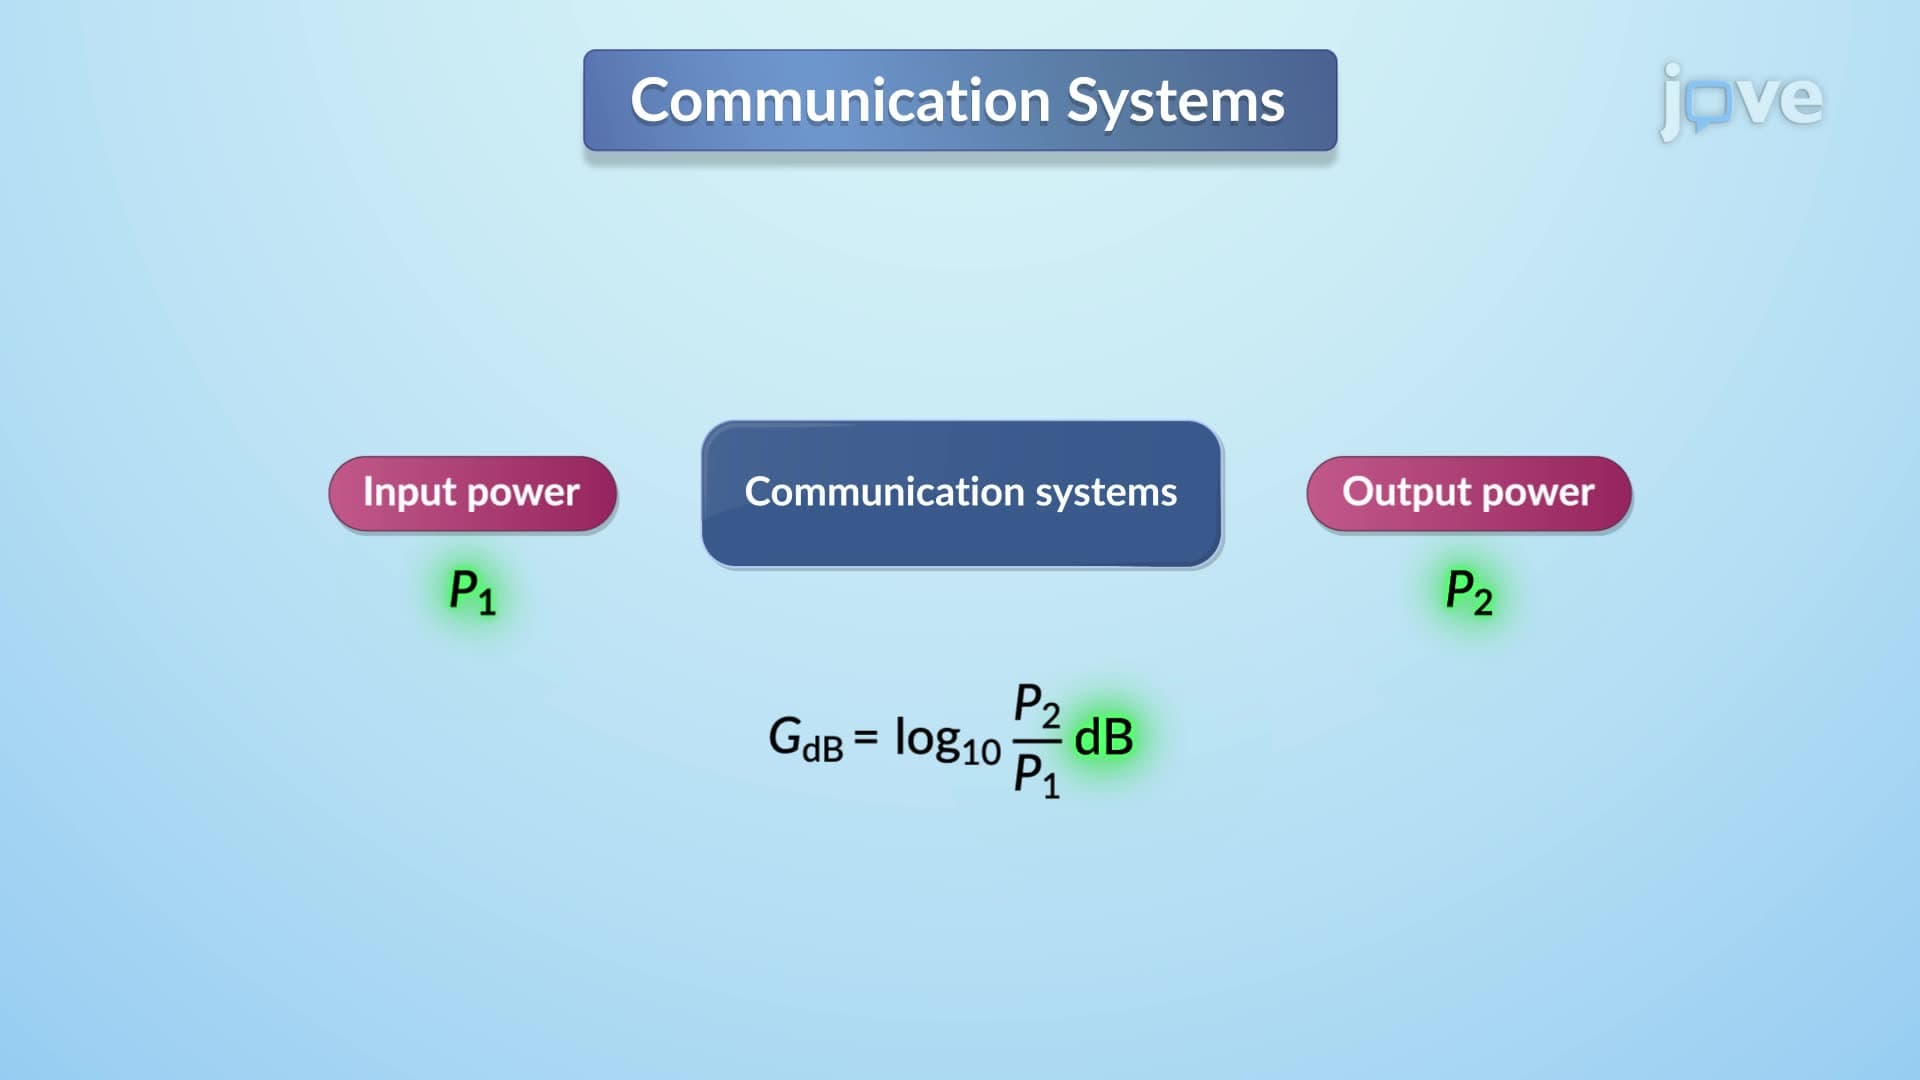
Gain
Gain:
Suppose Vin is the input and Vout is the output signal to a circuit.
 01:06
Model Approaches for Pharmacokinetic Data: Distributed Parameter Models
The distributed parameter models are specifically designed to account for variations and differences in some drug classes. This model is particularly useful for assessing regional concentrations of anticancer or...
 01:30
Information Processing Approach
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
The...
 01:15
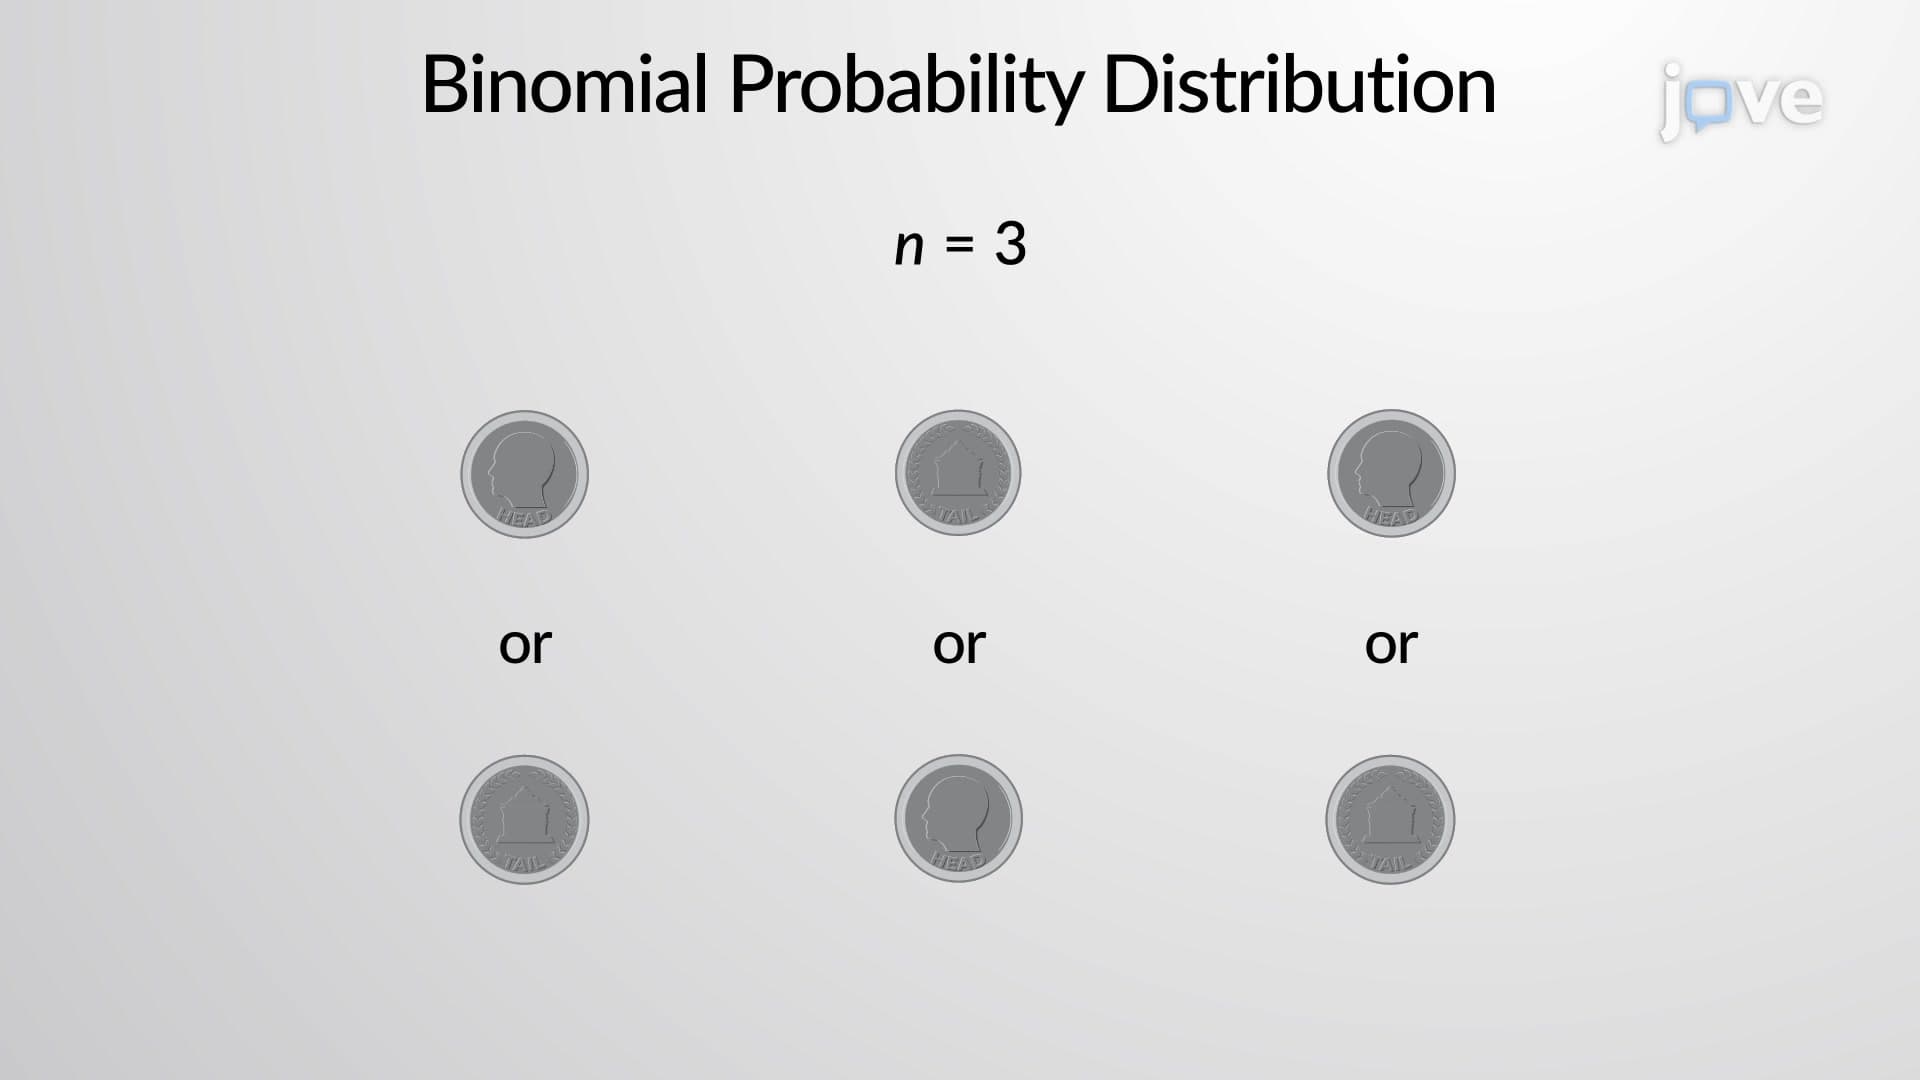
Binomial Probability Distribution
The outcomes of a binomial experiment fit a binomial probability distribution. A statistical experiment can be classified as a binomial experiment if the following conditions are met:
There are a fixed number of trials. Think of trials as repetitions of an experiment. The letter n denotes the number of trials.
There are only two possible outcomes,...