Dynamic programming re-ranking for PPI interactor and pair extraction in full-text articles
Related Experiment Videos
Richard Tzong-Han Tsai1, Po-Ting Lai
1Department of Computer Science & Engineering, Yuan Ze University, Chung-Li, Taiwan, R.O.C. thtsai@saturn.yzu.edu.tw

Background:
Experimentally verified protein-protein interactions (PPIs) cannot be easily retrieved by researchers unless they are stored in PPI databases. The curation of such databases can be facilitated by employing text-mining systems to identify genes which play the interactor role in PPIs and to map these genes to unique database identifiers (interactor normalization task or INT) and then to return a list of interaction pairs for each article (interaction pair task or IPT). These two tasks are evaluated in terms of the area under curve of the interpolated precision/recall (AUC iP/R) score because the order of identifiers in the output list is important for ease of curation.
Results:
Our INT system developed for the BioCreAtIvE II.5 INT challenge achieved a promising AUC iP/R of 43.5% by using a support vector machine (SVM)-based ranking procedure. Using our new re-ranking algorithm, we have been able to improve system performance (AUC iP/R) by 1.84%. Our experimental results also show that with the re-ranked INT results, our unsupervised IPT system can achieve a competitive AUC iP/R of 23.86%, which outperforms the best BC II.5 INT system by 1.64%. Compared to using only SVM ranked INT results, using re-ranked INT results boosts AUC iP/R by 7.84%. Statistical significance t-test results show that our INT/IPT system with re-ranking outperforms that without re-ranking by a statistically significant difference.
Conclusions:
In this paper, we present a new re-ranking algorithm that considers co-occurrence among identifiers in an article to improve INT and IPT ranking results. Combining the re-ranked INT results with an unsupervised approach to find associations among interactors, the proposed method can boost the IPT performance. We also implement score computation using dynamic programming, which is faster and more efficient than traditional approaches.
Related Concept Videos
 00:56
Extraction: Advanced Methods
 01:14
Extraction: Partition and Distribution Coefficients
For extracting a solute from an aqueous phase into an organic...
 01:09
Decision Making: P-value Method
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can have a...
 01:10
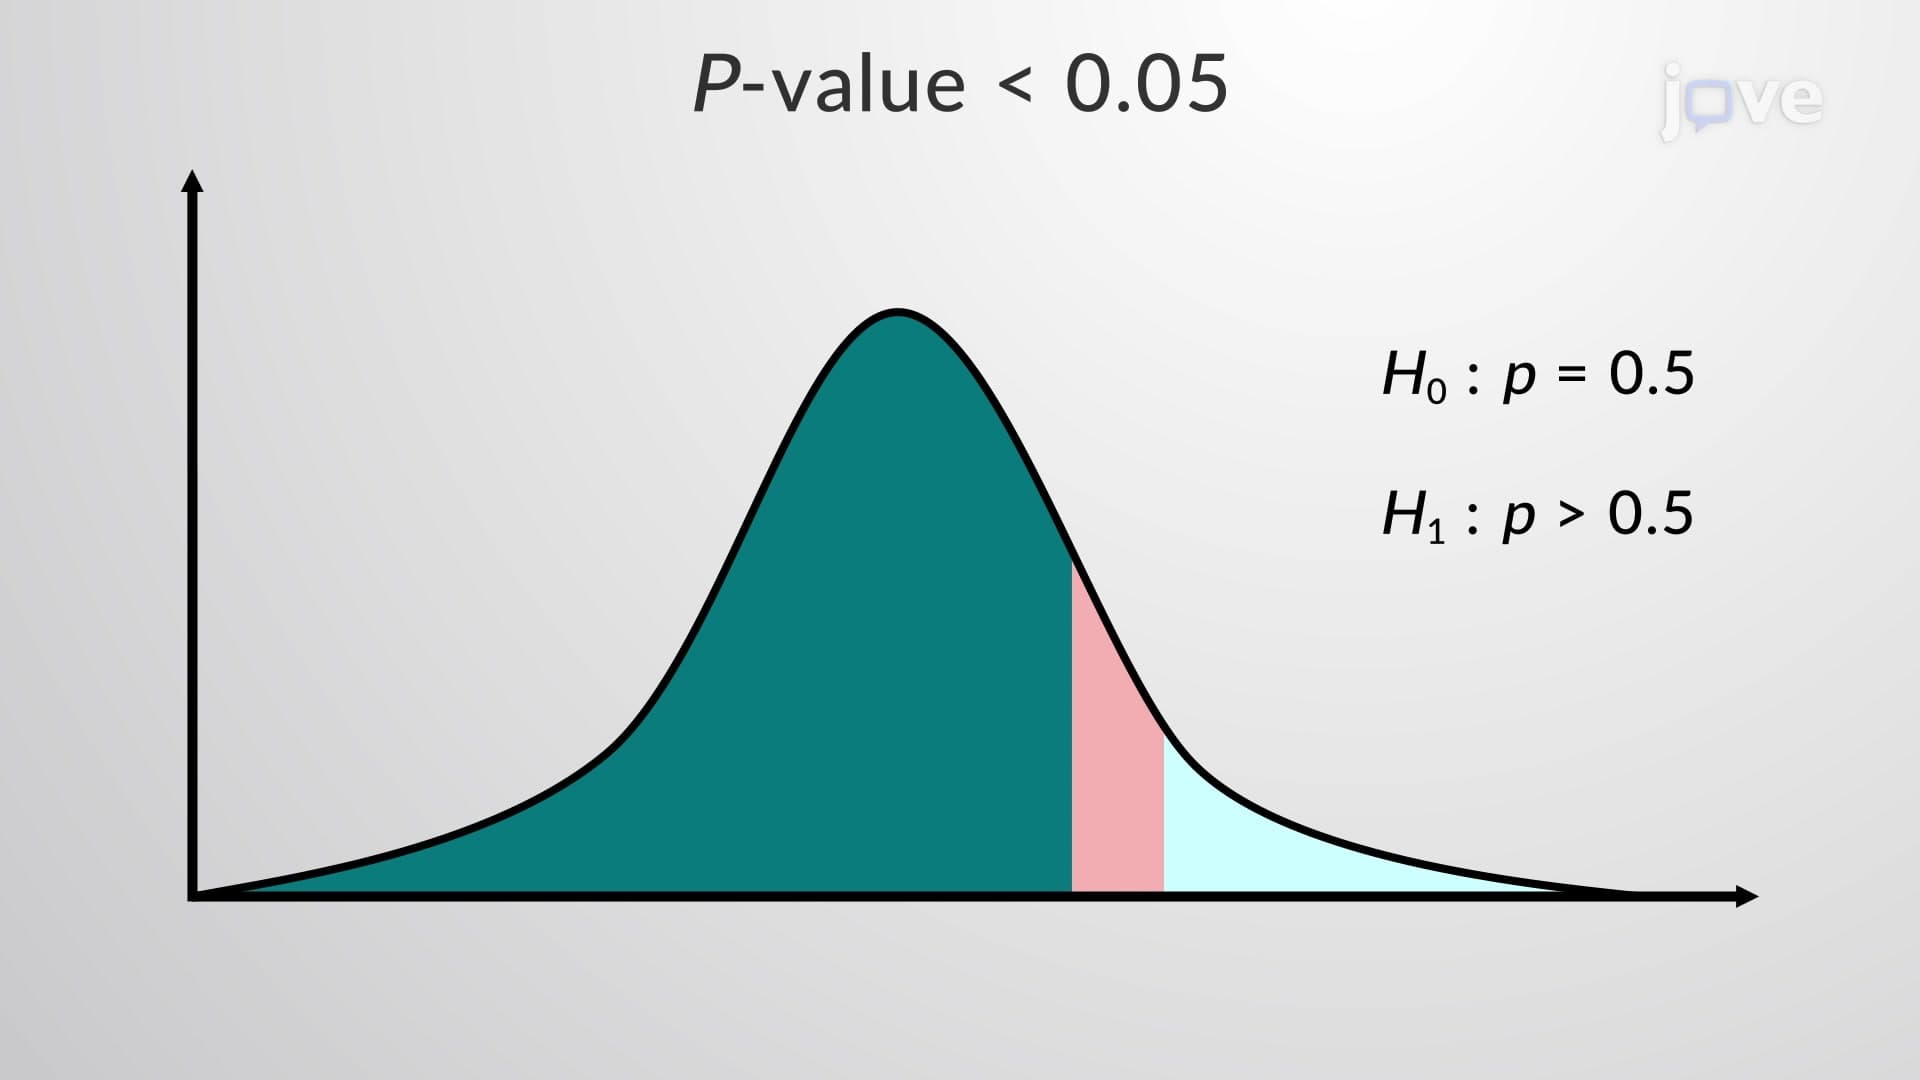
P-value
P-value stands for the probability value. P-value is the probability that, if the null hypothesis is true, the results from another randomly selected sample will be as extreme or more extreme as the results obtained from the given sample.
A large P-value calculated from the data indicates to not reject the null hypothesis. But a higher P-value does not mean that the null hypothesis is true. The smaller the P-value, the more unlikely...
 01:57
Protein Complexes with Interchangeable Parts
The SCF ubiquitin ligase is a protein complex of five individual proteins. This complex attaches ubiquitin to other target proteins to mark them for degradation. In order to...
01:57Protein Complexes with Interchangeable Parts
The SCF ubiquitin ligase is a protein complex of five individual proteins. This complex attaches ubiquitin to other target proteins to mark them for degradation. In order to...