Related Experiment Video
Updated: Jun 1, 2026
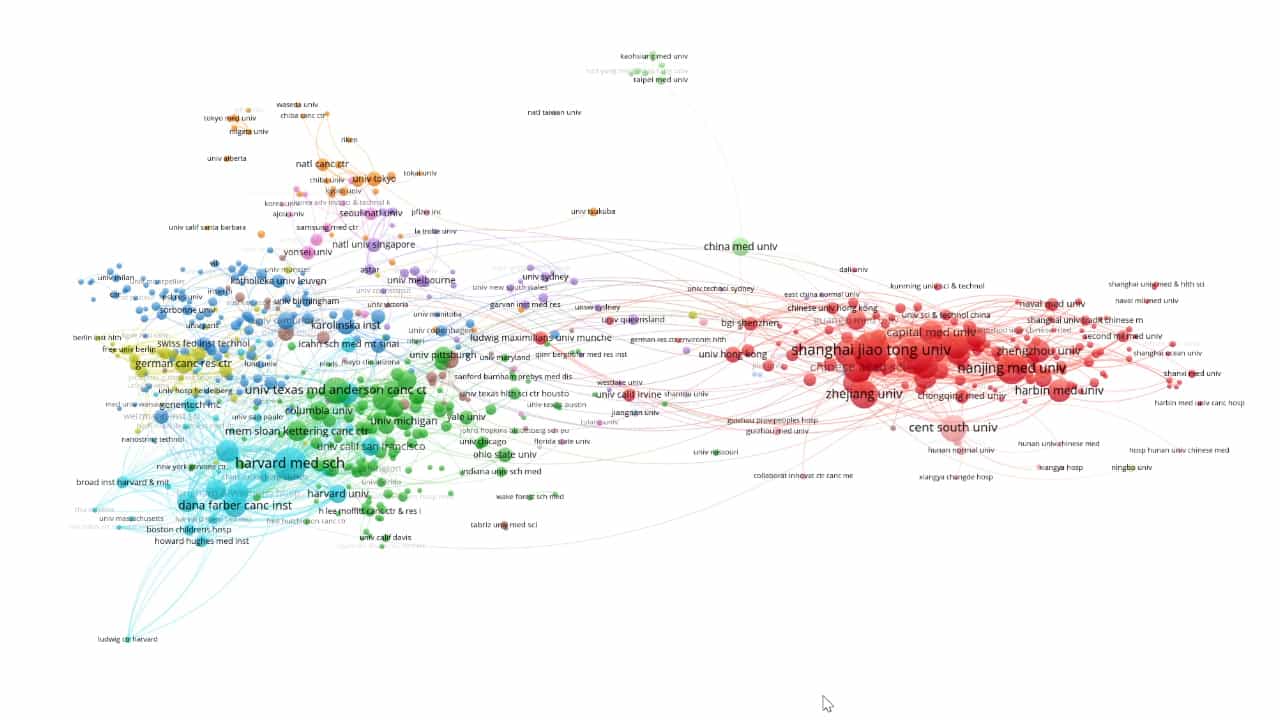

Global and Current Research Trends of Single-Cell Sequencing in Cancer: A Bibliometric and Visualization Study
Published on: April 18, 2025
A simple index for the high-citation tail of citation distribution to quantify research performance in countries and
1Centro de Biotecnología y Genómica de Plantas, Universidad Politécnica de Madrid, Madrid, Spain. alonso.rodriguez@upm.es

Background:
Conventional scientometric predictors of research performance such as the number of papers, citations, and papers in the top 1% of highly cited papers cannot be validated in terms of the number of Nobel Prize achievements across countries and institutions. The purpose of this paper is to find a bibliometric indicator that correlates with the number of Nobel Prize achievements.
Methodology/Principal Findings:
This study assumes that the high-citation tail of citation distribution holds most of the information about high scientific performance. Here I propose the x-index, which is calculated from the number of national articles in the top 1% and 0.1% of highly cited papers and has a subtractive term to discount highly cited papers that are not scientific breakthroughs. The x-index, the number of Nobel Prize achievements, and the number of national articles in Nature or Science are highly correlated. The high correlations among these independent parameters demonstrate that they are good measures of high scientific performance because scientific excellence is their only common characteristic. However, the x-index has superior features as compared to the other two parameters. Nobel Prize achievements are low frequency events and their number is an imprecise indicator, which in addition is zero in most institutions; the evaluation of research making use of the number of publications in prestigious journals is not advised.
Conclusion:
The x-index is a simple and precise indicator for high research performance.
Related Concept Videos
 01:18
Percentile
 01:10
Central Tendency: Analysis
The mean is one such measure, calculated by totaling all values in a dataset and dividing by the number of values. For instance, the mean blood pressure reading (120, 130, 140, 150) would be 135. However, the mean can be affected by extreme values or outliers.
The median, another measure,...
 01:15
Quartile
1; 1; 2; 2; 4; 6; 6.8; 7.2; 8; 8.3; 9; 10; 10; 11.5
The median or second quartile is seven. The lower half of the...
 02:16
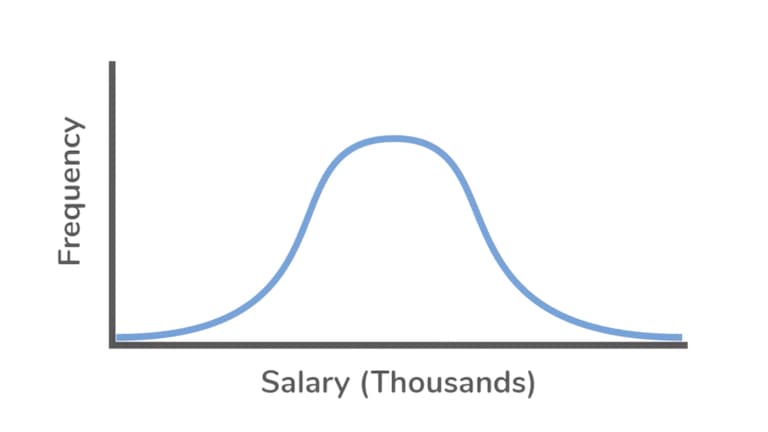
Measures of Central Tendency
 01:08
Outliers and Influential Points
 01:14
Relative Frequency Histogram