Querying large read collections in main memory: a versatile data structure
Related Experiment Video
Updated: May 31, 2026
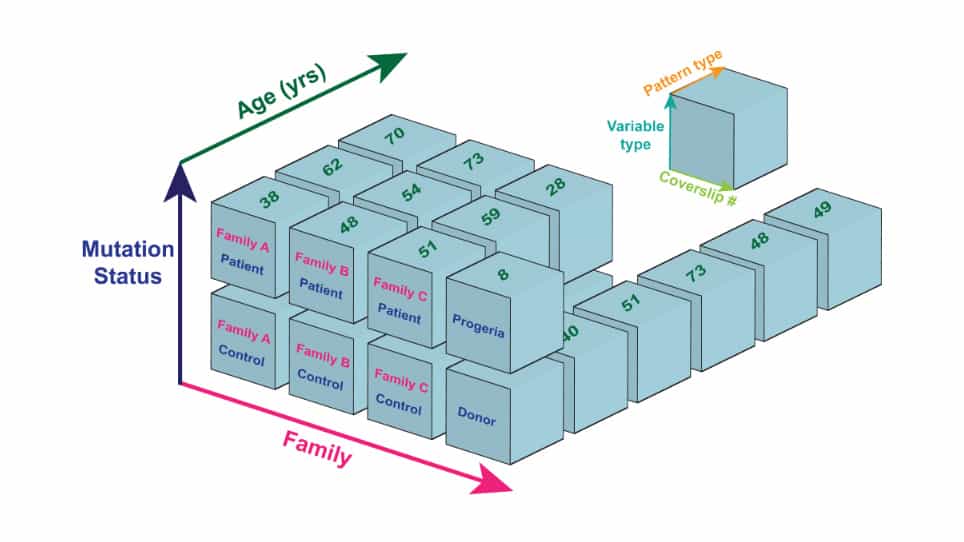
Databases to Efficiently Manage Medium Sized, Low Velocity, Multidimensional Data in Tissue Engineering
Published on: November 22, 2019
Nicolas Philippe1, Mikaël Salson, Thierry Lecroq
1LIRMM, UMR 5506, CNRS and Université de Montpellier 2, CC 477, 161 rue Ada, 34095 Montpellier, France.

Background:
High Throughput Sequencing (HTS) is now heavily exploited for genome (re-) sequencing, metagenomics, epigenomics, and transcriptomics and requires different, but computer intensive bioinformatic analyses. When a reference genome is available, mapping reads on it is the first step of this analysis. Read mapping programs owe their efficiency to the use of involved genome indexing data structures, like the Burrows-Wheeler transform. Recent solutions index both the genome, and the k-mers of the reads using hash-tables to further increase efficiency and accuracy. In various contexts (e.g. assembly or transcriptome analysis), read processing requires to determine the sub-collection of reads that are related to a given sequence, which is done by searching for some k-mers in the reads. Currently, many developments have focused on genome indexing structures for read mapping, but the question of read indexing remains broadly unexplored. However, the increase in sequence throughput urges for new algorithmic solutions to query large read collections efficiently.
Results:
Here, we present a solution, named Gk arrays, to index large collections of reads, an algorithm to build the structure, and procedures to query it. Once constructed, the index structure is kept in main memory and is repeatedly accessed to answer queries like "given a k-mer, get the reads containing this k-mer (once/at least once)". We compared our structure to other solutions that adapt uncompressed indexing structures designed for long texts and show that it processes queries fast, while requiring much less memory. Our structure can thus handle larger read collections. We provide examples where such queries are adapted to different types of read analysis (SNP detection, assembly, RNA-Seq).
Conclusions:
Gk arrays constitute a versatile data structure that enables fast and more accurate read analysis in various contexts. The Gk arrays provide a flexible brick to design innovative programs that mine efficiently genomics, epigenomics, metagenomics, or transcriptomics reads. The Gk arrays library is available under Cecill (GPL compliant) license from http://www.atgc-montpellier.fr/ngs/.
Related Concept Videos
 01:12
Maximum Size of Aggregate
 01:19
Understanding Memory
 01:08
Data Collection by Observations
An astronomer viewing the motion and brightness of stars in the sky and recording the data is an example of observational data collection. A botanist recording...
 01:23
Storage
 01:05
Data Collection III
The principles to begin the physical assessment include conducting a comprehensive or problem-related history in a quiet, well-lit room, emphasizing privacy and comfort for the patient.
 01:23
System of Memory