Topical perspective on massive threading and parallelism
Related Experiment Video
Updated: May 31, 2026
Perspectives on Neuroscience
Published on: July 31, 2007
1PNNL, P.O. Box 999, Richland, WA 99352, USA. rmfarber@usa.net

Abstract:
Unquestionably computer architectures have undergone a recent and noteworthy paradigm shift that now delivers multi- and many-core systems with tens to many thousands of concurrent hardware processing elements per workstation or supercomputer node. GPGPU (General Purpose Graphics Processor Unit) technology in particular has attracted significant attention as new software development capabilities, namely CUDA (Compute Unified Device Architecture) and OpenCL™, have made it possible for students as well as small and large research organizations to achieve excellent speedup for many applications over more conventional computing architectures. The current scientific literature reflects this shift with numerous examples of GPGPU applications that have achieved one, two, and in some special cases, three-orders of magnitude increased computational performance through the use of massive threading to exploit parallelism. Multi-core architectures are also evolving quickly to exploit both massive-threading and massive-parallelism such as the 1.3 million threads Blue Waters supercomputer. The challenge confronting scientists in planning future experimental and theoretical research efforts--be they individual efforts with one computer or collaborative efforts proposing to use the largest supercomputers in the world is how to capitalize on these new massively threaded computational architectures--especially as not all computational problems will scale to massive parallelism. In particular, the costs associated with restructuring software (and potentially redesigning algorithms) to exploit the parallelism of these multi- and many-threaded machines must be considered along with application scalability and lifespan. This perspective is an overview of the current state of threading and parallelize with some insight into the future.
More Related Videos
Related Concept Videos
 01:20
Parallel Processing
 01:06
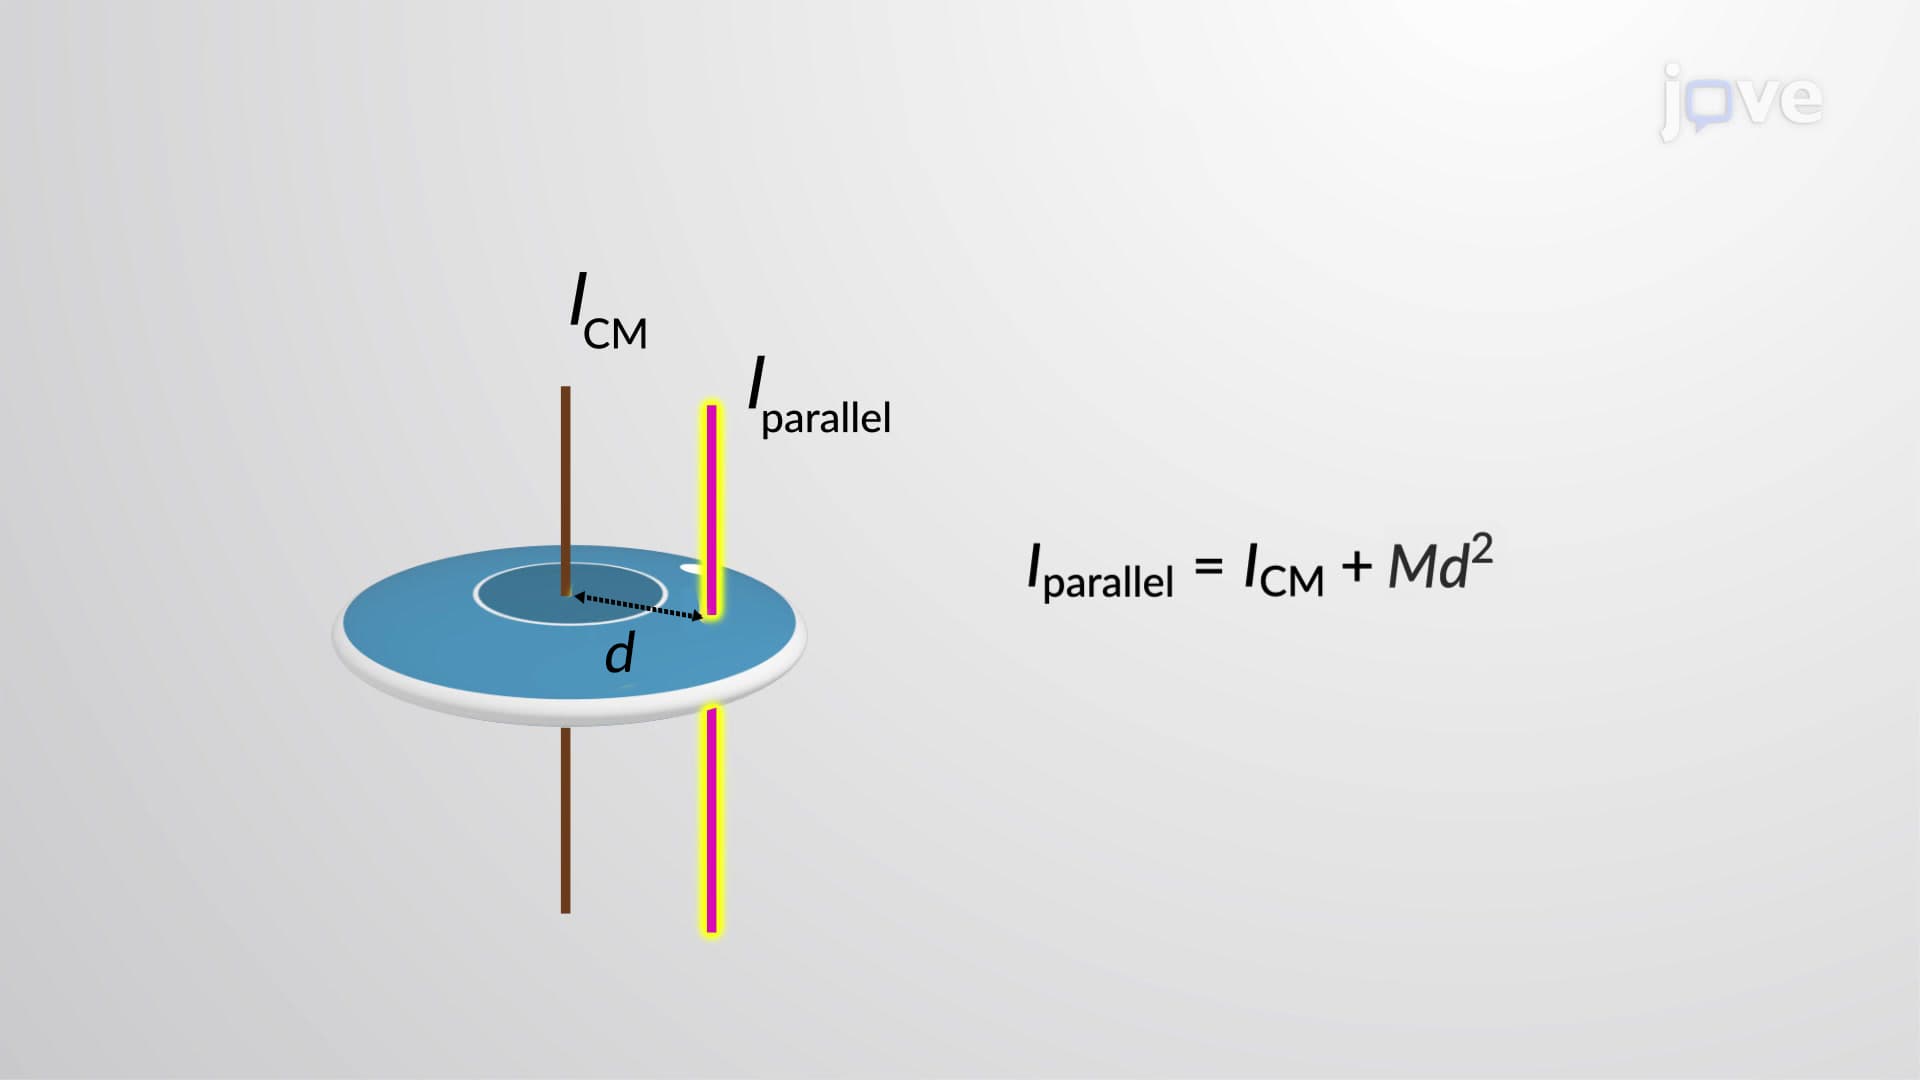
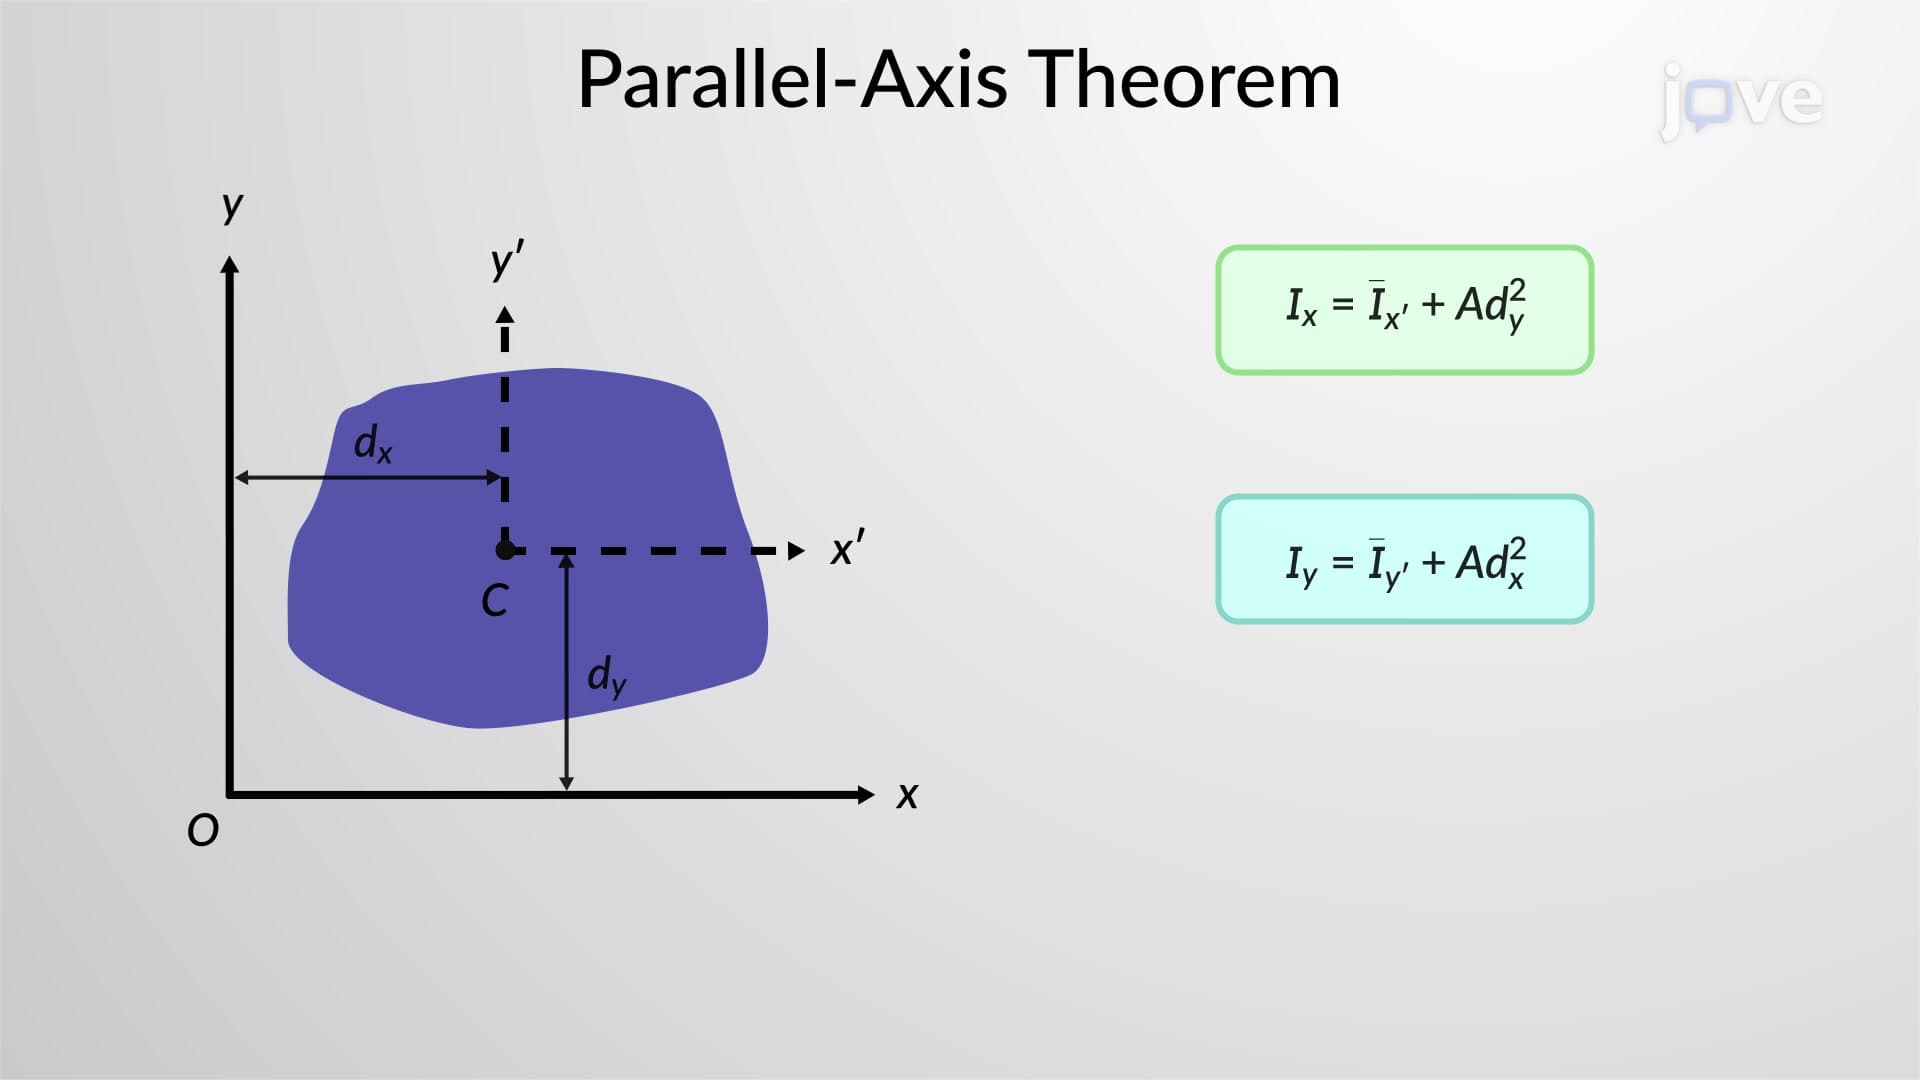
Parallel-axis Theorem
 01:12
Parallel-Axis Theorem for an Area
For a flywheel approximated as a solid disc, consider an infinitesimal differential element with an arbitrary distance...
 01:23
Parallel Resonance
 01:10
Column Efficiency: Plate Theory
A higher number of theoretical plates signifies better column efficiency and improved separation capabilities. Plate height affects bandwidth and separation quality; it is inversely...
 01:59
Lagging Strand Synthesis
There are several major differences between synthesis of the leading strand and synthesis of the lagging strand. 1) Leading strand synthesis happens in the direction of replication fork opening, whereas lagging strand synthesis happens in the...