Maximum margin Bayesian network classifiers
Related Experiment Video
Updated: May 30, 2026

Selecting Multiple Biomarker Subsets with Similarly Effective Binary Classification Performances
Published on: October 11, 2018
Franz Pernkopf1, Michael Wohlmayr, Sebastian Tschiatschek
1Laboratory of Signal Processing and Speech Communication, Department of Electrical Engineering, Graz University of Technology, Inffeldgasse 16c, Graz A-8010, Austria. pernkopf@tugraz.at

Abstract:
We present a maximum margin parameter learning algorithm for Bayesian network classifiers using a conjugate gradient (CG) method for optimization. In contrast to previous approaches, we maintain the normalization constraints on the parameters of the Bayesian network during optimization, i.e., the probabilistic interpretation of the model is not lost. This enables us to handle missing features in discriminatively optimized Bayesian networks. In experiments, we compare the classification performance of maximum margin parameter learning to conditional likelihood and maximum likelihood learning approaches. Discriminative parameter learning significantly outperforms generative maximum likelihood estimation for naive Bayes and tree augmented naive Bayes structures on all considered data sets. Furthermore, maximizing the margin dominates the conditional likelihood approach in terms of classification performance in most cases. We provide results for a recently proposed maximum margin optimization approach based on convex relaxation. While the classification results are highly similar, our CG-based optimization is computationally up to orders of magnitude faster. Margin-optimized Bayesian network classifiers achieve classification performance comparable to support vector machines (SVMs) using fewer parameters. Moreover, we show that unanticipated missing feature values during classification can be easily processed by discriminatively optimized Bayesian network classifiers, a case where discriminative classifiers usually require mechanisms to complete unknown feature values in the data first.
Related Concept Videos
 01:27
Margin of Error
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
The...
 01:29
Aggregates Classification
Petrographic classification groups aggregates based on common mineralogical characteristics. Some of the common mineral groups found in aggregates are...
 01:31
Classification of Systems-II
 01:15
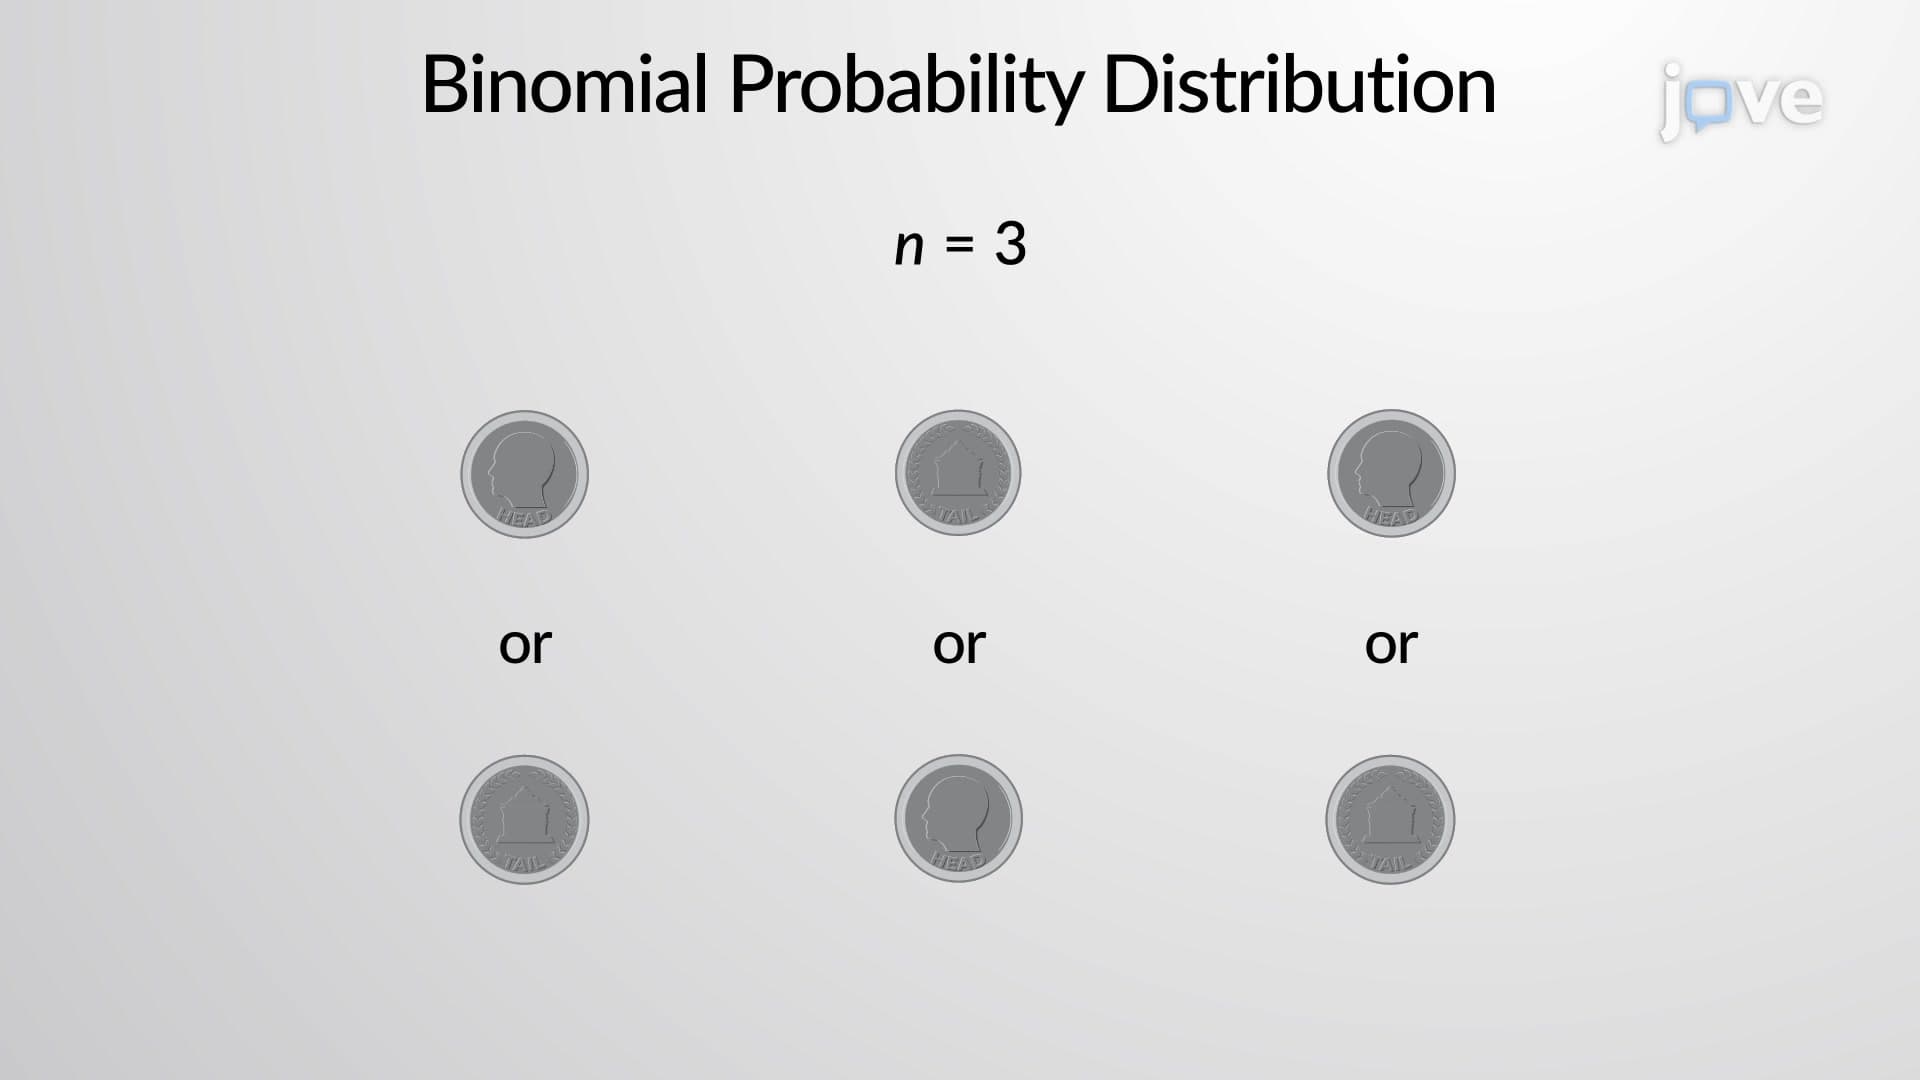
Binomial Probability Distribution
The outcomes of a binomial experiment fit a binomial probability distribution. A statistical experiment can be classified as a binomial experiment if the following conditions are met:
There are a fixed number of trials. Think of trials as repetitions of an experiment. The letter n denotes the number of trials.
There are only two possible outcomes,...
 01:26
Classification of Systems-I
Homogeneity dictates that if an input x(t) is multiplied by a constant c, the output y(t) is multiplied by the same constant. Mathematically, this is expressed as: