The sensitivity of the modified viterbi algorithm to the source statistics

R Shinghal1, G T Toussaint

  • 1Department of Computer Science, Concordia University, Montreal, P.Q., Canada.

Related Concept Videos

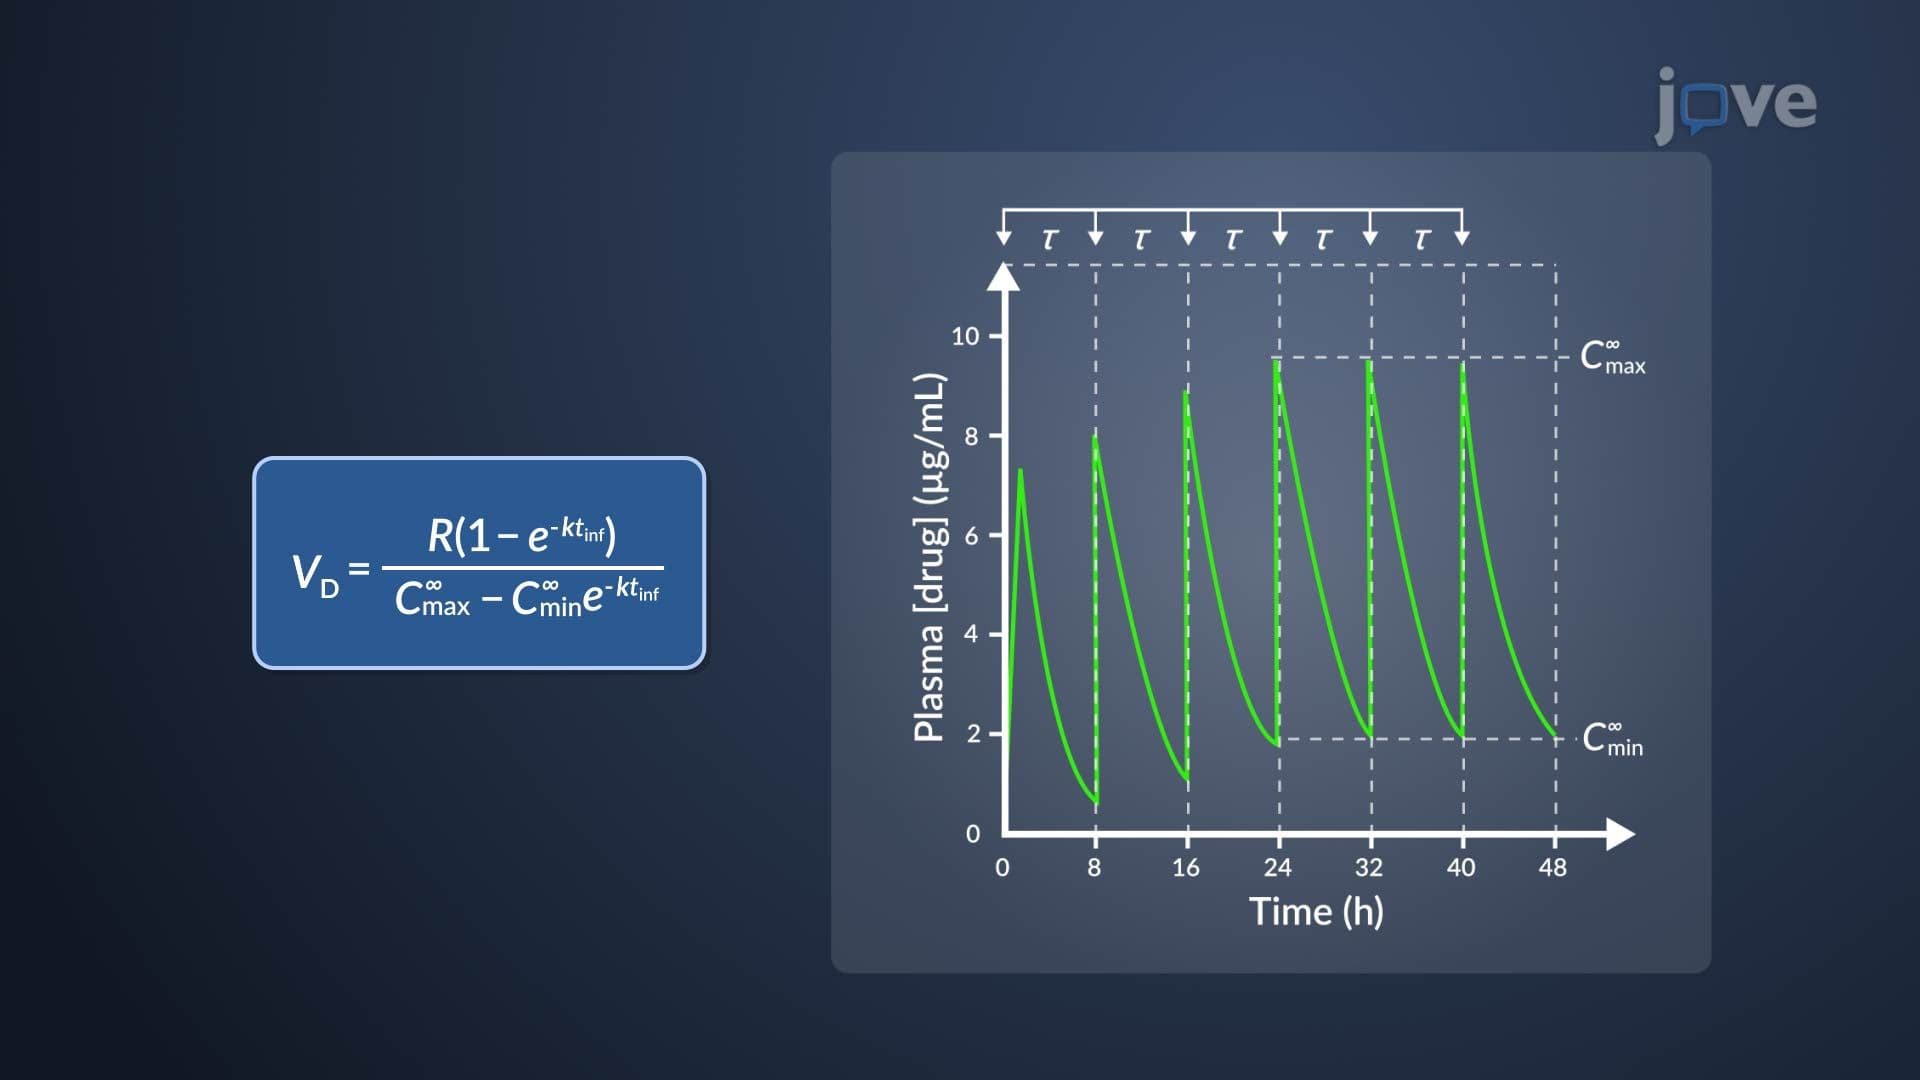
Estimation of k and VD of Aminoglycosides01:20

Estimation of k and VD of Aminoglycosides

Aminoglycosides are a class of antibiotics used to treat various bacterial infections. Clinicians must determine the elimination rate constant (k) and volume of distribution (VD) to optimize therapeutic efficacy and minimize toxicity. The k value represents the rate at which the drug is removed from the body, and the VD reflects the degree to which the drug distributes into body tissues. Accurately estimating these parameters allows healthcare professionals to tailor drug dosing to individual...
Sensitivity, Specificity, and Predicted Value01:13

Sensitivity, Specificity, and Predicted Value

In healthcare diagnostics, laboratory tests play a crucial role in identifying and diagnosing a wide range of medical conditions. However, interpreting test results is not always straightforward. An abnormal test result does not always confirm the presence of a disease, just as a normal result does not guarantee its absence. To assess the reliability of these diagnostic tools, healthcare practitioners rely on two key statistical indicators: sensitivity and specificity.
Sensitivity is the...
Statistical Significance01:37

Statistical Significance

Once data is collected from both the experimental and the control groups, a statistical analysis is conducted to find out if there are meaningful differences between the two groups. A statistical analysis determines how likely any difference found is due to chance (and thus not meaningful). In psychology, group differences are considered meaningful, or significant, if the odds that these differences occurred by chance alone are 5 percent or less. Stated another way, if we repeated this...
Expected Frequencies in Goodness-of-Fit Tests01:19

Expected Frequencies in Goodness-of-Fit Tests
A goodness-of-fit test is conducted to determine whether the observed frequency values are statistically similar to the frequencies expected for the dataset. Suppose the expected frequencies for a dataset are equal such as when predicting the frequency of any number appearing when casting a die. In that case, the expected frequency is the ratio of the total number of observations (n) to the number of categories (k).
Probability in Statistics01:14

Probability in Statistics

Probability is the likelihood of an event occurring. The term event is defined as a collection of results of a procedure. An event is a simple event when an outcome cannot be divided into simpler parts.
An example of a simple event is a coin toss. The result of a coin toss is either a head or a tail. Here, head and tail are two simple events. These two simple events make up the sample space. Further, the probability of an event occurring falls within the range of 0 to 1. The probability of an...
Accuracy and Errors in Hypothesis Testing01:13

Accuracy and Errors in Hypothesis Testing

Hypothesis testing is a fundamental statistical tool that begins with the assumption that the null hypothesis H0 is true. During this process, two types of errors can occur: Type I and Type II. A Type I error refers to the incorrect rejection of a true null hypothesis, while a Type II error involves the failure to reject a false null hypothesis.
In hypothesis testing, the probability of making a Type I error, denoted as α, is commonly set at 0.05. This significance level indicates a 5% chance...