Related Experiment Video
Updated: May 28, 2026

Lexical Decision Task for Studying Written Word Recognition in Adults with and without Dementia or Mild Cognitive Impairment
Published on: June 25, 2019
Determining the degree of randomness of descriptors in linear regression equations with respect to the data size
1Center for Bioinformatics, Campus Building E2.1, Saarland University, 66123 Saarbrücken, Germany. michael.hutter@bioinformatik.uni-saarland.de

Abstract:
Linear regression equations suffer from the curse of dimensionality that leads to overfitting and accidental correlation, particularly for small data sets and when many variables are present. This can lead to cases where descriptors based on random numbers exhibit higher correlations than actual descriptors. In this study, it was therefore investigated how high the degree of accidental correlation of a single descriptor can be with respect to the number of observations. On the basis of computer simulations for data sizes ranging from 7 to 500 observations, a formula was derived that expresses the degree of randomness (in percent) of a chosen descriptor depending on its correlation coefficient and the size of the data set. This allows one to determine a cutoff for the correlation below which descriptors can be discarded due to a high risk of chance correlation. Doing so, the number of eligible variables for the regression analysis can be reduced substantially. Corresponding applications are reported for several QSAR data sets of various sizes.
Related Concept Videos
 01:19
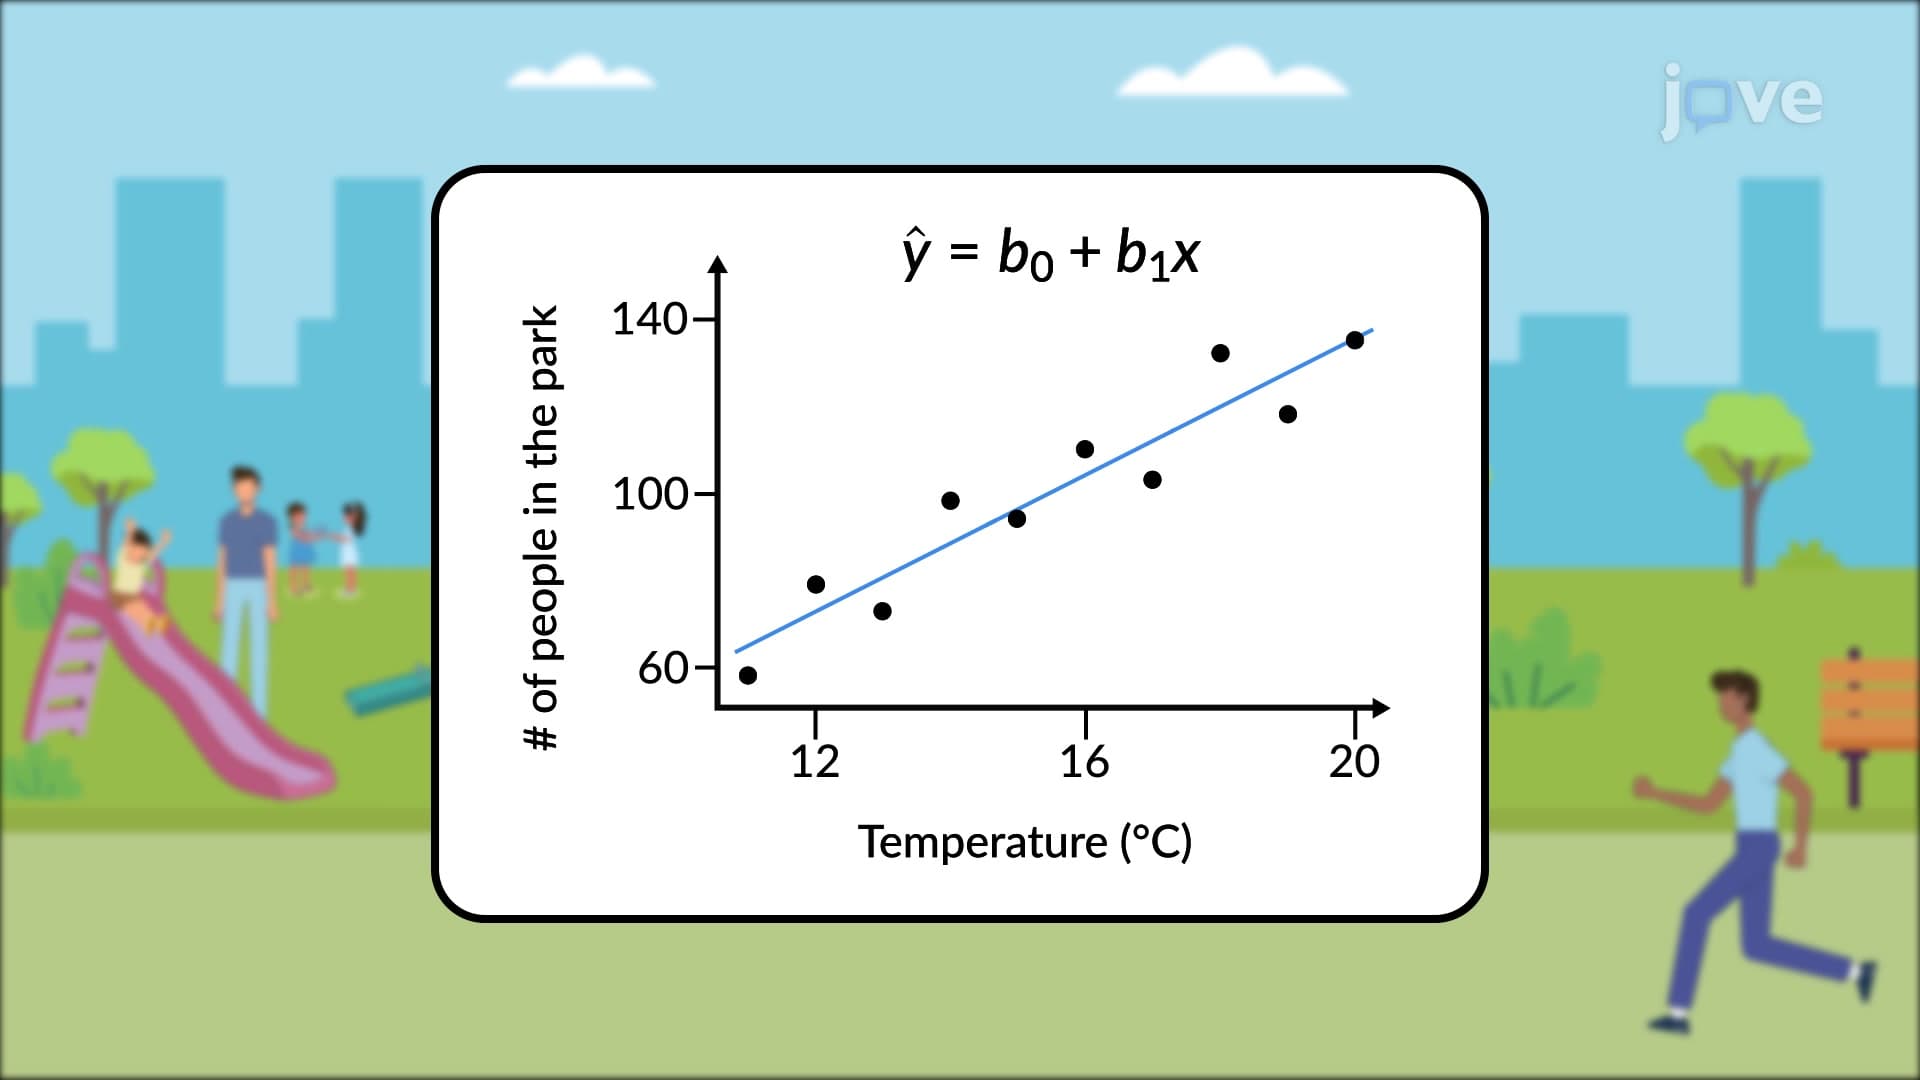
Variation
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
 01:02
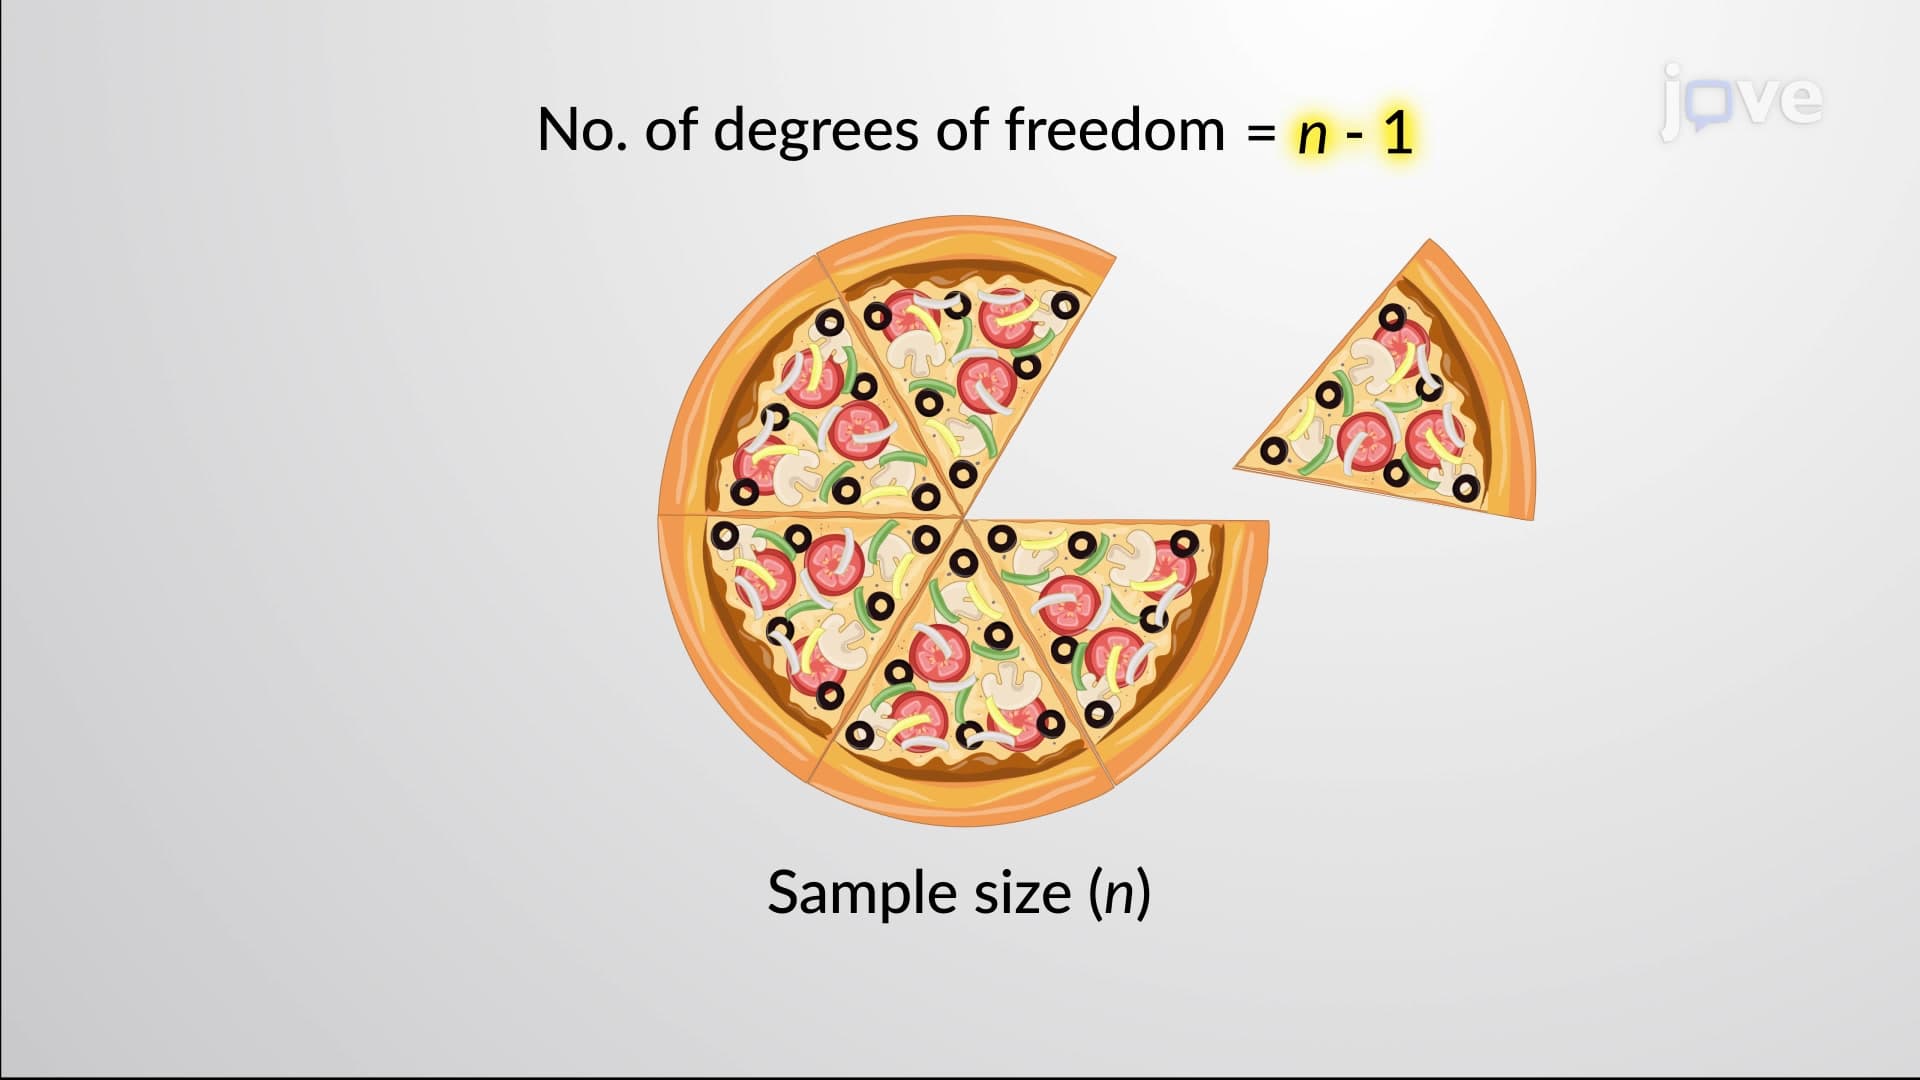
Degrees of Freedom
For example, suppose there are three unknown numbers whose mean is 10; although we can freely assign values to the first and second numbers, the value of the last number can not be arbitrarily assigned.
 01:02
Degrees of Freedom
For example, suppose there are three unknown numbers whose mean is 10; although we can freely assign values to the first and second numbers, the value of the last number can not be arbitrarily...
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:25
Multiple Regression
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
 01:04
Random Error