Random KNN feature selection - a fast and stable alternative to Random Forests
Related Experiment Video
Updated: May 27, 2026

Selecting Multiple Biomarker Subsets with Similarly Effective Binary Classification Performances
Published on: October 11, 2018
Shengqiao Li1, E James Harner, Donald A Adjeroh
1The Department of Statistics, West Virginia University, Morgantown, WV 26506, USA.

Background:
Successfully modeling high-dimensional data involving thousands of variables is challenging. This is especially true for gene expression profiling experiments, given the large number of genes involved and the small number of samples available. Random Forests (RF) is a popular and widely used approach to feature selection for such "small n, large p problems." However, Random Forests suffers from instability, especially in the presence of noisy and/or unbalanced inputs.
Results:
We present RKNN-FS, an innovative feature selection procedure for "small n, large p problems." RKNN-FS is based on Random KNN (RKNN), a novel generalization of traditional nearest-neighbor modeling. RKNN consists of an ensemble of base k-nearest neighbor models, each constructed from a random subset of the input variables. To rank the importance of the variables, we define a criterion on the RKNN framework, using the notion of support. A two-stage backward model selection method is then developed based on this criterion. Empirical results on microarray data sets with thousands of variables and relatively few samples show that RKNN-FS is an effective feature selection approach for high-dimensional data. RKNN is similar to Random Forests in terms of classification accuracy without feature selection. However, RKNN provides much better classification accuracy than RF when each method incorporates a feature-selection step. Our results show that RKNN is significantly more stable and more robust than Random Forests for feature selection when the input data are noisy and/or unbalanced. Further, RKNN-FS is much faster than the Random Forests feature selection method (RF-FS), especially for large scale problems, involving thousands of variables and multiple classes.
Conclusions:
Given the superiority of Random KNN in classification performance when compared with Random Forests, RKNN-FS's simplicity and ease of implementation, and its superiority in speed and stability, we propose RKNN-FS as a faster and more stable alternative to Random Forests in classification problems involving feature selection for high-dimensional datasets.

Related Concept Videos
 01:13
Randomized Experiments
Simple randomization
Simple...
 01:09
Random Sampling Method
 01:19
Survival Tree
Building a Survival Tree
Constructing a survival tree begins...
 01:17
Wald-Wolfowitz Runs Test I
The test works...
 01:09
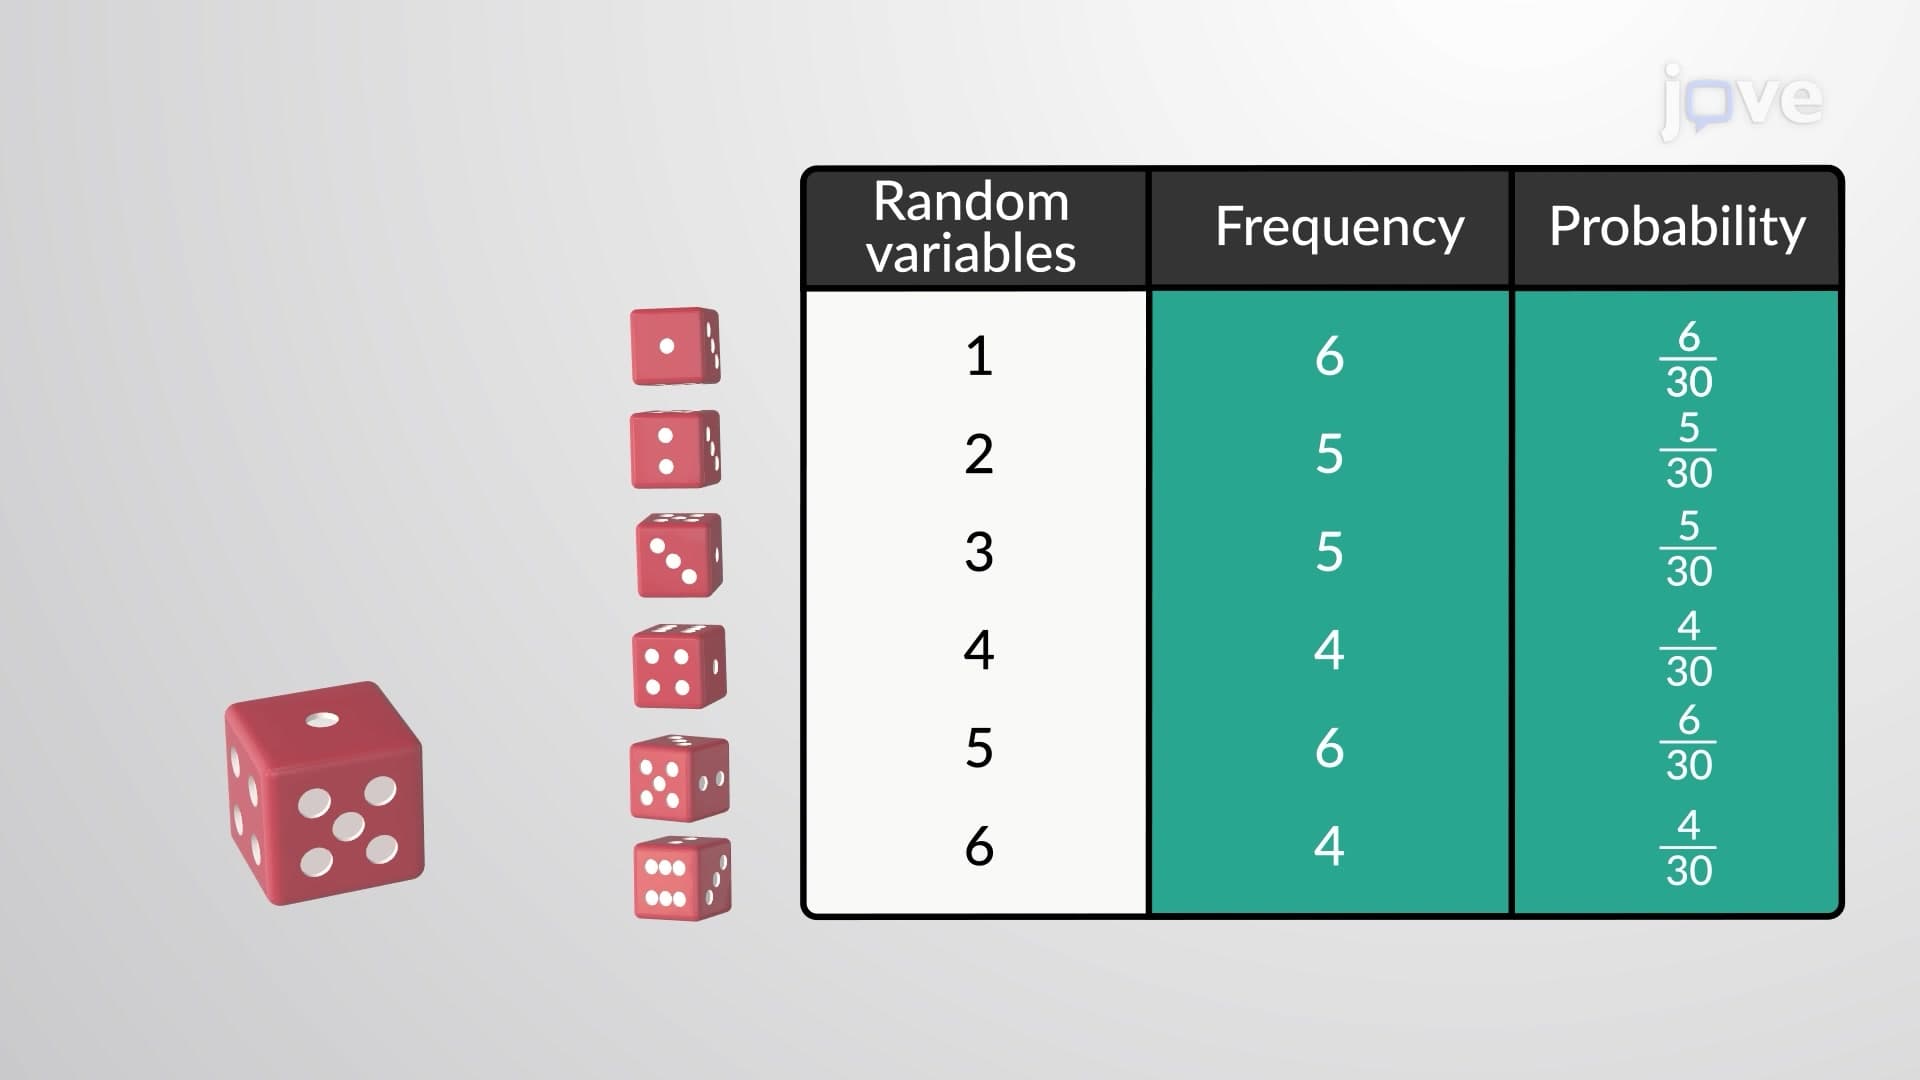
Random Variables
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
 01:17
Wald-Wolfowitz Runs Test II
For binary data, runs are identified using symbols such as + and −, or equivalently, 1s and 0s. In...