Related Experiment Video
Updated: May 23, 2026
A Novel Bayesian Change-point Algorithm for Genome-wide Analysis of Diverse ChIPseq Data Types
Published on: December 10, 2012
Supervised Bayesian latent class models for high-dimensional data
Stacia M Desantis1, E Andrés Houseman, Brent A Coull
1Division of Biostatistics and Epidemiology, Department of Medicine, Medical University of South Carolina, Charleston, SC 29425, USA. desantis@musc.edu

Abstract:
High-grade gliomas are the most common primary brain tumors in adults and are typically diagnosed using histopathology. However, these diagnostic categories are highly heterogeneous and do not always correlate well with survival. In an attempt to refine these diagnoses, we make several immunohistochemical measurements of YKL-40, a gene previously shown to be differentially expressed between diagnostic groups. We propose two latent class models for classification and variable selection in the presence of high-dimensional binary data, fit by using Bayesian Markov chain Monte Carlo techniques. Penalization and model selection are incorporated in this setting via prior distributions on the unknown parameters. The methods provide valid parameter estimates under conditions in which standard supervised latent class models do not, and outperform two-stage approaches to variable selection and parameter estimation in a variety of settings. We study the properties of these methods in simulations, and apply these methodologies to the glioma study for which identifiable three-class parameter estimates cannot be obtained without penalization. With penalization, the resulting latent classes correlate well with clinical tumor grade and offer additional information on survival prognosis that is not captured by clinical diagnosis alone. The inclusion of YKL-40 features also increases the precision of survival estimates. Fitting models with and without YKL-40 highlights a subgroup of patients who have glioblastoma (GBM) diagnosis but appear to have better prognosis than the typical GBM patient.
Related Concept Videos
 01:06
Model Approaches for Pharmacokinetic Data: Distributed Parameter Models
The distributed parameter models are specifically designed to account for variations and differences in some drug classes. This model is particularly useful for assessing regional concentrations of anticancer or...
 01:14
Model Approaches for Pharmacokinetic Data: Compartment Models
Two primary types of compartment models are recognized: mammillary and catenary. The more...
 01:14
Multicompartment Models: Overview
These models offer a more comprehensive representation of drug behavior in the body than one-compartment models. They accommodate the complexity of drug distribution,...
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance, comparing...
 01:17
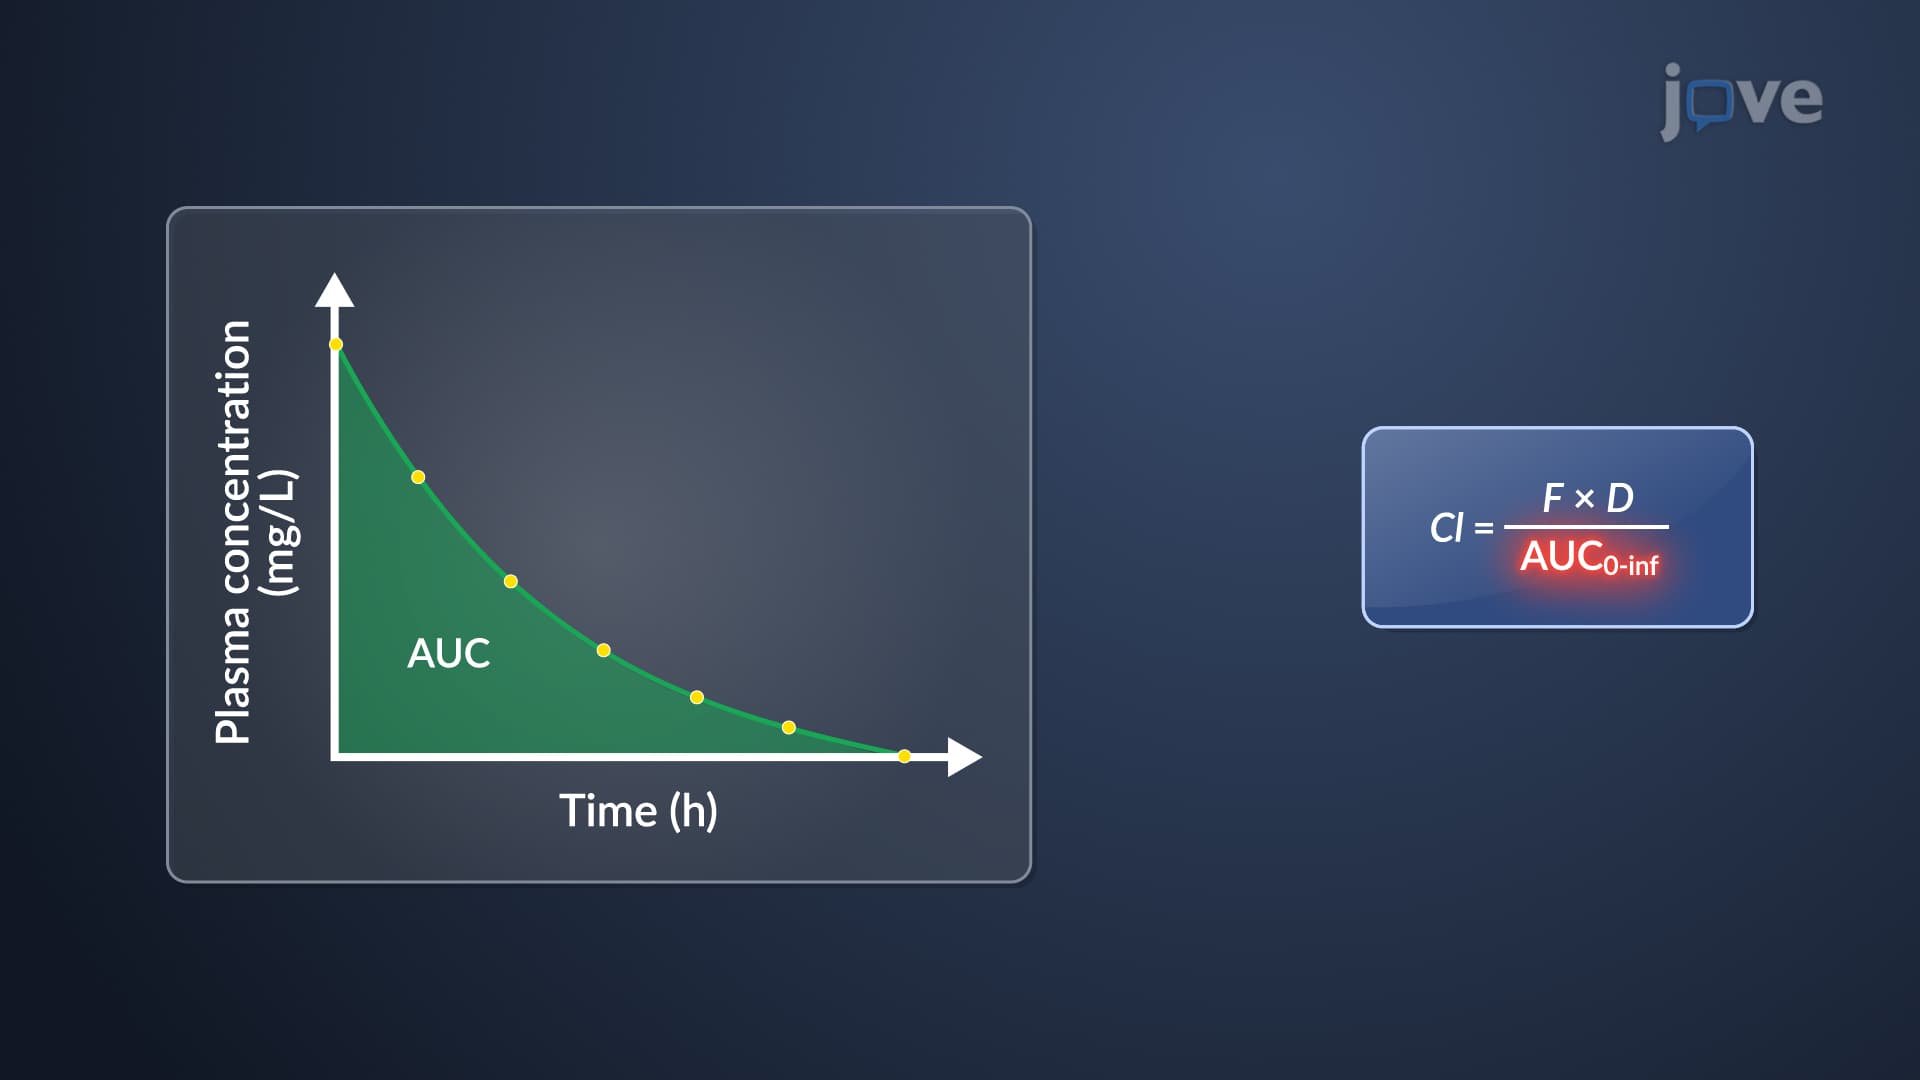
Clearance Models: Noncompartmental Models
The noncompartmental approach capitalizes on extensive sampling data, correlating the volume of distribution to systemic exposure and the administered dosage. This method enables...
 01:17
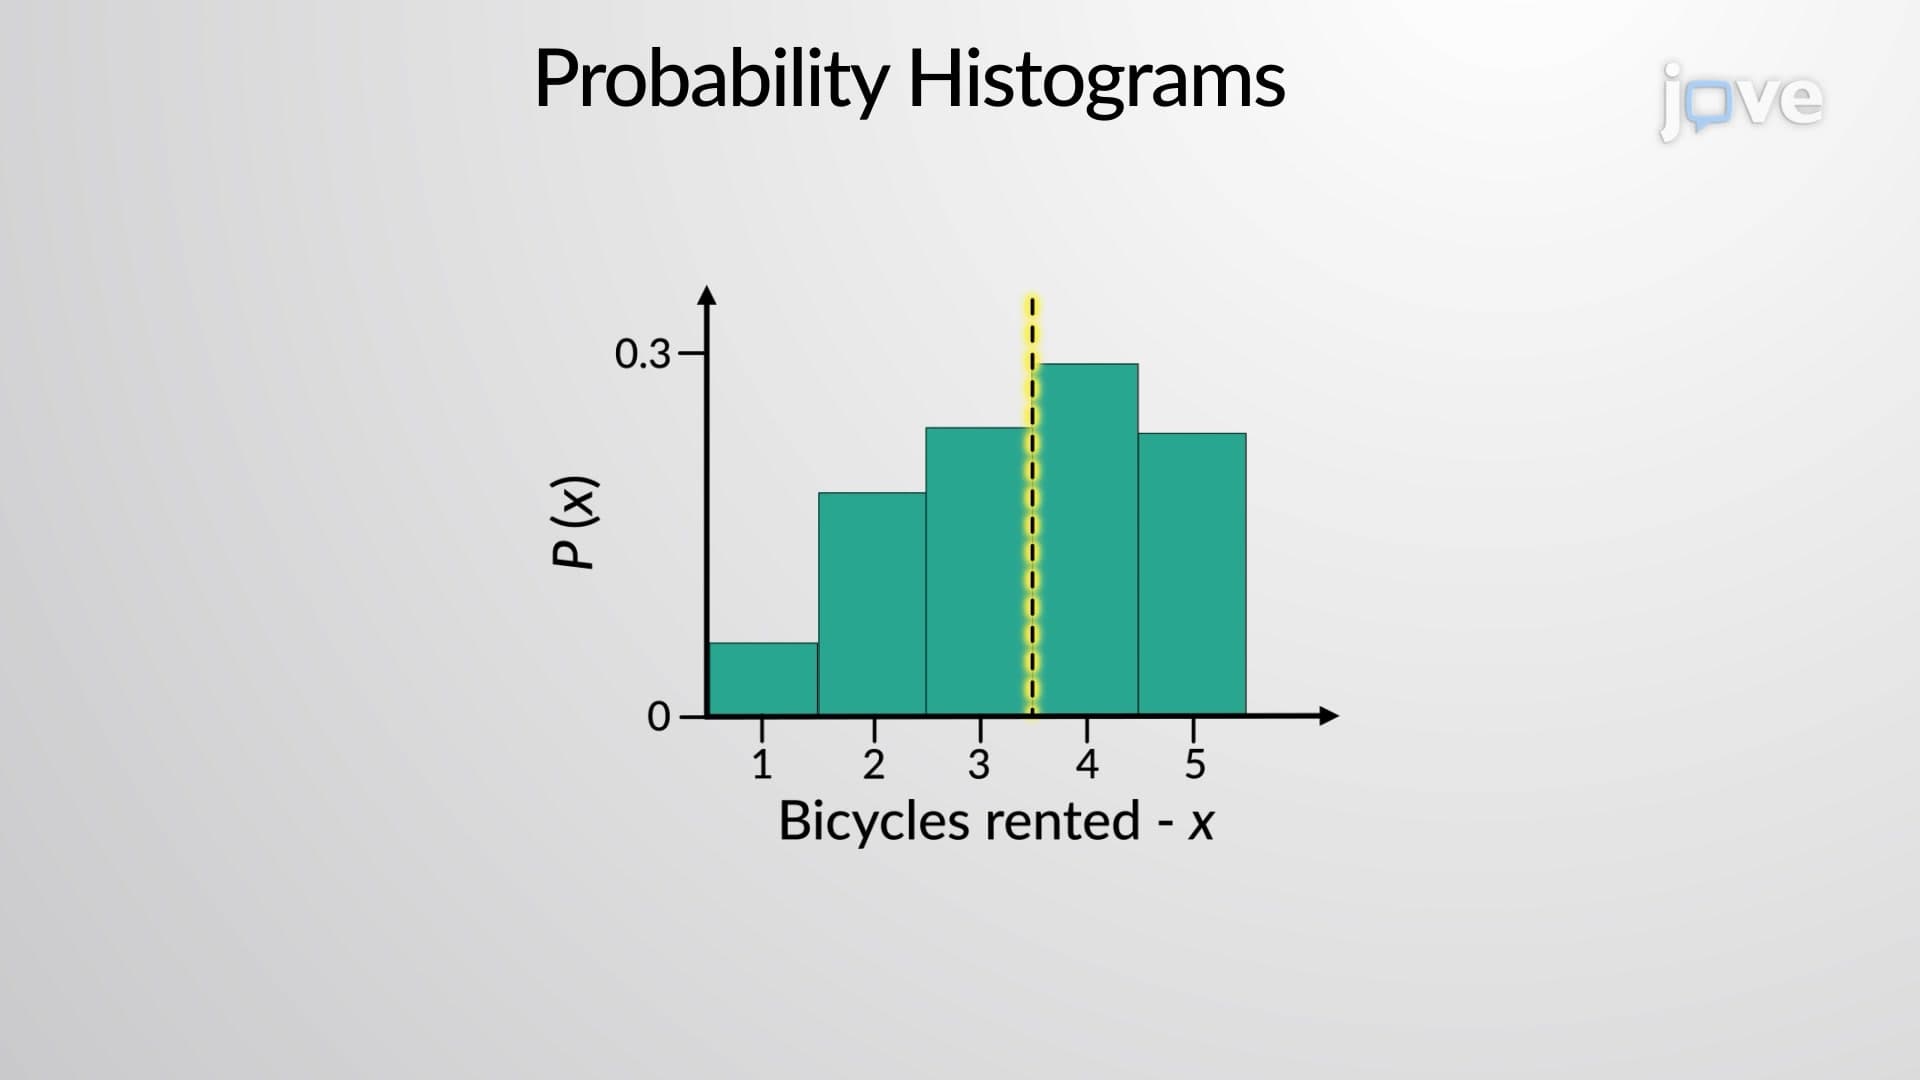
Probability Histograms