Related Experiment Video
Updated: May 22, 2026

Drug Repurposing Hypothesis Generation Using the "RE:fine Drugs" System
Published on: December 11, 2016
Relation mining experiments in the pharmacogenomics domain
Fabio Rinaldi1, Gerold Schneider, Simon Clematide
1Institute of Computational Linguistics, University of Zurich, Binzmühlestrasse 14, 8050 Zürich, Switzerland. fabio.rinaldi@uzh.ch

Abstract:
The mutual interactions among genes, diseases, and drugs are at the heart of biomedical research, and are especially important for the pharmacological industry. The recent trend towards personalized medicine makes it increasingly relevant to be able to tailor drugs to specific genetic makeups. The pharmacogenetics and pharmacogenomics knowledge base (PharmGKB) aims at capturing relevant information about such interactions from several sources, including curation of the biomedical literature. Advanced text mining tools which can support the process of manual curation are increasingly necessary in order to cope with the deluge of new published results. However, effective evaluation of those tools requires the availability of manually curated data as gold standard. In this paper we discuss how the existing PharmGKB database can be used for such an evaluation task in a way similar to the usage of gold standard data derived from protein-protein interaction databases in one of the recent BioCreative shared tasks. Additionally, we present our own considerations and results on the feasibility and difficulty of such a task.
Related Concept Videos
 01:29
Pharmacogenomics: Identification of New Drug Targets
 01:29
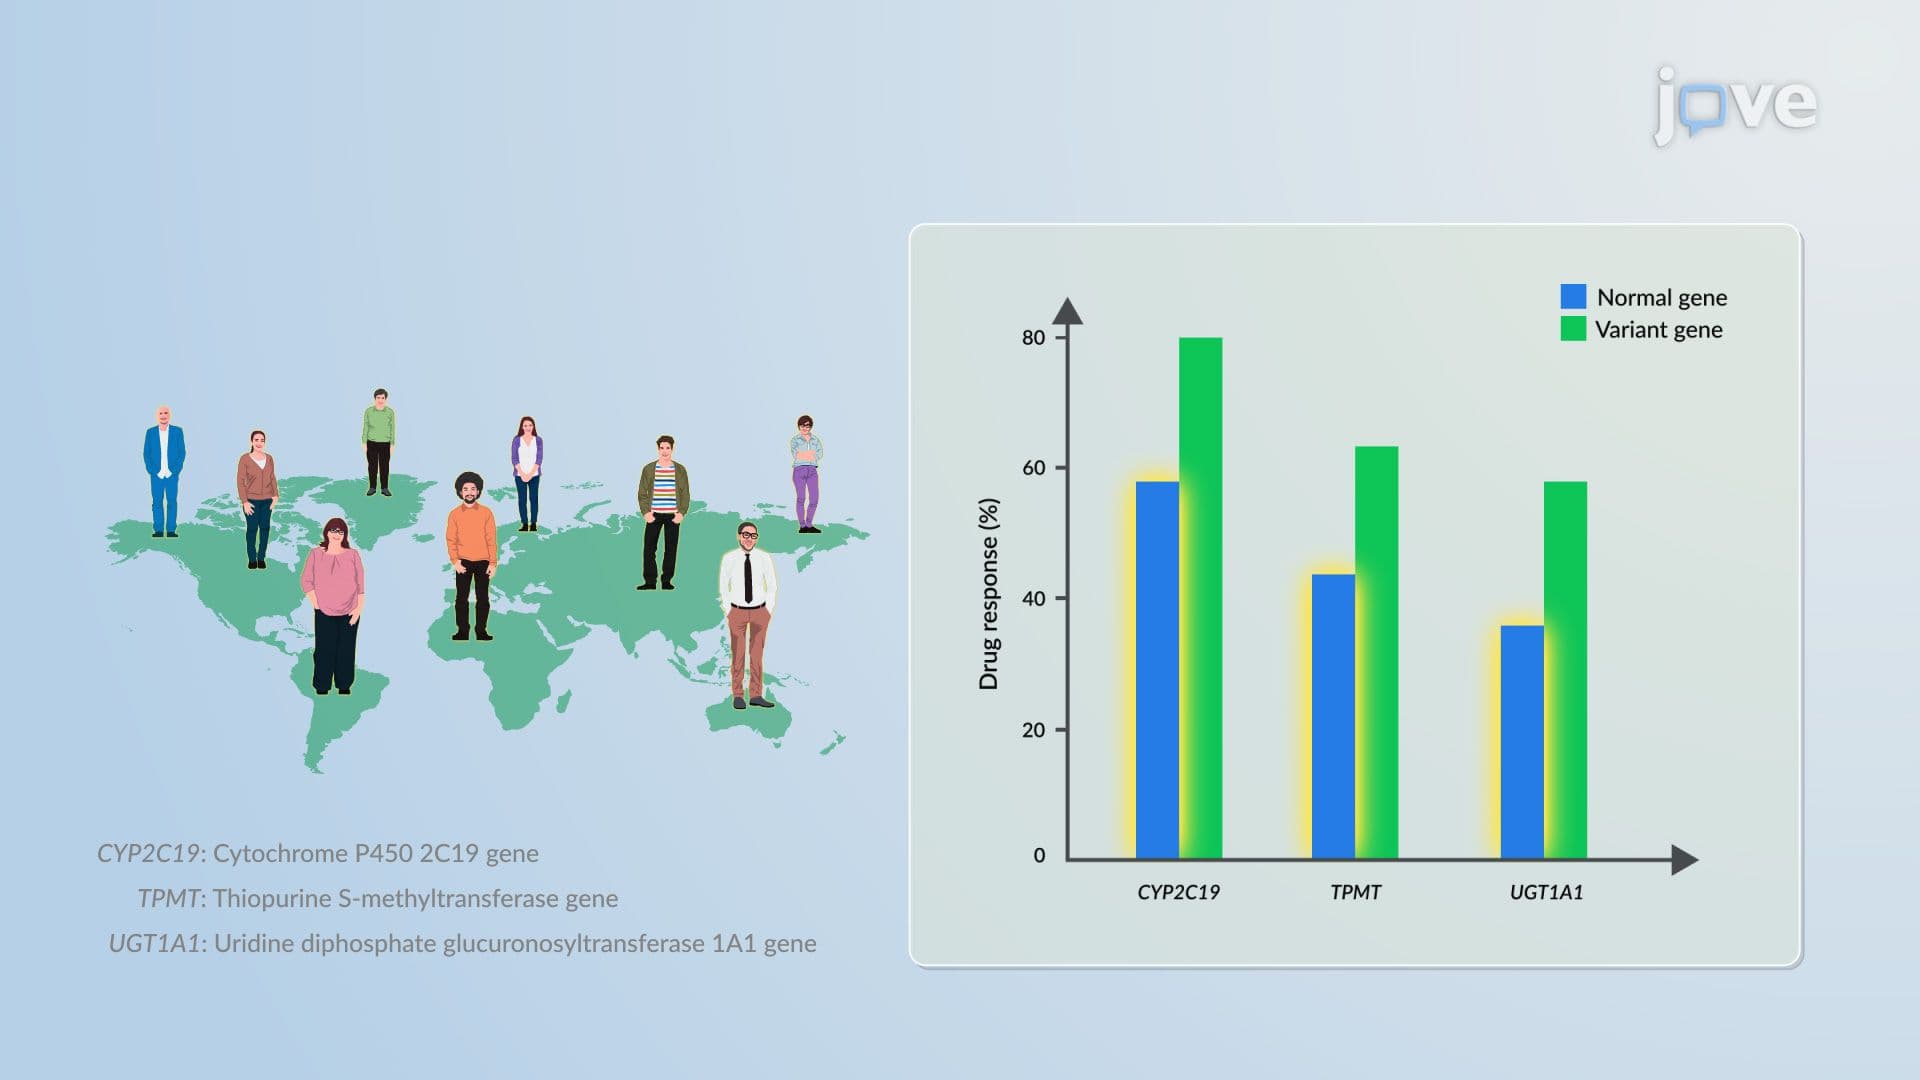
Pharmacogenetics and Pharmacogenomics: Overview
 01:27
Pharmacogenetics of Drug Metabolism: Overview
 01:27
Principles of Pharmacogenetics: Types of Genetic Variants
 01:29
Pharmacogenetic Phenotypes: Alterations in Pharmacokinetics, Drug Targets and Biologic Milieu
 01:12
Analysis of Population Pharmacokinetic Data