Related Experiment Video
Updated: May 22, 2026

A Practical Guide to Phylogenetics for Nonexperts
Published on: February 5, 2014
Computing posterior probabilities for score-based alignments using ppALIGN
Stefan Wolfsheimer1, Alexander Hartmann, Ralf Rabus
1Department of Applied Mathematics (MAP5), University of Paris Descartes, France.

Abstract:
Score-based pairwise alignments are widely used in bioinformatics in particular with molecular database search tools, such as the BLAST family. Due to sophisticated heuristics, such algorithms are usually fast but the underlying scoring model unfortunately lacks a statistical description of the reliability of the reported alignments. In particular, close to gaps, in low-score or low-complexity regions, a huge number of alternative alignments arise which results in a decrease of the certainty of the alignment. ppALIGN is a software package that uses hidden Markov Model techniques to compute position-wise reliability of score-based pairwise alignments of DNA or protein sequences. The design of the model allows for a direct connection between the scoring function and the parameters of the probabilistic model. For this reason it is suitable to analyze the outcomes of popular score based aligners and search tools without having to choose a complicated set of parameters. By contrast, our program only requires the classical score parameters (the scoring function and gap costs). The package comes along with a library written in C++, a standalone program for user defined alignments (ppALIGN) and another program (ppBLAST) which can process a complete result set of BLAST. The main algorithms essentially exhibit a linear time complexity (in the alignment lengths), and they are hence suitable for on-line computations. We have also included alternative decoding algorithms to provide alternative alignments. ppALIGN is a fast program/library that helps detect and quantify questionable regions in pairwise alignments. Due to its structure, the input/output interface it can to be connected to other post-processing tools. Empirically, we illustrate its usefulness in terms of correctly predicted reliable regions for sequences generated using the ROSE model for sequence evolution, and identify sensor-specific regions in the denitrifying betaproteobacterium Aromatoleum aromaticum.

Related Concept Videos
 01:24
Testing a Claim about Population Proportion
There are two methods of testing a claim about a population proportion: (1) Using the sample proportion from the data where a binomial distribution is approximated to the normal distribution and (2) Using the binomial probabilities calculated from the data.
The first method uses normal distribution as an approximation to the binomial distribution. The requirements are as follows: sample size is large...
 01:09
Wilcoxon Signed-Ranks Test for Matched Pairs
 01:09
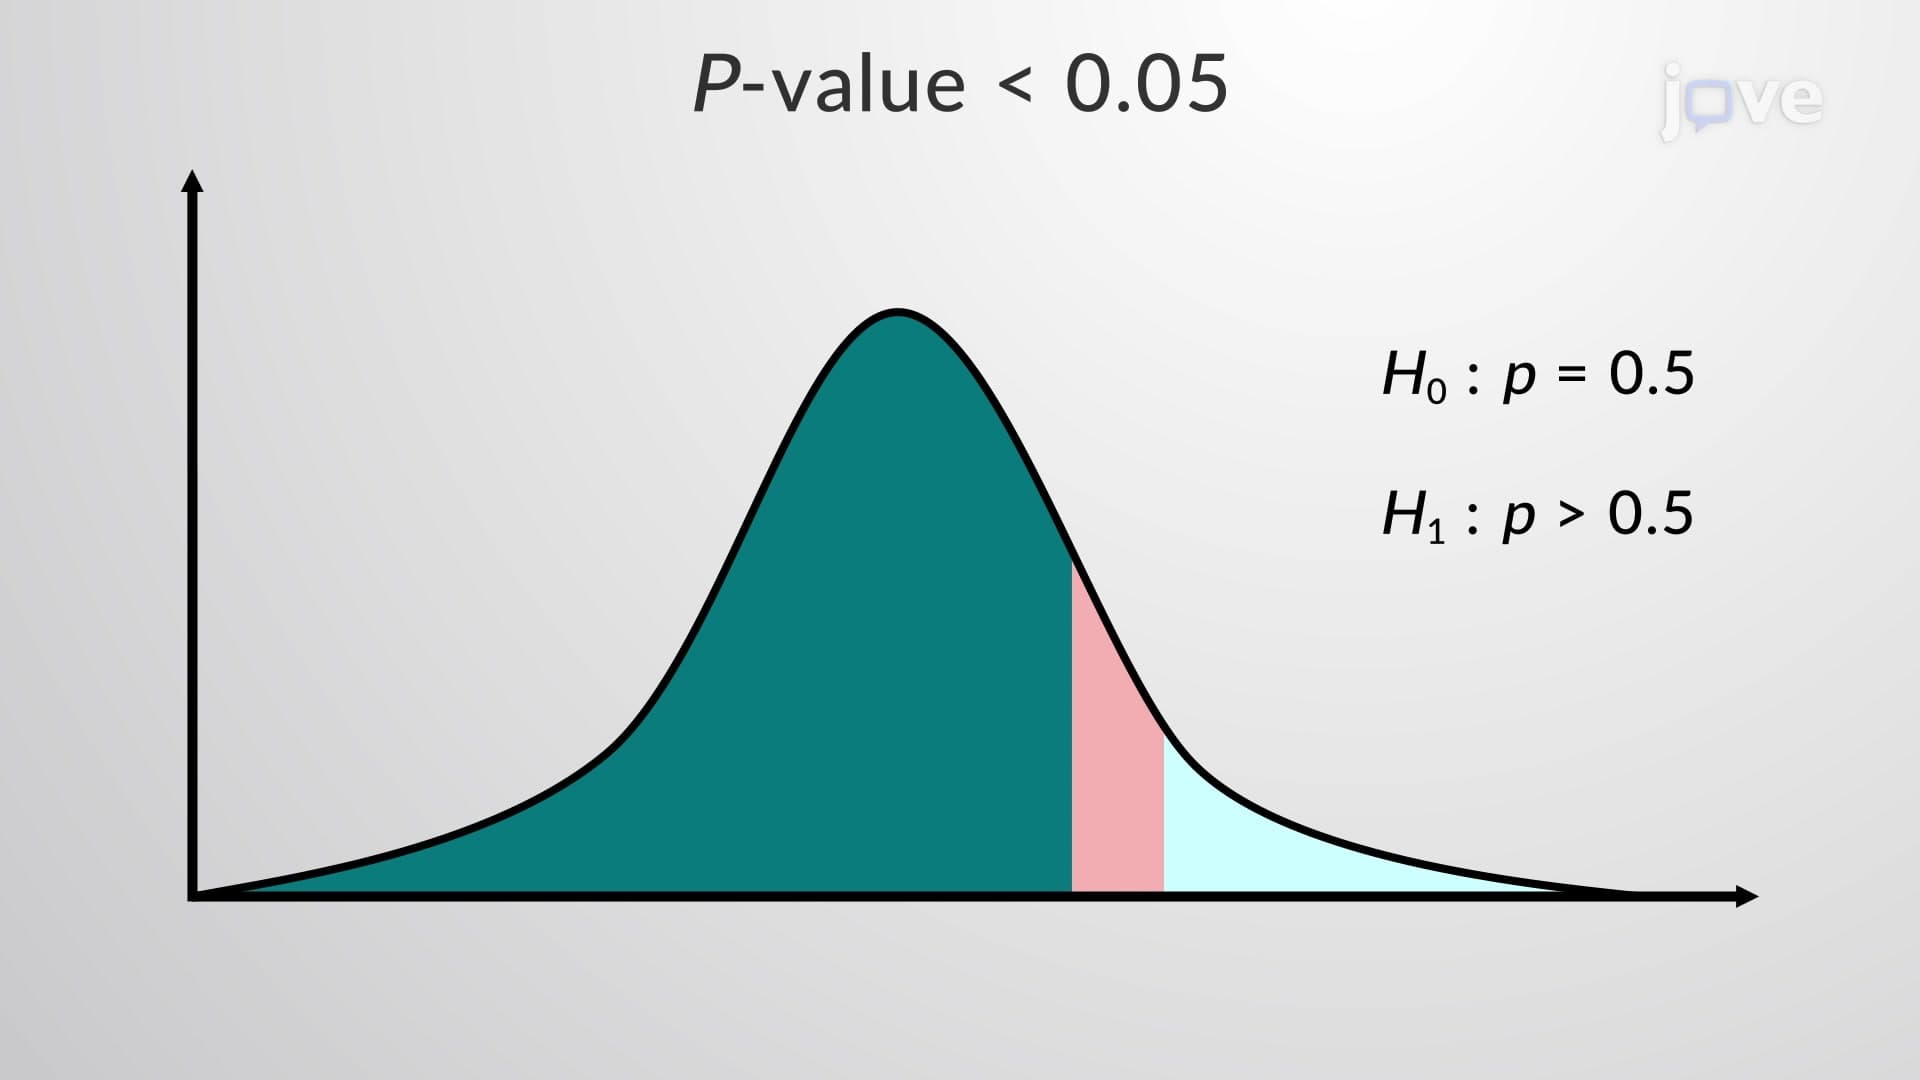
Decision Making: P-value Method
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can have a...
 01:10
P-value
P-value stands for the probability value. P-value is the probability that, if the null hypothesis is true, the results from another randomly selected sample will be as extreme or more extreme as the results obtained from the given sample.
A large P-value calculated from the data indicates to not reject the null hypothesis. But a higher P-value does not mean that the null hypothesis is true. The smaller the P-value, the more unlikely...
 01:20
Kendall's Coefficient of Concordance
 01:19
Expected Frequencies in Goodness-of-Fit Tests