Related Experiment Video
Updated: May 21, 2026
Generating the Transcriptional Regulation View of Transcriptomic Features for Prediction Task and Dark Biomarker Detection on Small Datasets
Published on: March 1, 2024
Learning word sense disambiguation in biomedical text with difference between training and test distributions
Jeong-Woo Son1, Seong-Bae Park
1Department of Computer Engineering, Kyungpook National University, Daegu 702-701, Korea. jwson@sejong.knu.ac.kr

Abstract:
Word Sense Disambiguation methods based on machine learning techniques with lexical features suffer from the discordance between distributions of the training and test documents, due to the diversity of lexical space. To tackle this problem, this paper proposes Support Vector Machines with Example-wise Weights. In this method, the training distribution is matched with the test distribution by weighting training examples according to their similarity to all test data. The experimental results show the distribution change between the training and test data is actually recognised and the proposed method which considers this change in its training phase outperforms ordinary SVMs.
Related Concept Videos
 01:19
Data: Types and Distribution
Distributions in...
 01:16
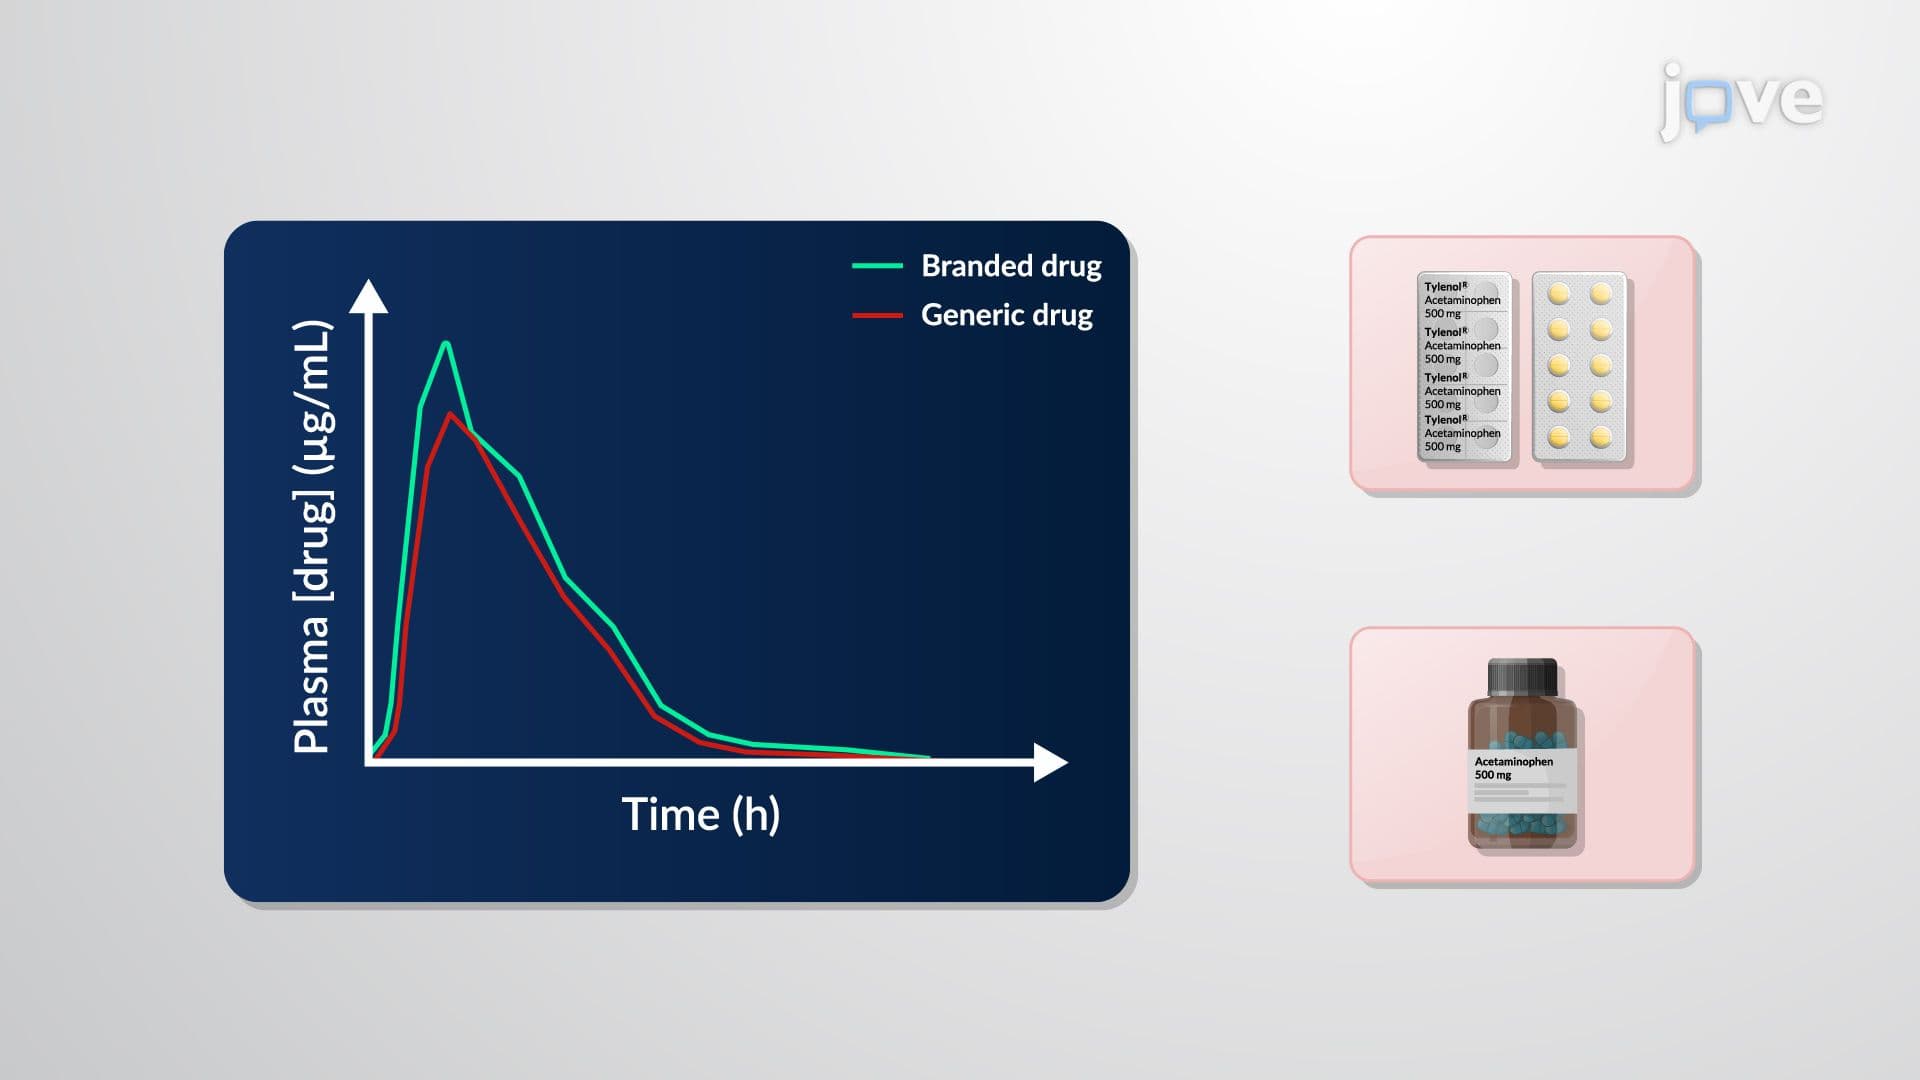
Bioequivalence Data: Statistical Interpretation
 01:17
Sign Test for Matched Pairs
To conduct the sign test, we first calculate the differences in value between...
 01:09
Comparing Experimental Results: Student's t-Test
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance, comparing...
 00:57
Behrens–Fisher Test
This test is...