A new estimator of the discovery probability
Related Experiment Video
Updated: May 18, 2026
A Tactile Automated Passive-Finger Stimulator (TAPS)
Published on: June 3, 2009
Stefano Favaro1, Antonio Lijoi, Igor Prünster
1Department of Economics and Statistics, University of Torino, Torino, Italy.

Abstract:
Species sampling problems have a long history in ecological and biological studies and a number of issues, including the evaluation of species richness, the design of sampling experiments, and the estimation of rare species variety, are to be addressed. Such inferential problems have recently emerged also in genomic applications, however, exhibiting some peculiar features that make them more challenging: specifically, one has to deal with very large populations (genomic libraries) containing a huge number of distinct species (genes) and only a small portion of the library has been sampled (sequenced). These aspects motivate the Bayesian nonparametric approach we undertake, since it allows to achieve the degree of flexibility typically needed in this framework. Based on an observed sample of size n, focus will be on prediction of a key aspect of the outcome from an additional sample of size m, namely, the so-called discovery probability. In particular, conditionally on an observed basic sample of size n, we derive a novel estimator of the probability of detecting, at the (n+m+1)th observation, species that have been observed with any given frequency in the enlarged sample of size n+m. Such an estimator admits a closed-form expression that can be exactly evaluated. The result we obtain allows us to quantify both the rate at which rare species are detected and the achieved sample coverage of abundant species, as m increases. Natural applications are represented by the estimation of the probability of discovering rare genes within genomic libraries and the results are illustrated by means of two expressed sequence tags datasets.


Related Concept Videos
 01:06
What are Estimates?
The estimate for the mean of a sample is denoted by ͞x, whereas the mean of the population is designated as μ. Further, parameters such as the mean,...
 01:24
Testing a Claim about Population Proportion
There are two methods of testing a claim about a population proportion: (1) Using the sample proportion from the data where a binomial distribution is approximated to the normal distribution and (2) Using the binomial probabilities calculated from the data.
The first method uses normal distribution as an approximation to the binomial distribution. The requirements are as follows: sample size is large...
 01:24
Kaplan-Meier Approach
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
The...
 01:10
P-value
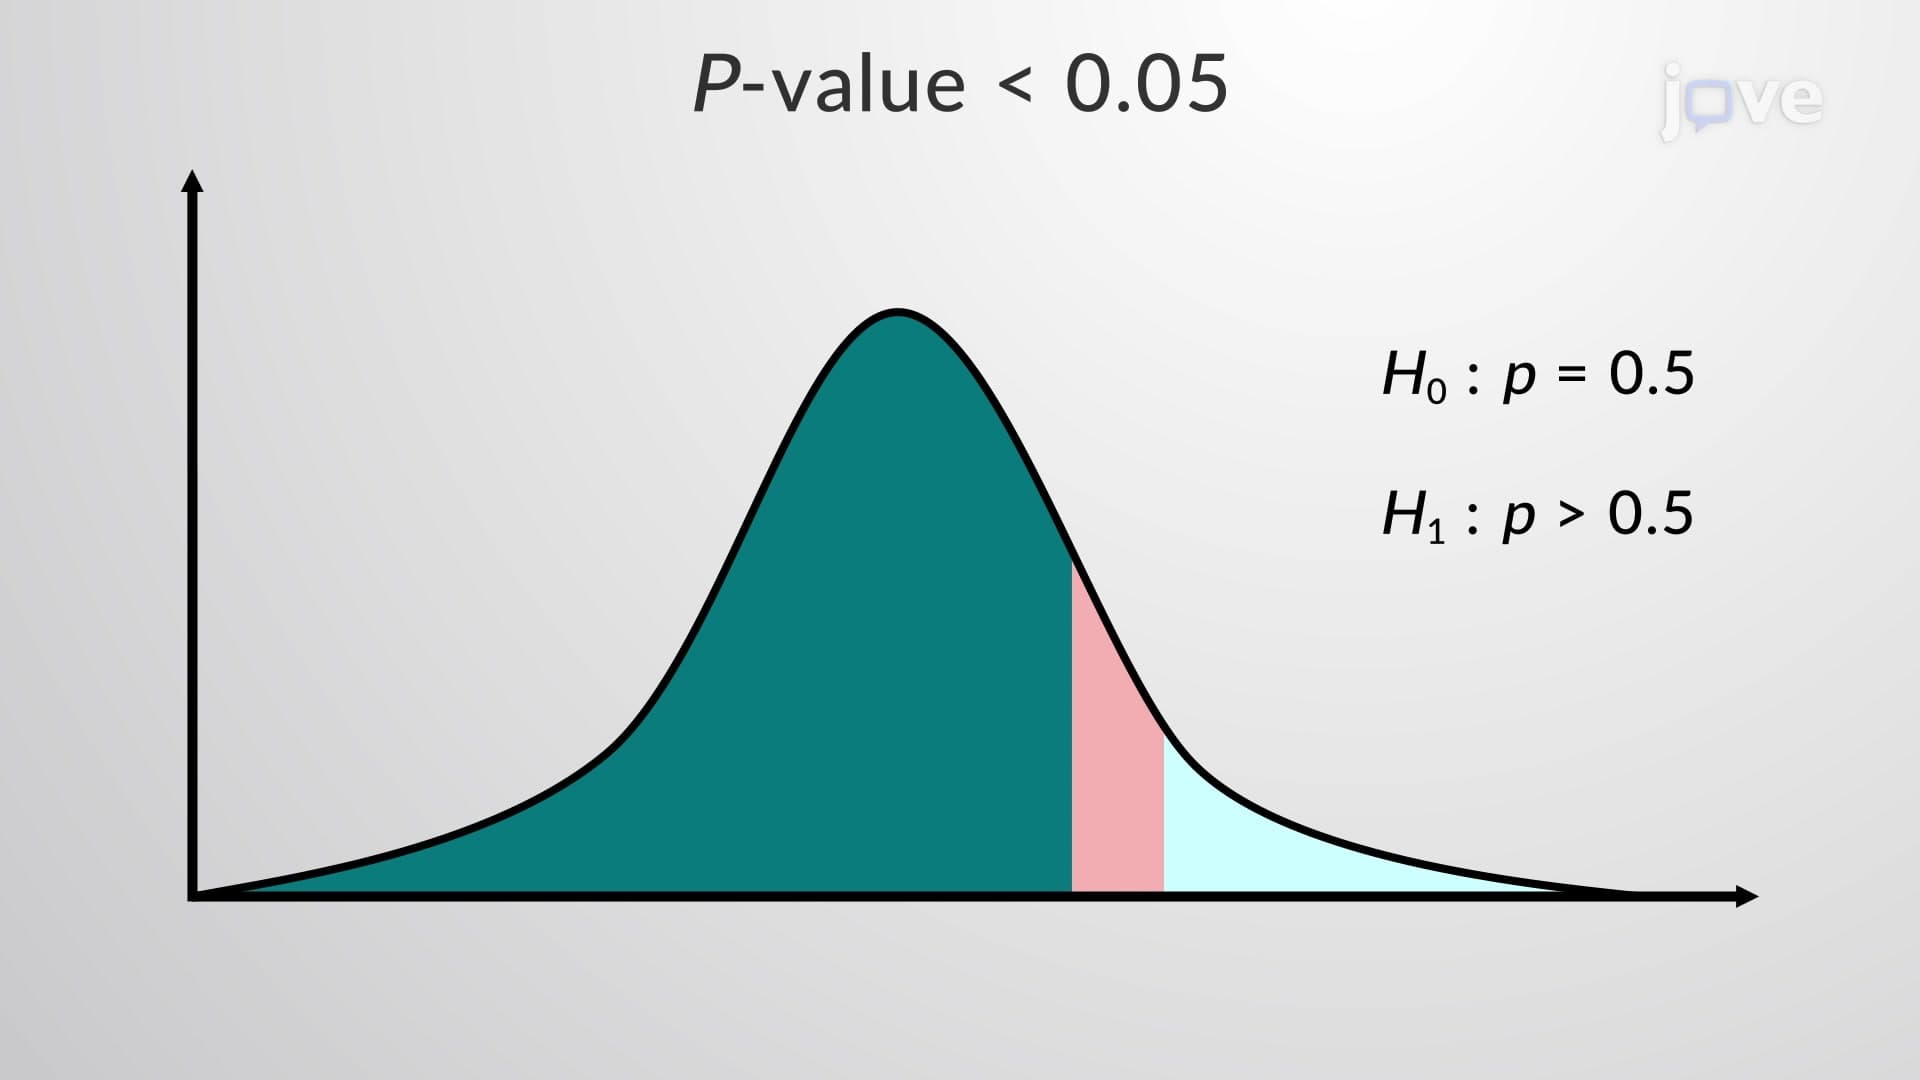
P-value stands for the probability value. P-value is the probability that, if the null hypothesis is true, the results from another randomly selected sample will be as extreme or more extreme as the results obtained from the given sample.
A large P-value calculated from the data indicates to not reject the null hypothesis. But a higher P-value does not mean that the null hypothesis is true. The smaller the P-value, the more unlikely...
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
On...