Related Experiment Video
Updated: May 15, 2026


Development of an Individual-Tree Basal Area Increment Model using a Linear Mixed-Effects Approach
Published on: July 3, 2020
The effect of skewness and kurtosis on the robustness of linear mixed models
Jaume Arnau1, Rebecca Bendayan, María J Blanca
1Department of Methodology of the Behavioral Sciences, University of Barcelona, Barcelona, Spain.

Abstract:
This study analyzes the robustness of the linear mixed model (LMM) with the Kenward-Roger (KR) procedure to violations of normality and sphericity when used in split-plot designs with small sample sizes. Specifically, it explores the independent effect of skewness and kurtosis on KR robustness for the values of skewness and kurtosis coefficients that are most frequently found in psychological and educational research data. To this end, a Monte Carlo simulation study was designed, considering a split-plot design with three levels of the between-subjects grouping factor and four levels of the within-subjects factor. Robustness is assessed in terms of the probability of type I error. The results showed that (1) the robustness of the KR procedure does not differ as a function of the violation or satisfaction of the sphericity assumption when small samples are used; (2) the LMM with KR can be a good option for analyzing total sample sizes of 45 or larger when their distributions are normal, slightly or moderately skewed, and with different degrees of kurtosis violation; (3) the effect of skewness on the robustness of the LMM with KR is greater than the corresponding effect of kurtosis for common values; and (4) when data are not normal and the total sample size is 30, the procedure is not robust. Alternative analyses should be performed when the total sample size is 30.
Related Concept Videos
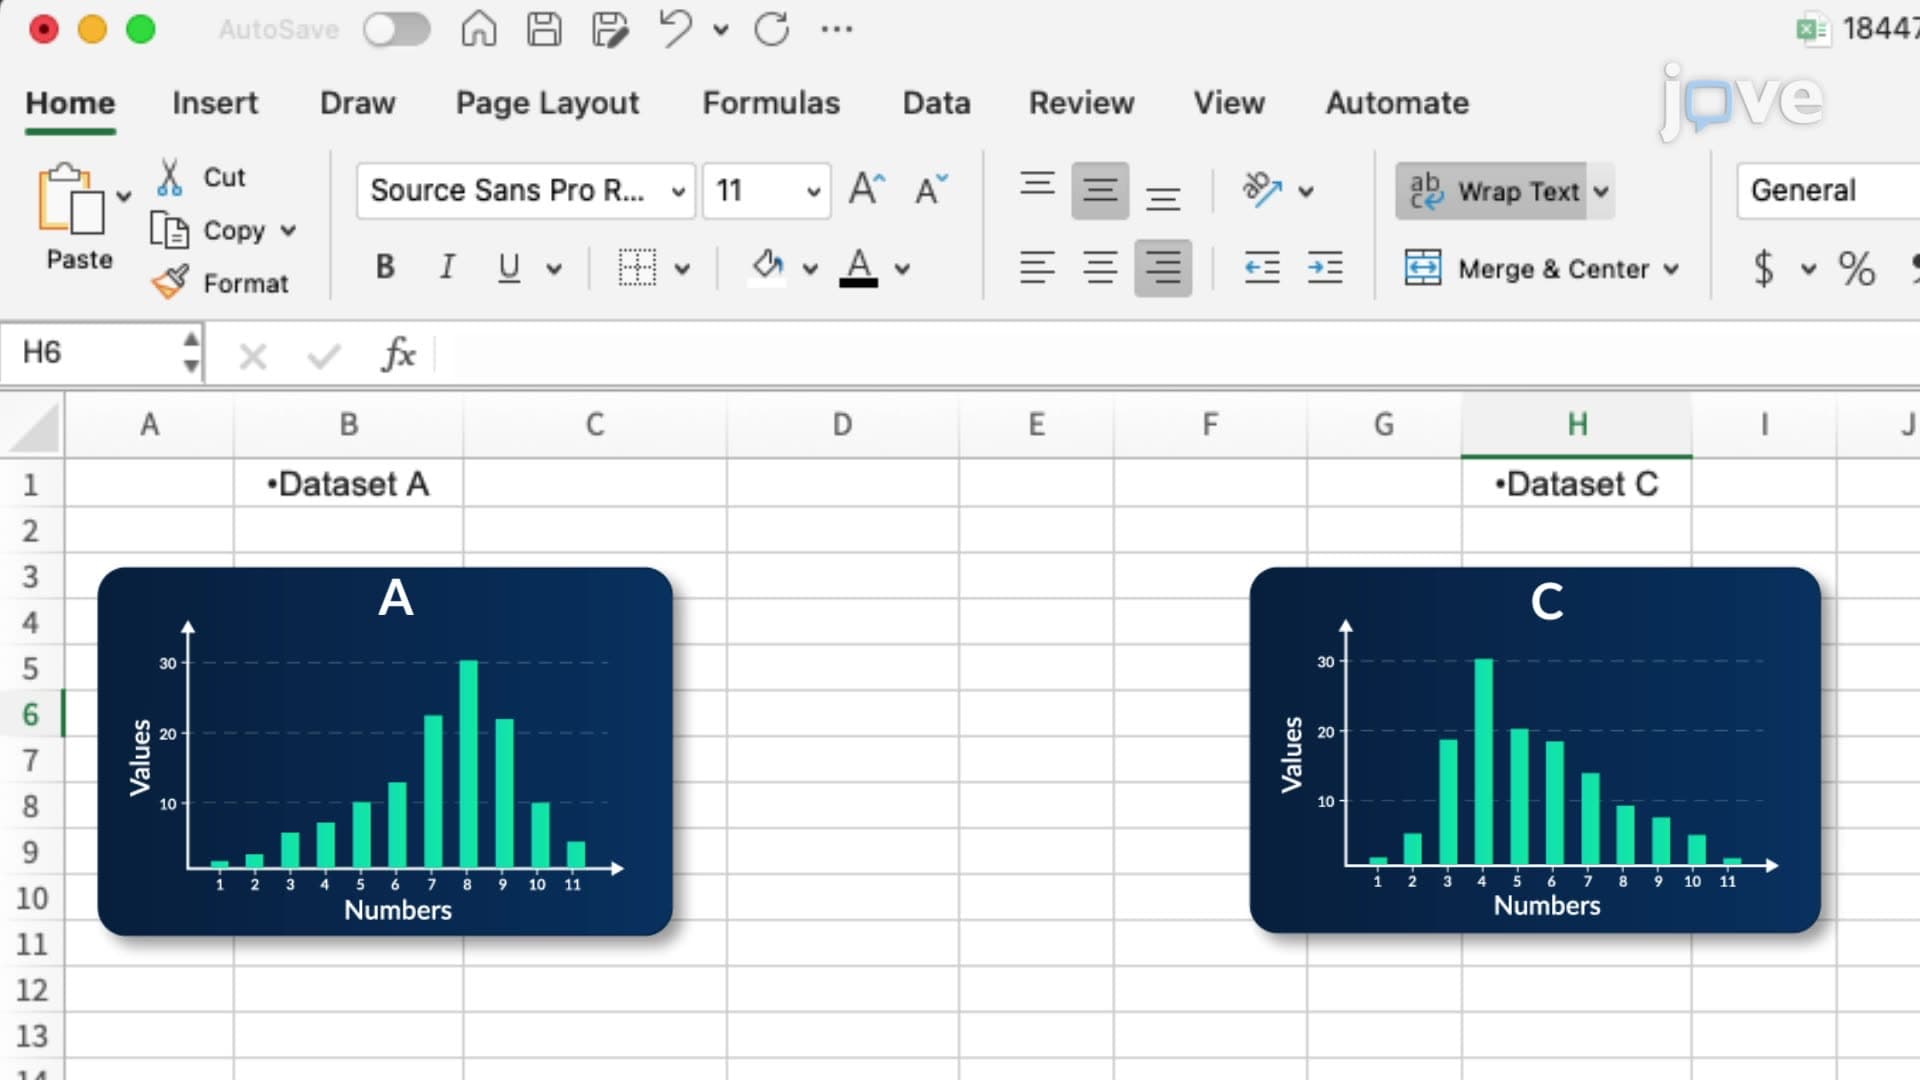 01:24
Microsoft Excel: Finding Central Tendency, Skew, and Kurtosis
Mean: The arithmetic average of all data points. It is calculated by adding all the values together and dividing by the number of values. The mean is sensitive to extreme values (outliers).
Median: The middle value when the data points are arranged in ascending or descending...
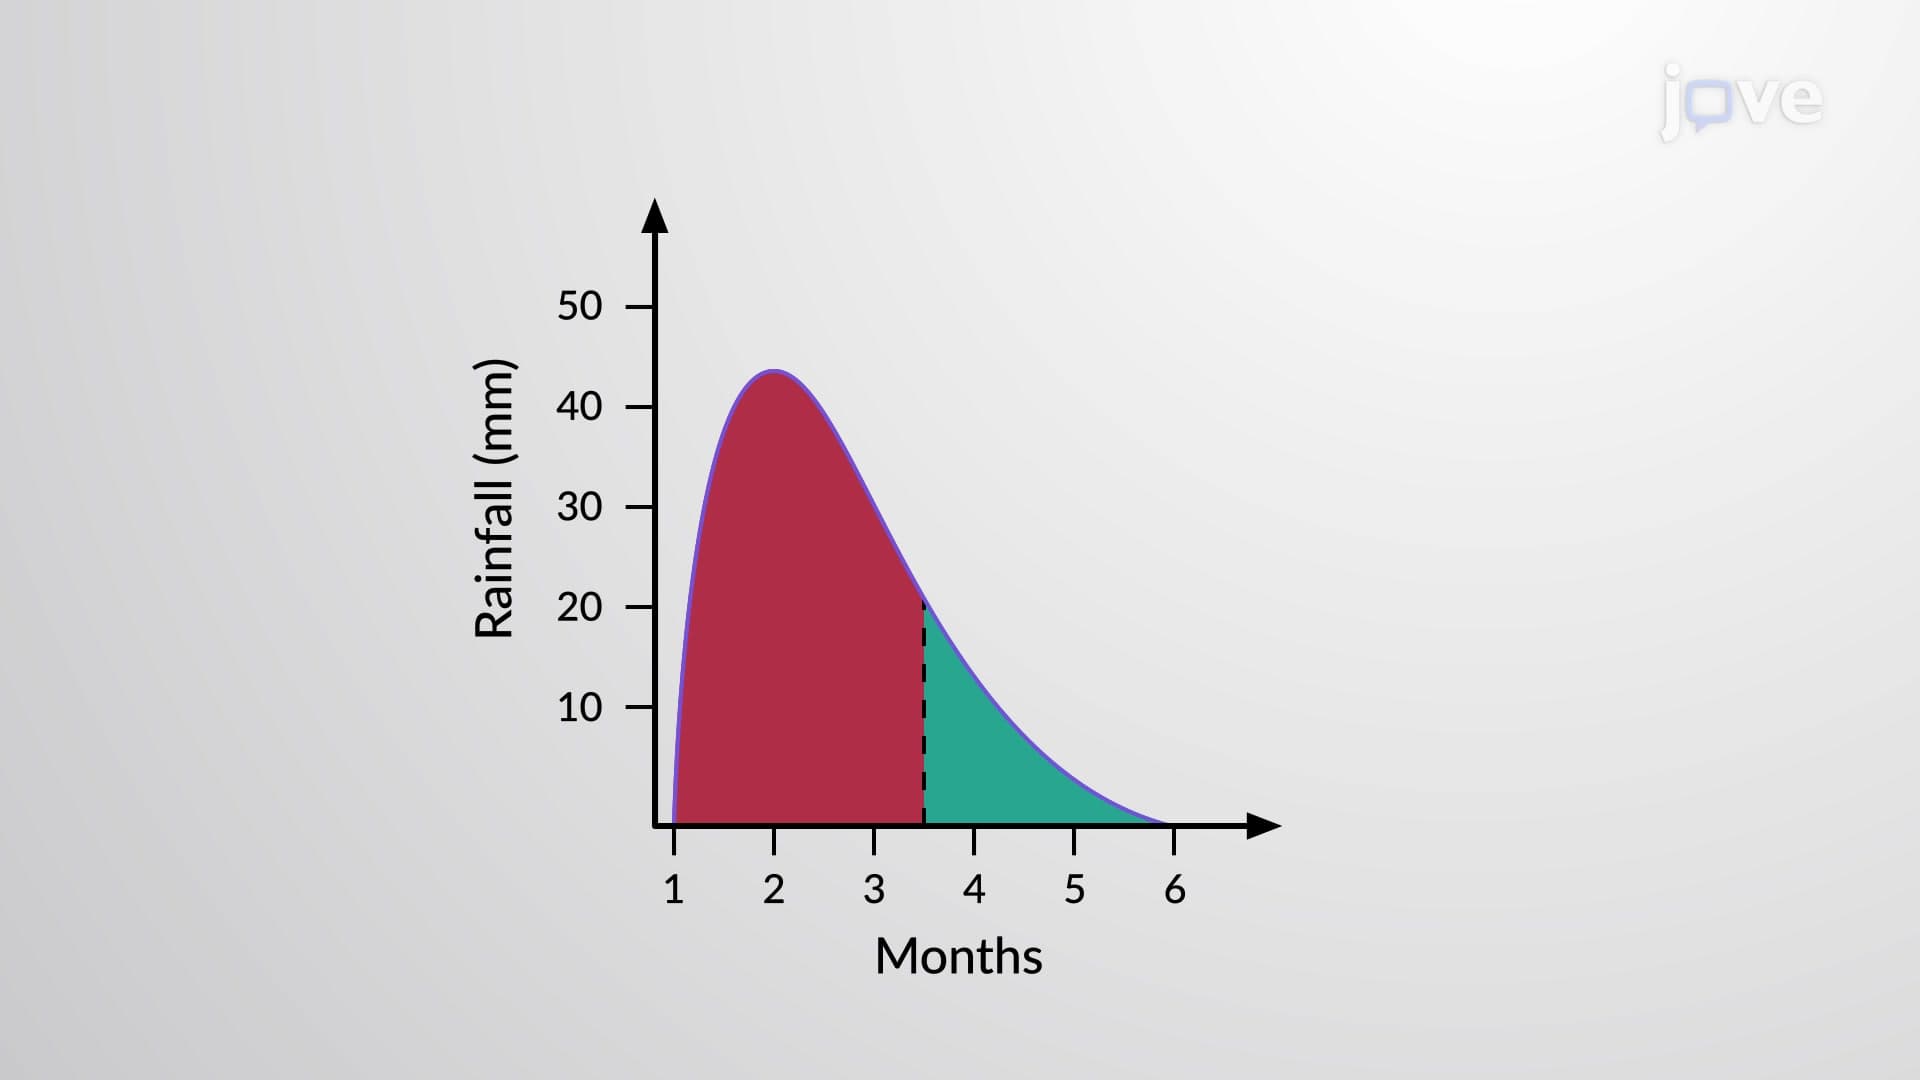 01:06
Skewness
The longer the tail of the plot on one side, the more skewed it is. The skewness of a data set’s values suggests that the measures of central tendency are...
 01:09
Types of Skewness
For instance, in the middle of a pandemic, the geographical distribution of vaccine coverage may be positively skewed towards populations in the global north countries. However,...
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance, comparing...
 01:09
Statistical Methods to Analyze Parametric Data: Student t-Test and Goodness-of-Fit Test
The Student's t-test is a statistical test that examines if there is a statistically significant difference between the means of two groups. This test is instrumental when dealing with data...
 01:16
Goodness-of-Fit Test