Fitting and interpreting loglinear interactions in cross-classifications from health policy and medicine

M L Brown1

  • 1Department of Mathematics, Simmons College, Boston, Mass.

Related Concept Videos

Biostatistics: Overview01:20

Biostatistics: Overview

Biostatistics plays a crucial role in understanding and analyzing data in healthcare and biology. Biostatisticians conduct experiments, gather evidence, and draw meaningful conclusions using statistical methods and techniques. Different variables form the foundation of biostatistical analysis, allowing researchers to understand and interpret data effectively. These variables are classified into different types, each serving a specific purpose in statistical analysis.
Discrete variables are...
Mechanistic Models: Compartment Models in Individual and Population Analysis01:23

Mechanistic Models: Compartment Models in Individual and Population Analysis
Mechanistic models are utilized in individual analysis using single-source data, but imperfections arise due to data collection errors, preventing perfect prediction of observed data. The mathematical equation involves known values (Xi), observed concentrations (Ci), measurement errors (εi), model parameters (ϕj), and the related function (ƒi) for i number of values. Different least-squares metrics quantify differences between predicted and observed values. The ordinary least squares (OLS)...
Pharmacodynamic Models: Logarithmic Concentration–Effect Model01:15

Pharmacodynamic Models: Logarithmic Concentration–Effect Model

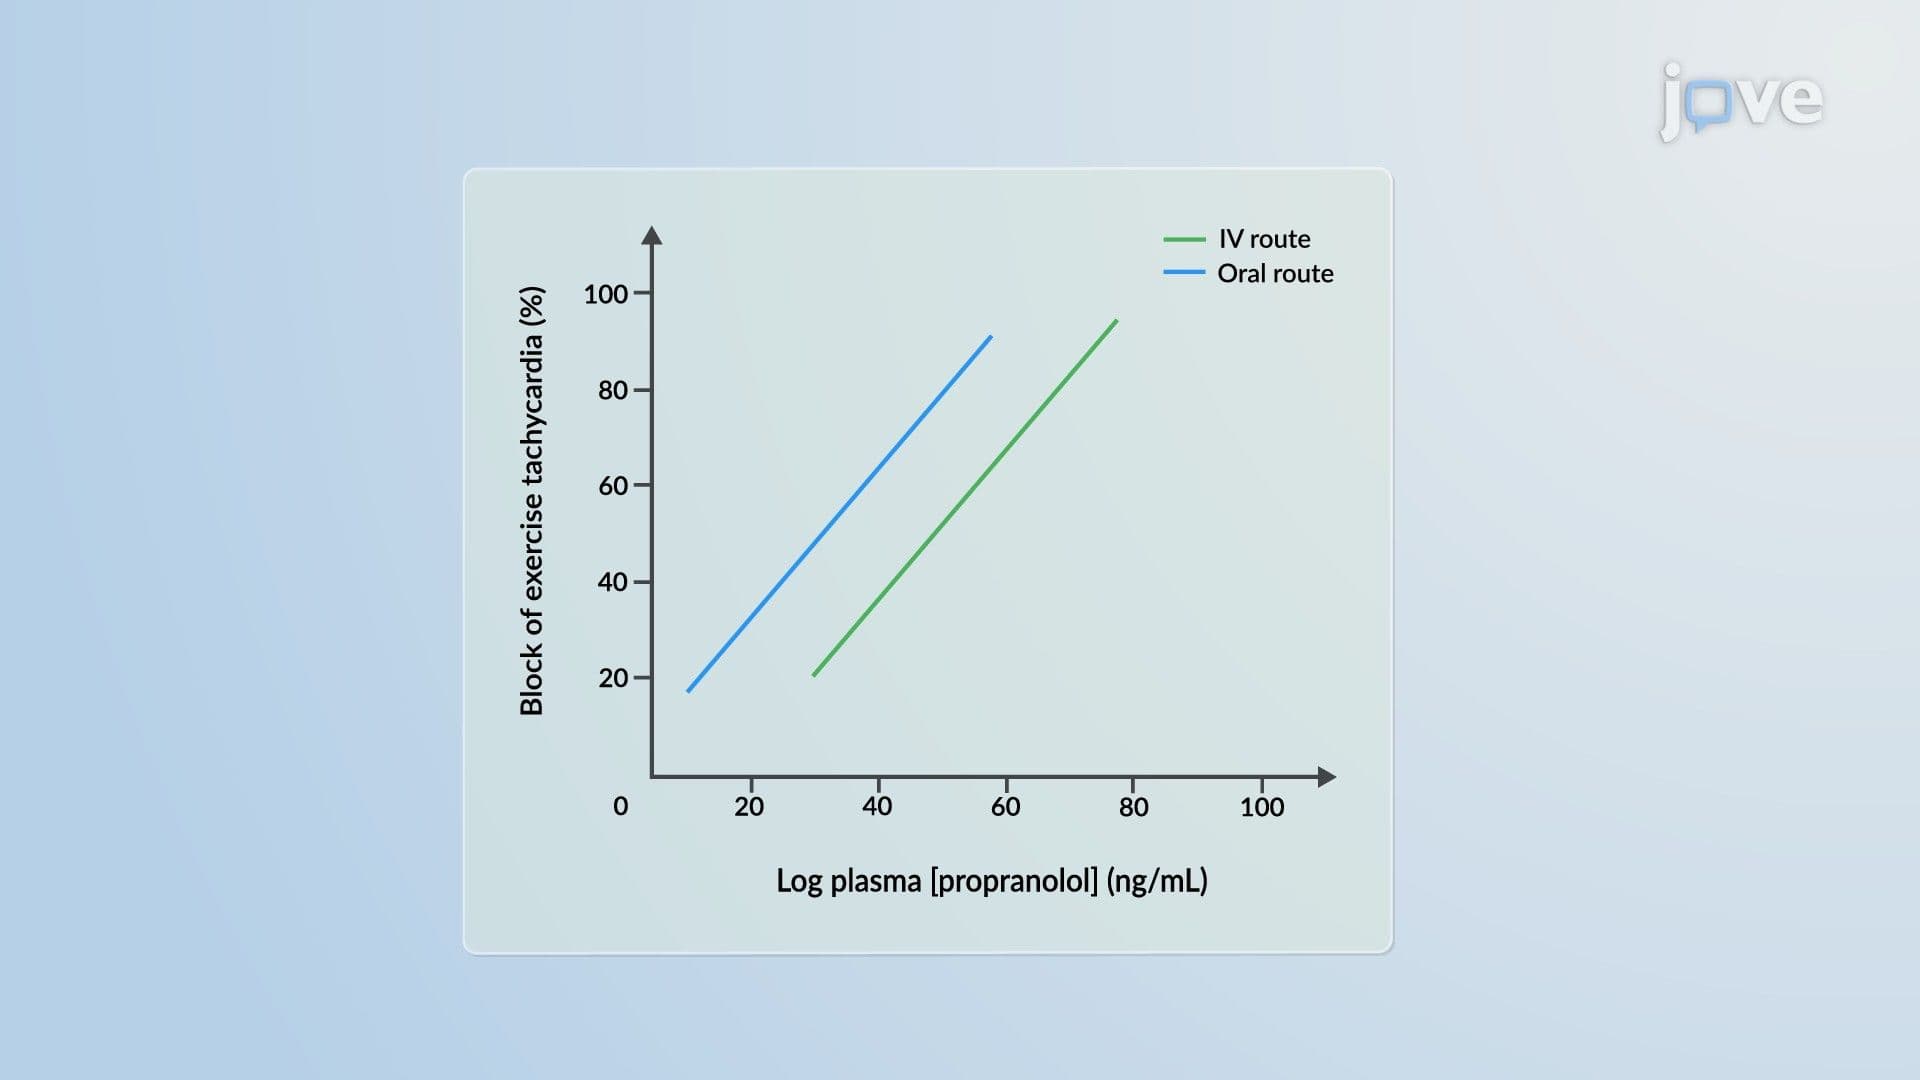
The log-linear model is a pharmacological framework used to describe the relationship between drug concentration and its effect. This model is particularly relevant when the observed effects range between 20% and 80% of the drug’s maximum effect (Emax), where a near-linear relationship is observed between the log of drug concentration and the measured effect. However, the log-linear model does not predict the maximum possible effect (Emax) or the effect at zero drug concentration, limiting its...
Statistical Methods for Analyzing Epidemiological Data01:25

Statistical Methods for Analyzing Epidemiological Data

Epidemiological data primarily involves information on specific populations' occurrence, distribution, and determinants of health and diseases. This data is crucial for understanding disease patterns and impacts, aiding public health decision-making and disease prevention strategies. The analysis of epidemiological data employs various statistical methods to interpret health-related data effectively. Here are some commonly used methods:
Comparing the Survival Analysis of Two or More Groups01:20

Comparing the Survival Analysis of Two or More Groups
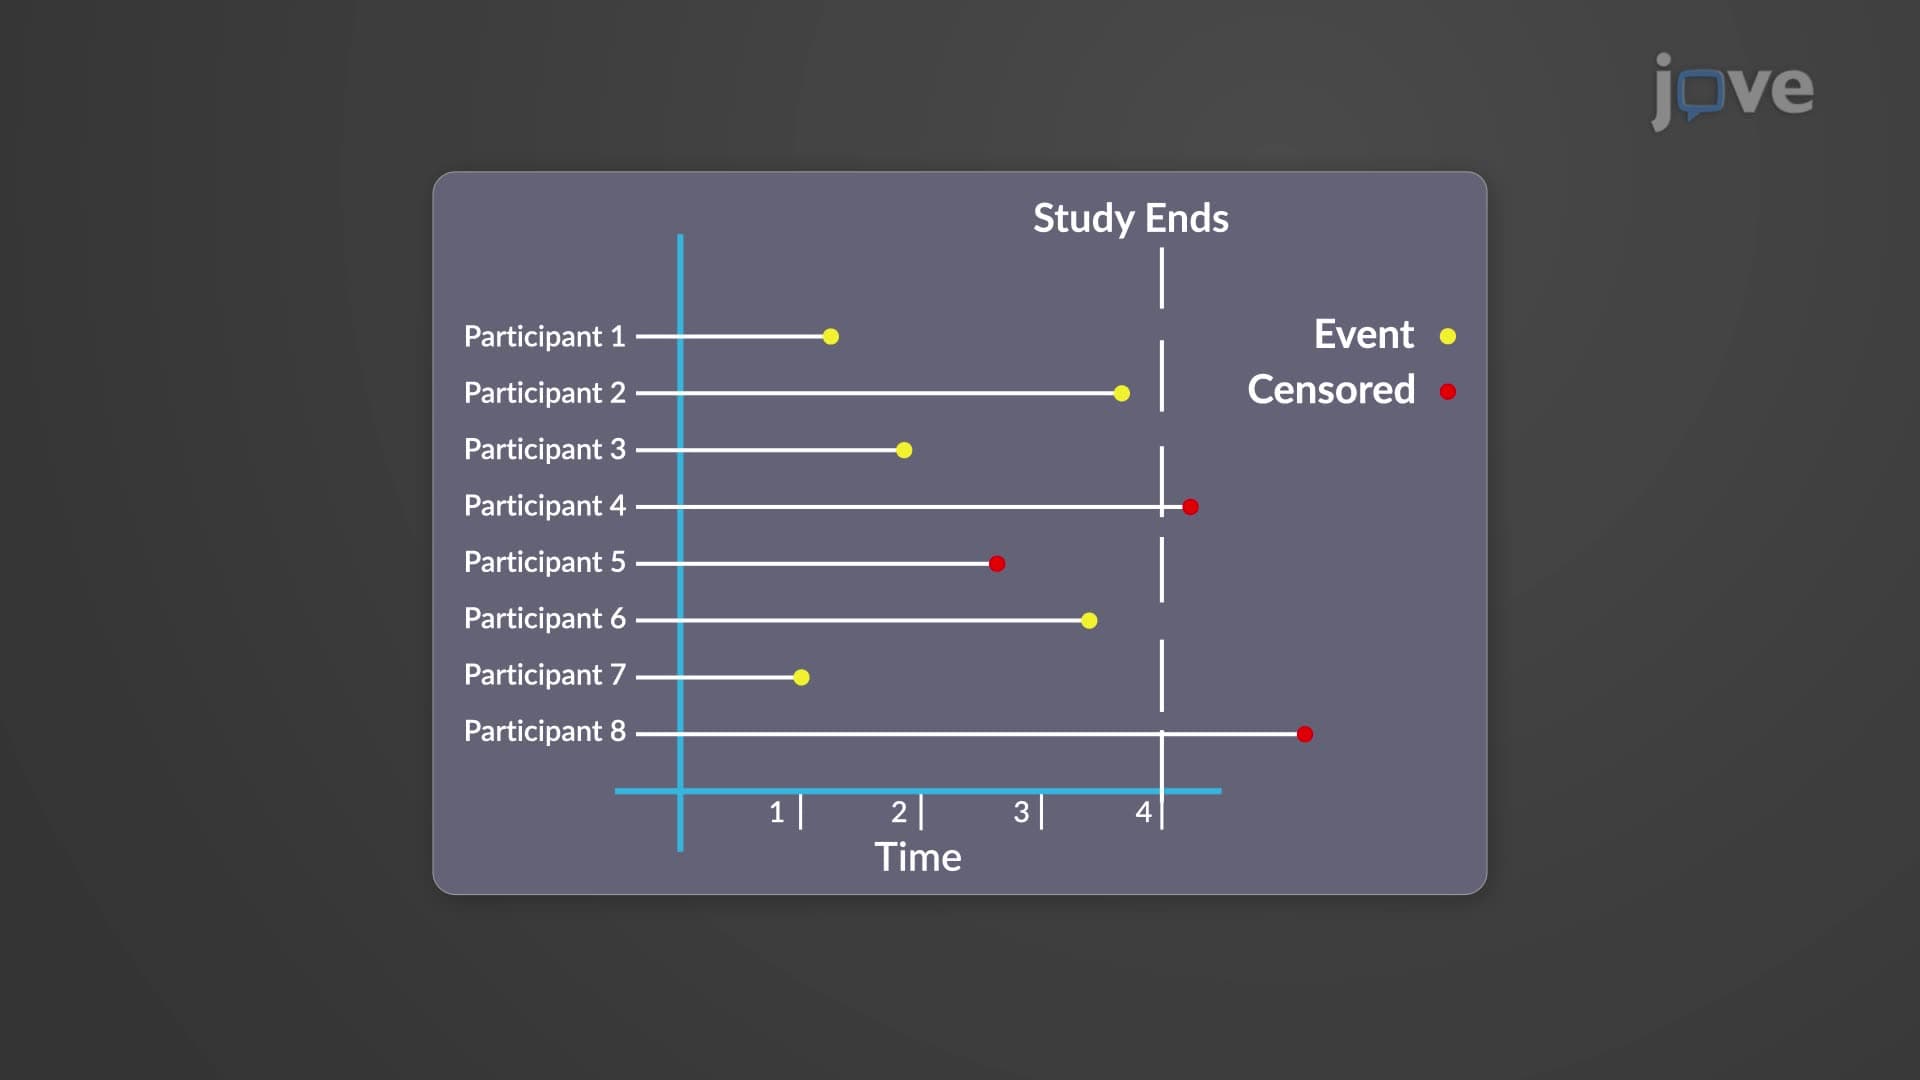
Survival analysis is a cornerstone of medical research, used to evaluate the time until an event of interest occurs, such as death, disease recurrence, or recovery. Unlike standard statistical methods, survival analysis is particularly adept at handling censored data—instances where the event has not occurred for some participants by the end of the study or remains unobserved. To address these unique challenges, specialized techniques like the Kaplan-Meier estimator, log-rank test, and Cox...
The Mantel-Cox Log-Rank Test01:19

The Mantel-Cox Log-Rank Test

The Mantel-Cox log-rank test is a widely used statistical method for comparing the survival distributions of two groups. It tests whether a statistically significant difference exists in survival times between the groups without assuming a specific distribution for the survival data, making it a non-parametric test. This flexibility makes the log-rank test particularly valuable in medical research and other fields where the timing of an event, such as death or disease recurrence, is of interest.
