Related Experiment Video
Updated: May 12, 2026
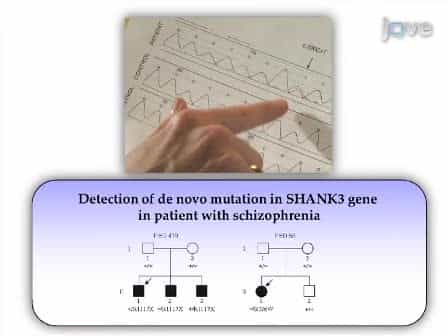
A Strategy to Identify de Novo Mutations in Common Disorders such as Autism and Schizophrenia
Published on: June 15, 2011
Simple and efficient identification of rare recessive pathologically important sequence variants from next generation
Ian M Carr1, Joanne Morgan, Christopher Watson
1School of Medicine, University of Leeds, Leeds, United Kingdom. i.m.carr@leeds.ac.uk

Abstract:
Massively parallel ("next generation") DNA sequencing (NGS) has quickly become the method of choice for seeking pathogenic mutations in rare uncharacterized monogenic diseases. Typically, before DNA sequencing, protein-coding regions are enriched from patient genomic DNA, representing either the entire genome ("exome sequencing") or selected mapped candidate loci. Sequence variants, identified as differences between the patient's and the human genome reference sequences, are then filtered according to various quality parameters. Changes are screened against datasets of known polymorphisms, such as dbSNP and the 1000 Genomes Project, in the effort to narrow the list of candidate causative variants. An increasing number of commercial services now offer to both generate and align NGS data to a reference genome. This potentially allows small groups with limited computing infrastructure and informatics skills to utilize this technology. However, the capability to effectively filter and assess sequence variants is still an important bottleneck in the identification of deleterious sequence variants in both research and diagnostic settings. We have developed an approach to this problem comprising a user-friendly suite of programs that can interactively analyze, filter and screen data from enrichment-capture NGS data. These programs ("Agile Suite") are particularly suitable for small-scale gene discovery or for diagnostic analysis.

Related Concept Videos
 03:00
Next-generation Sequencing
Next-Generation Sequencing Methods
Although all next-generation methods use different technologies, they all share a set of standard features.
 02:26
Comparing Copy Number Variations and SNPs
Copy number variations or CNVs are the structural variations that cover more than 1kb of DNA sequence. The single nucleotide polymorphism (SNP), on the other hand, is a single nucleotide change or a point mutation that is found in more than 1%...
 02:51
Multi-species Conserved Sequences
Although the genome of each species varies greatly from each other, a few sequences are highly conserved. Such conserved DNA...