Related Experiment Video
Updated: May 4, 2026

Infinium Assay for Large-scale SNP Genotyping Applications
Published on: November 19, 2013
Statistical analysis of big data on pharmacogenomics
1Department of Operations Research and Financial Engineering, Princeton University, Princeton, NJ 08544, USA. jqfan@princeton.edu

Abstract:
This paper discusses statistical methods for estimating complex correlation structure from large pharmacogenomic datasets. We selectively review several prominent statistical methods for estimating large covariance matrix for understanding correlation structure, inverse covariance matrix for network modeling, large-scale simultaneous tests for selecting significantly differently expressed genes and proteins and genetic markers for complex diseases, and high dimensional variable selection for identifying important molecules for understanding molecule mechanisms in pharmacogenomics. Their applications to gene network estimation and biomarker selection are used to illustrate the methodological power. Several new challenges of Big data analysis, including complex data distribution, missing data, measurement error, spurious correlation, endogeneity, and the need for robust statistical methods, are also discussed.
More Related Videos
 08:27
Large-Scale Multi-Omics Genome-Wide Association Studies Mo-GWAS: Guidelines for Sample Preparation and Normalization
Published on: July 27, 2021
 03:08
Using Human Differentially Expressed Gene Lists to Perform Downstream Pathway Enrichment Analysis and Target Prioritization
Published on: October 3, 2025
Related Concept Videos
 01:12
Analysis of Population Pharmacokinetic Data
 01:29
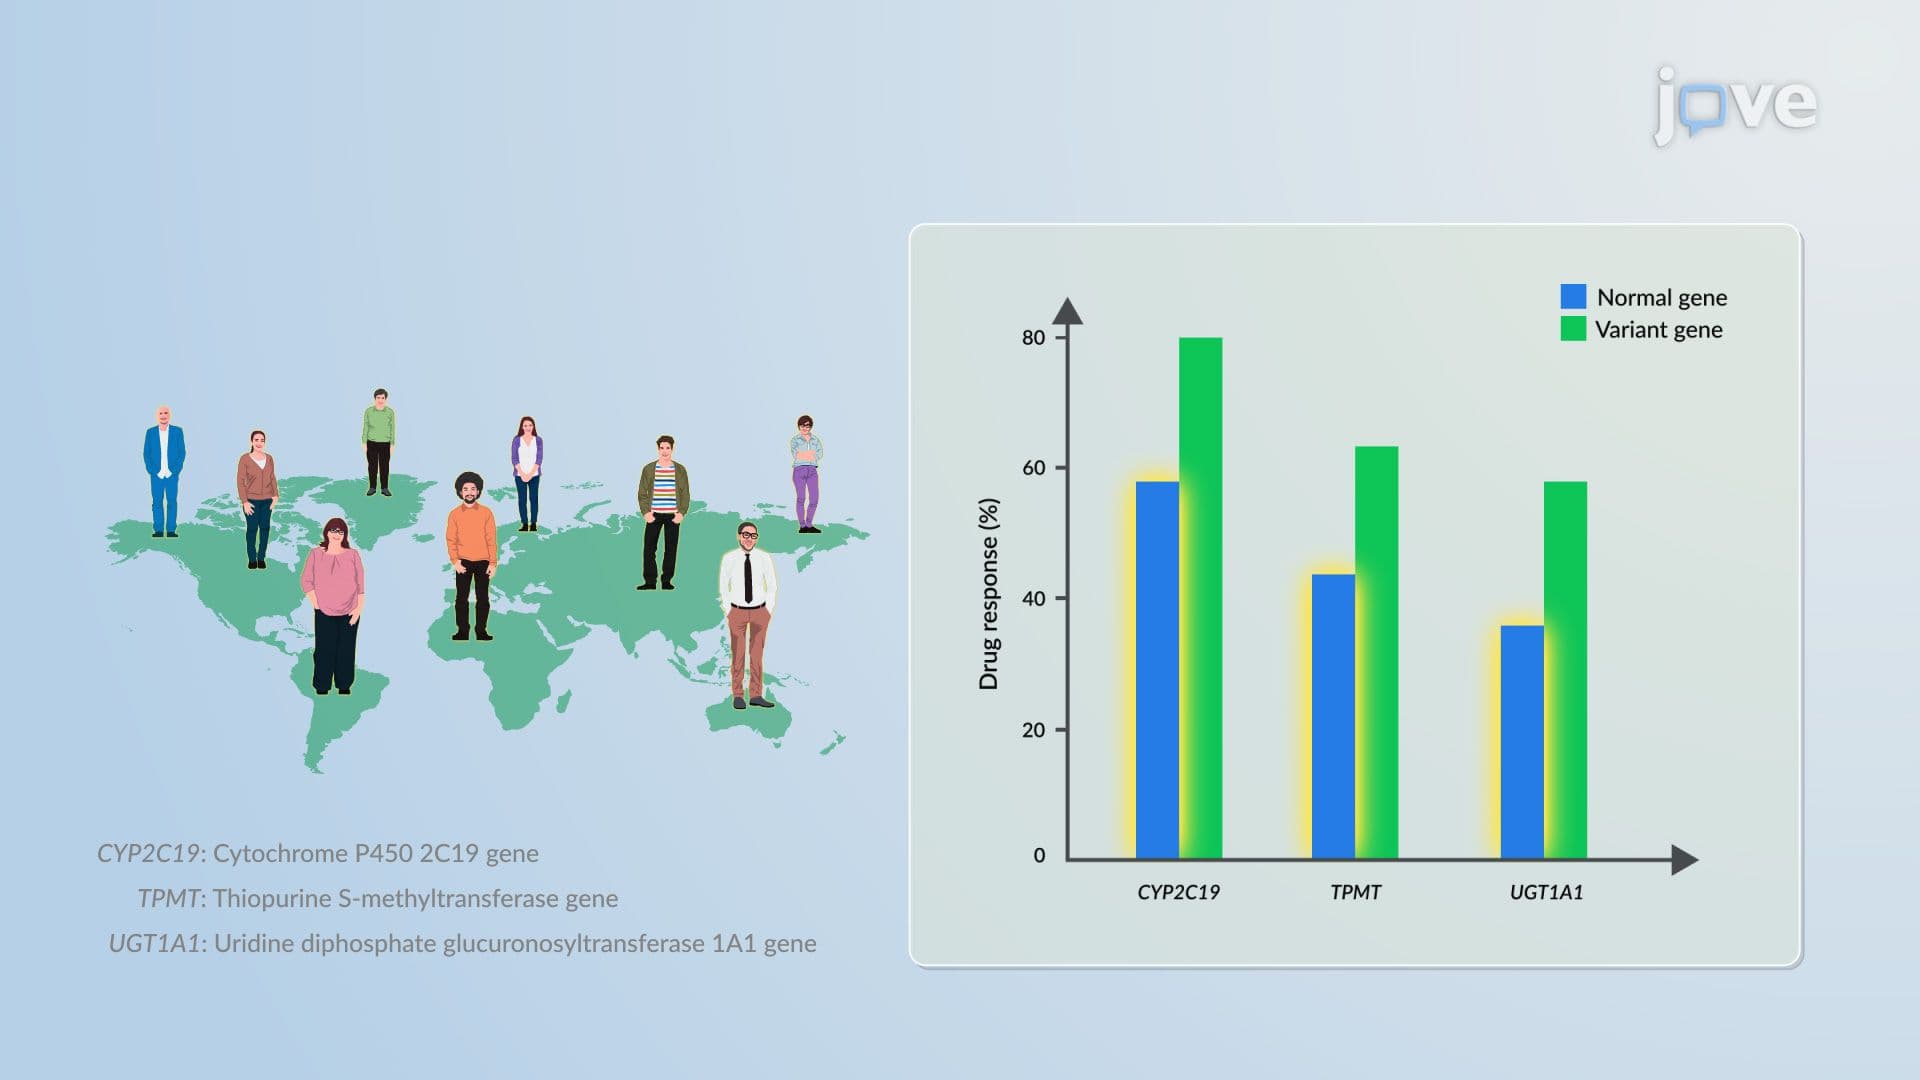
Pharmacogenetics and Pharmacogenomics: Overview
 01:27
Principles of Pharmacogenetics: Types of Genetic Variants
 01:29
Pharmacogenetic Phenotypes: Alterations in Pharmacokinetics, Drug Targets and Biologic Milieu
 01:27
Pharmacogenetics of Drug Metabolism: Overview
 01:29
Pharmacogenomics: Identification of New Drug Targets