Ridge regression in prediction problems: automatic choice of the ridge parameter
Related Experiment Video
Updated: May 9, 2026
Assessing Cerebral Autoregulation via Oscillatory Lower Body Negative Pressure and Projection Pursuit Regression
Published on: December 10, 2014
1Department of Epidemiology and Biostatistics, Imperial College London, London, United Kingdom; Statistical Consulting Group, GlaxoSmithKline, Stevenage, United Kingdom.

Abstract:
To date, numerous genetic variants have been identified as associated with diverse phenotypic traits. However, identified associations generally explain only a small proportion of trait heritability and the predictive power of models incorporating only known-associated variants has been small. Multiple regression is a popular framework in which to consider the joint effect of many genetic variants simultaneously. Ordinary multiple regression is seldom appropriate in the context of genetic data, due to the high dimensionality of the data and the correlation structure among the predictors. There has been a resurgence of interest in the use of penalised regression techniques to circumvent these difficulties. In this paper, we focus on ridge regression, a penalised regression approach that has been shown to offer good performance in multivariate prediction problems. One challenge in the application of ridge regression is the choice of the ridge parameter that controls the amount of shrinkage of the regression coefficients. We present a method to determine the ridge parameter based on the data, with the aim of good performance in high-dimensional prediction problems. We establish a theoretical justification for our approach, and demonstrate its performance on simulated genetic data and on a real data example. Fitting a ridge regression model to hundreds of thousands to millions of genetic variants simultaneously presents computational challenges. We have developed an R package, ridge, which addresses these issues. Ridge implements the automatic choice of ridge parameter presented in this paper, and is freely available from CRAN.

Related Concept Videos
 01:11
Regression Analysis
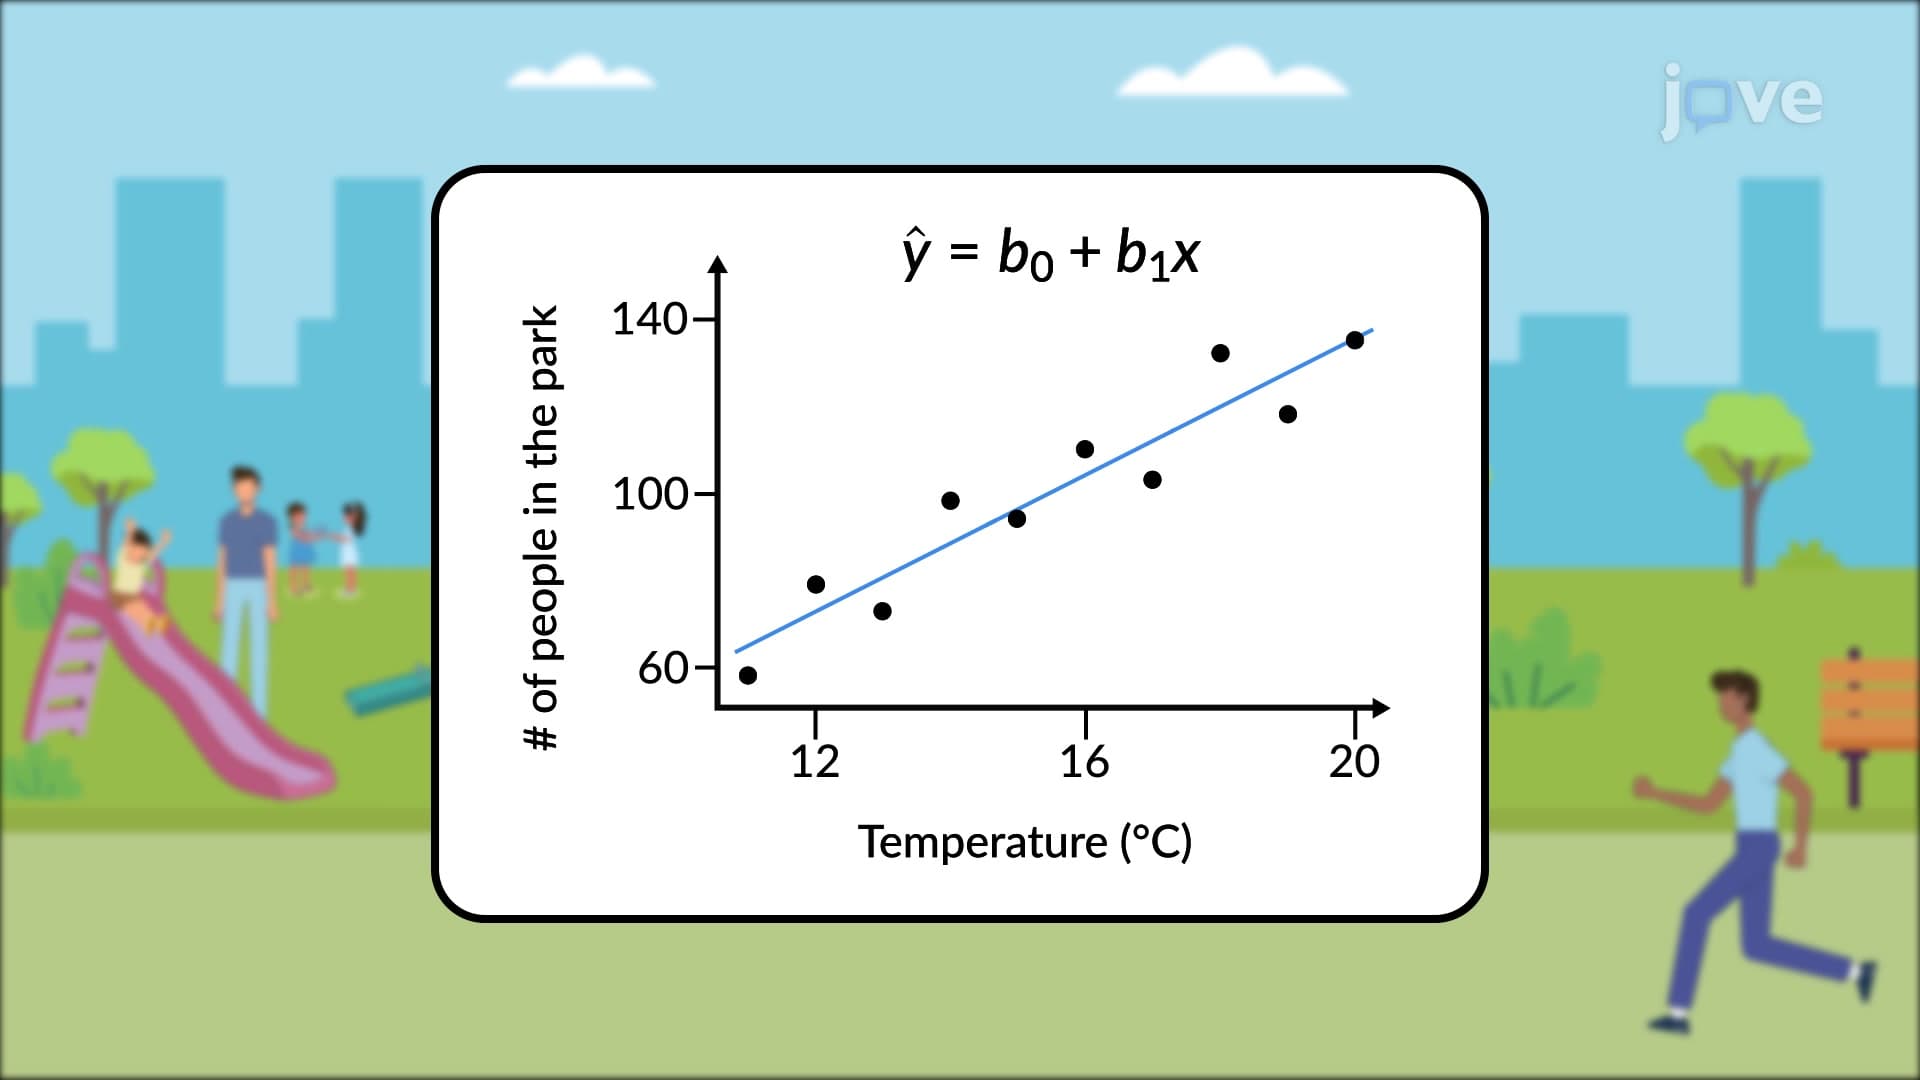
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
 01:25
Multiple Regression
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:19
Variation
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
 01:52
Regression Toward the Mean
 01:18
Microsoft Excel: Regression Analysis
To perform regression...