Related Experiment Video
Updated: May 8, 2026

Online Explorative Study on the Learning Uses of Virtual Reality Among Early Adopters
Published on: November 22, 2019
Explorations in statistics: the analysis of ratios and normalized data
1Division of Biostatistics and Bioinformatics, National Jewish Health, Denver, Colorado; and Department of Biostatistics and Informatics, Colorado School of Public Health, University of Colorado, Denver, Colorado.

Abstract:
Learning about statistics is a lot like learning about science: the learning is more meaningful if you can actively explore. This ninth installment of Explorations in Statistics explores the analysis of ratios and normalized-or standardized-data. As researchers, we compute a ratio-a numerator divided by a denominator-to compute a proportion for some biological response or to derive some standardized variable. In each situation, we want to control for differences in the denominator when the thing we really care about is the numerator. But there is peril lurking in a ratio: only if the relationship between numerator and denominator is a straight line through the origin will the ratio be meaningful. If not, the ratio will misrepresent the true relationship between numerator and denominator. In contrast, regression techniques-these include analysis of covariance-are versatile: they can accommodate an analysis of the relationship between numerator and denominator when a ratio is useless.

Related Concept Videos
 00:54
Ratio Level of Measurement
A set of data measured using the ratio scale takes care of the ratio problem and provides complete information. Ratio scale data are like interval scale data, except they have a zero point and ratios can be calculated. For...
 01:29
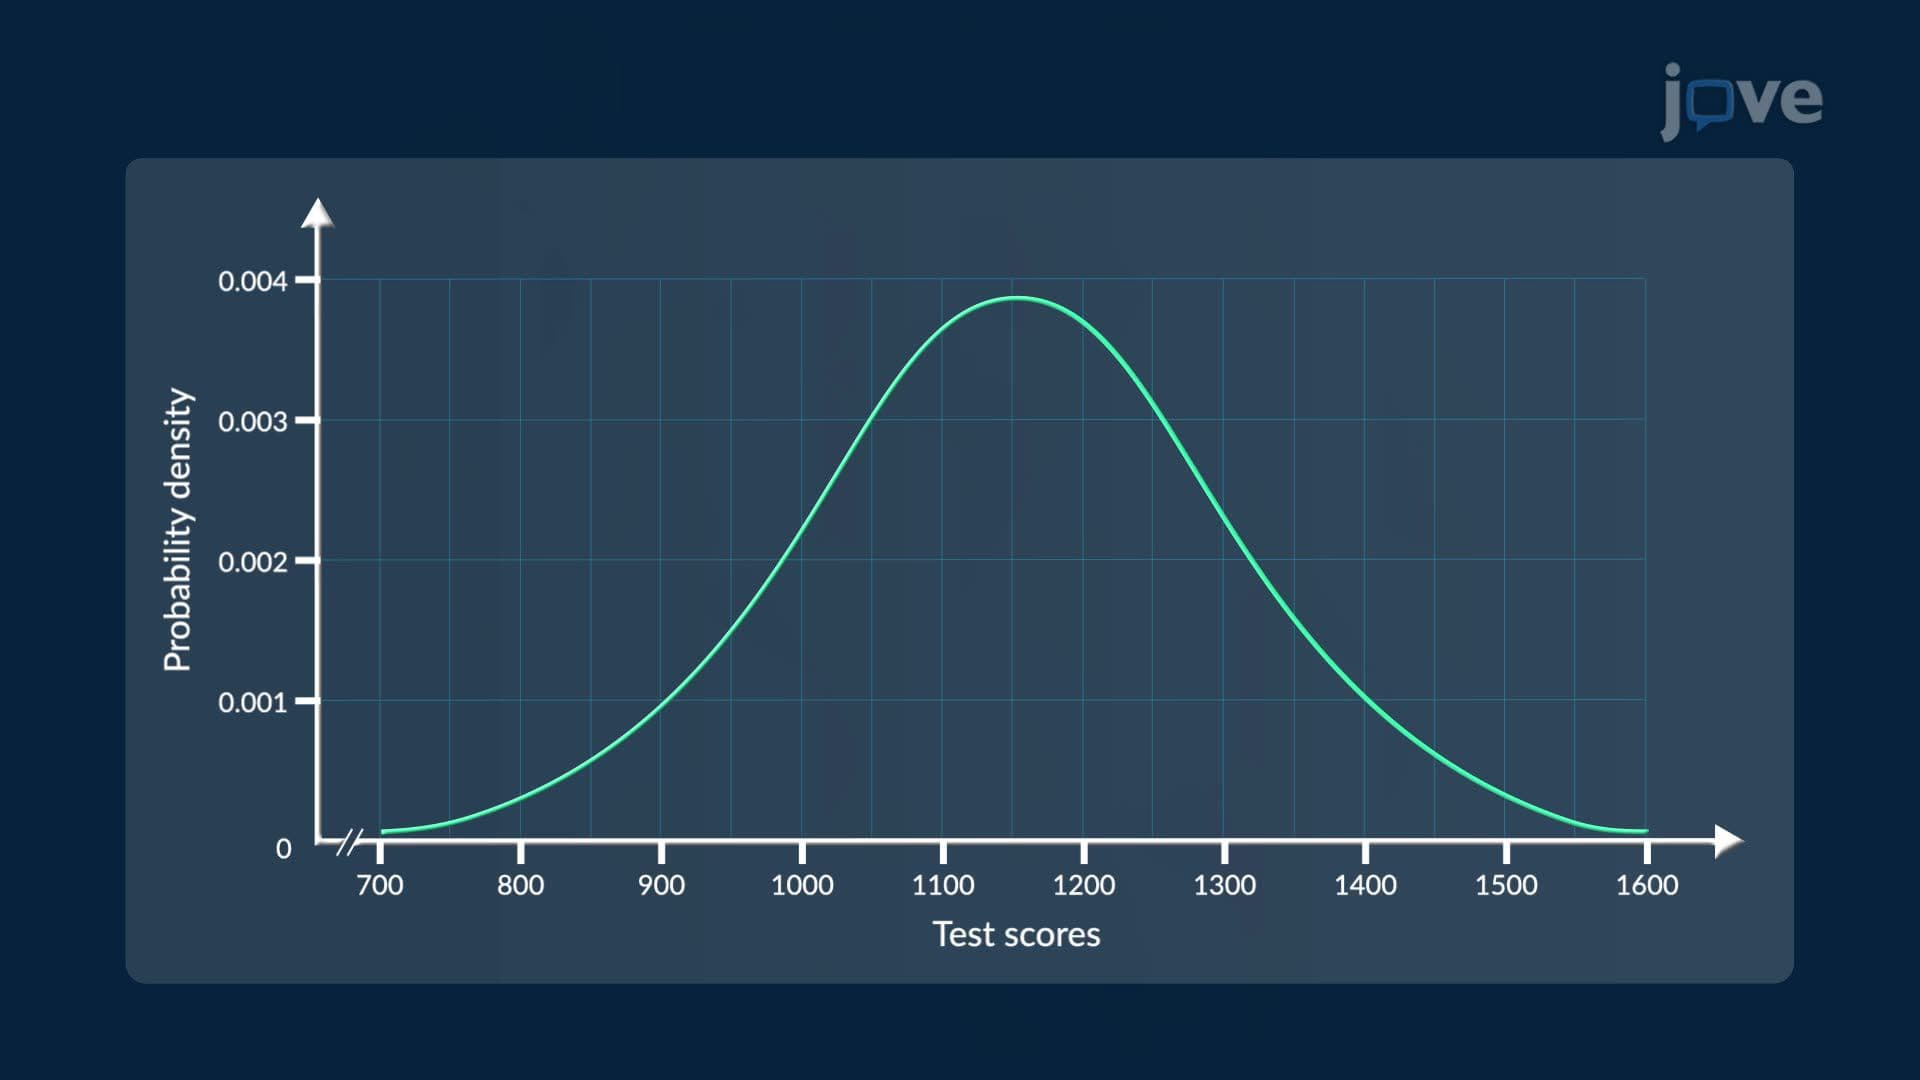
Introduction to Normal Distributions
 01:10
Review and Preview
Percentiles are a type of fractile that partition data into...
 01:13
Review and Preview
 01:11
Statistical Analysis: Overview
One of the most commonly used statistical quantifiers is the mean, which is the ratio between the sum of the numerical values of all results and the...
 01:21
Friedman Two-way Analysis of Variance by Ranks