Related Experiment Video
Updated: May 7, 2026

A Knowledge Graph Approach to Elucidate the Role of Organellar Pathways in Disease via Biomedical Reports
Published on: October 13, 2023
Extracting laboratory test information from biomedical text
Yanna Shen Kang1, Mehmet Kayaalp
1Center for Devices and Radiological Health, U.S. Food and Drug Administration, Silver Spring, Maryland, USA.

Background:
No previous study reported the efficacy of current natural language processing (NLP) methods for extracting laboratory test information from narrative documents. This study investigates the pathology informatics question of how accurately such information can be extracted from text with the current tools and techniques, especially machine learning and symbolic NLP methods. The study data came from a text corpus maintained by the U.S. Food and Drug Administration, containing a rich set of information on laboratory tests and test devices.
Methods:
THE AUTHORS DEVELOPED A SYMBOLIC INFORMATION EXTRACTION (SIE) SYSTEM TO EXTRACT DEVICE AND TEST SPECIFIC INFORMATION ABOUT FOUR TYPES OF LABORATORY TEST ENTITIES: Specimens, analytes, units of measures and detection limits. They compared the performance of SIE and three prominent machine learning based NLP systems, LingPipe, GATE and BANNER, each implementing a distinct supervised machine learning method, hidden Markov models, support vector machines and conditional random fields, respectively.
Results:
Machine learning systems recognized laboratory test entities with moderately high recall, but low precision rates. Their recall rates were relatively higher when the number of distinct entity values (e.g., the spectrum of specimens) was very limited or when lexical morphology of the entity was distinctive (as in units of measures), yet SIE outperformed them with statistically significant margins on extracting specimen, analyte and detection limit information in both precision and F-measure. Its high recall performance was statistically significant on analyte information extraction.
Conclusions:
Despite its shortcomings against machine learning methods, a well-tailored symbolic system may better discern relevancy among a pile of information of the same type and may outperform a machine learning system by tapping into lexically non-local contextual information such as the document structure.
More Related Videos
Related Concept Videos
 01:24
Automated Microbial Diagnostics
 01:15
Western Blotting
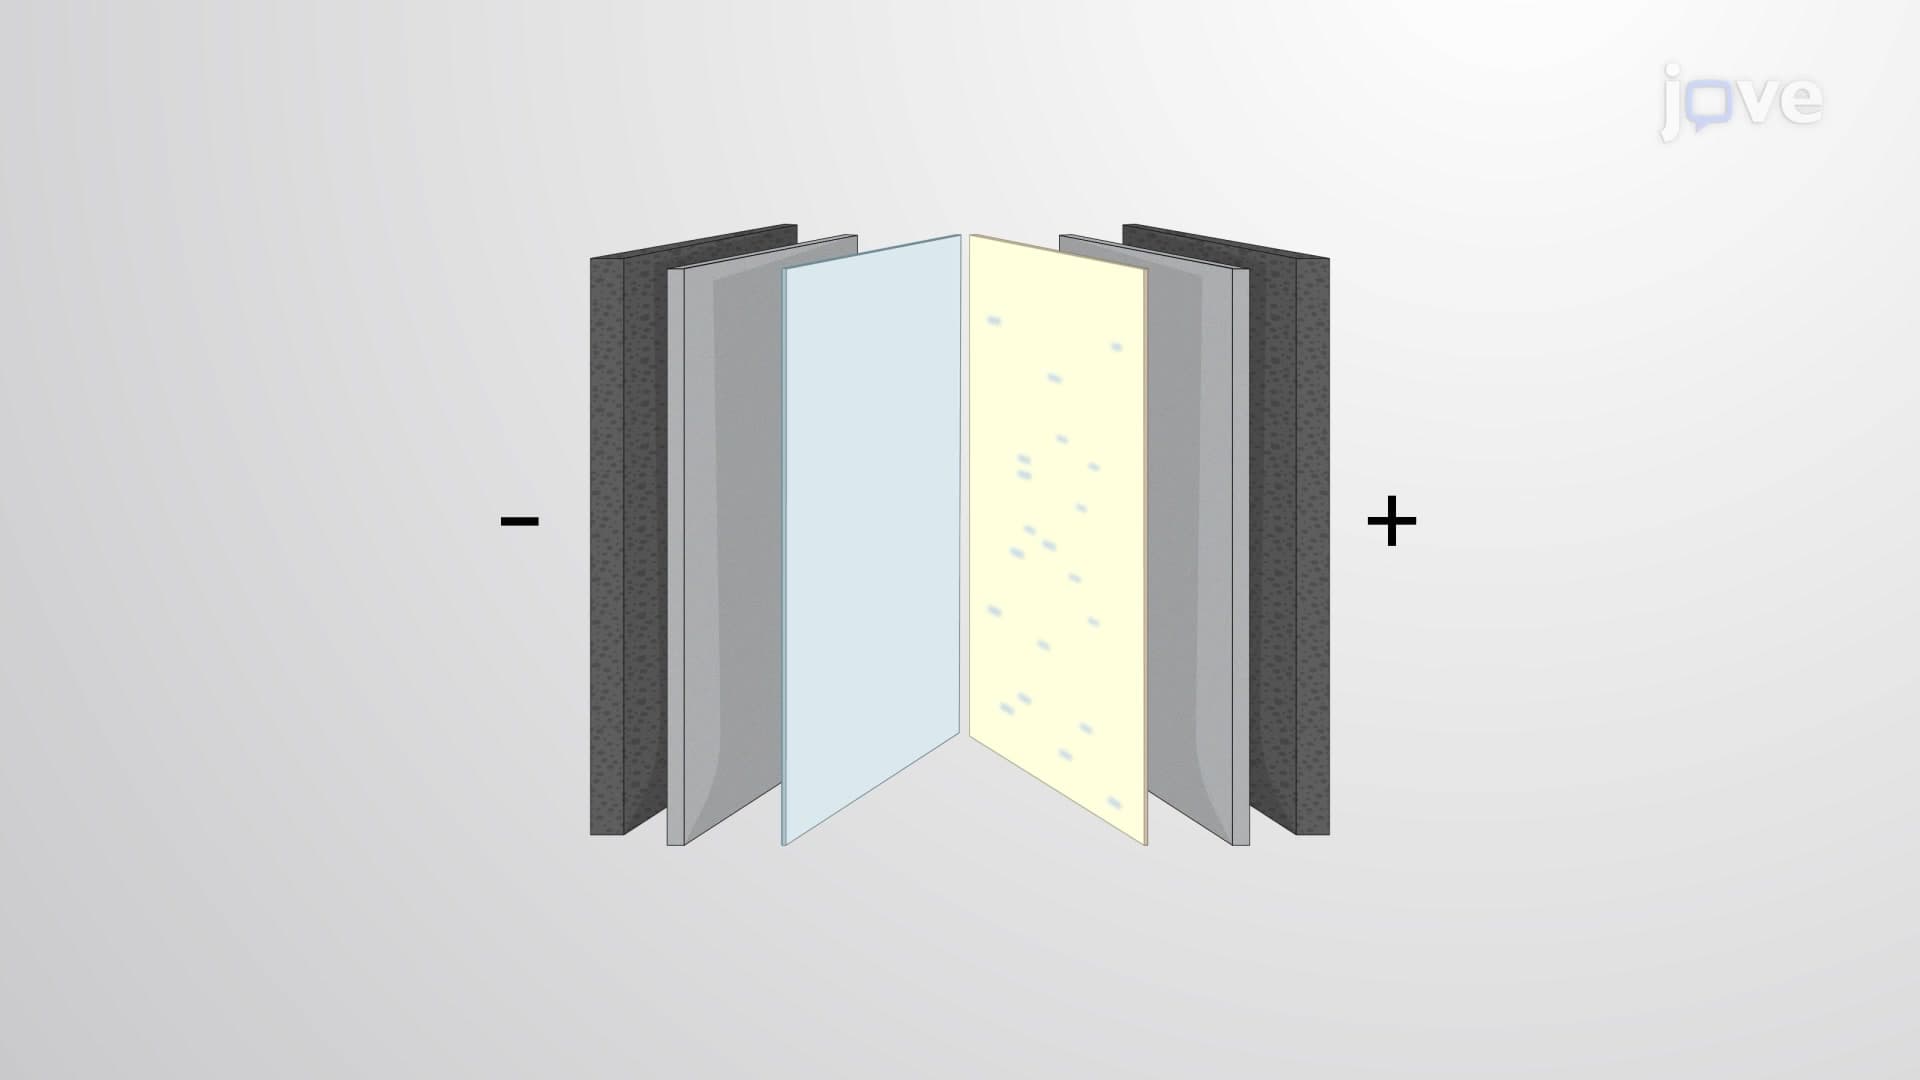
The technique begins with separating proteins from the sample using sodium dodecyl sulfate-polyacrylamide gel electrophoresis (SDS-PAGE), followed by protein transfer, immunoblotting, and finally, protein detection.