Related Experiment Video
Updated: May 6, 2026

Characterization of Complex Systems Using the Design of Experiments Approach: Transient Protein Expression in Tobacco as a Case Study
Published on: January 31, 2014
Estimation of influential points in any data set from coefficient of determination and its leave-one-out
Gergely Tóth1, Zsolt Bodai, Károly Héberger
1Institute of Chemistry, Loránd Eötvös University, Pázmány Sétány 1/a, Budapest, 1117, Hungary.

Abstract:
Coefficient of determination (R (2)) and its leave-one-out cross-validated analogue (denoted by Q (2) or R cv (2) ) are the most frequantly published values to characterize the predictive performance of models. In this article we use R (2) and Q (2) in a reversed aspect to determine uncommon points, i.e. influential points in any data sets. The term (1 - Q (2))/(1 - R (2)) corresponds to the ratio of predictive residual sum of squares and the residual sum of squares. The ratio correlates to the number of influential points in experimental and random data sets. We propose an (approximate) F test on (1 - Q (2))/(1 - R (2)) term to quickly pre-estimate the presence of influential points in training sets of models. The test is founded upon the routinely calculated Q (2) and R (2) values and warns the model builders to verify the training set, to perform influence analysis or even to change to robust modeling.

Related Concept Videos
 01:08
Outliers and Influential Points
 01:11
Calculating and Interpreting the Linear Correlation Coefficient
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:25
Multiple Regression
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
 01:19
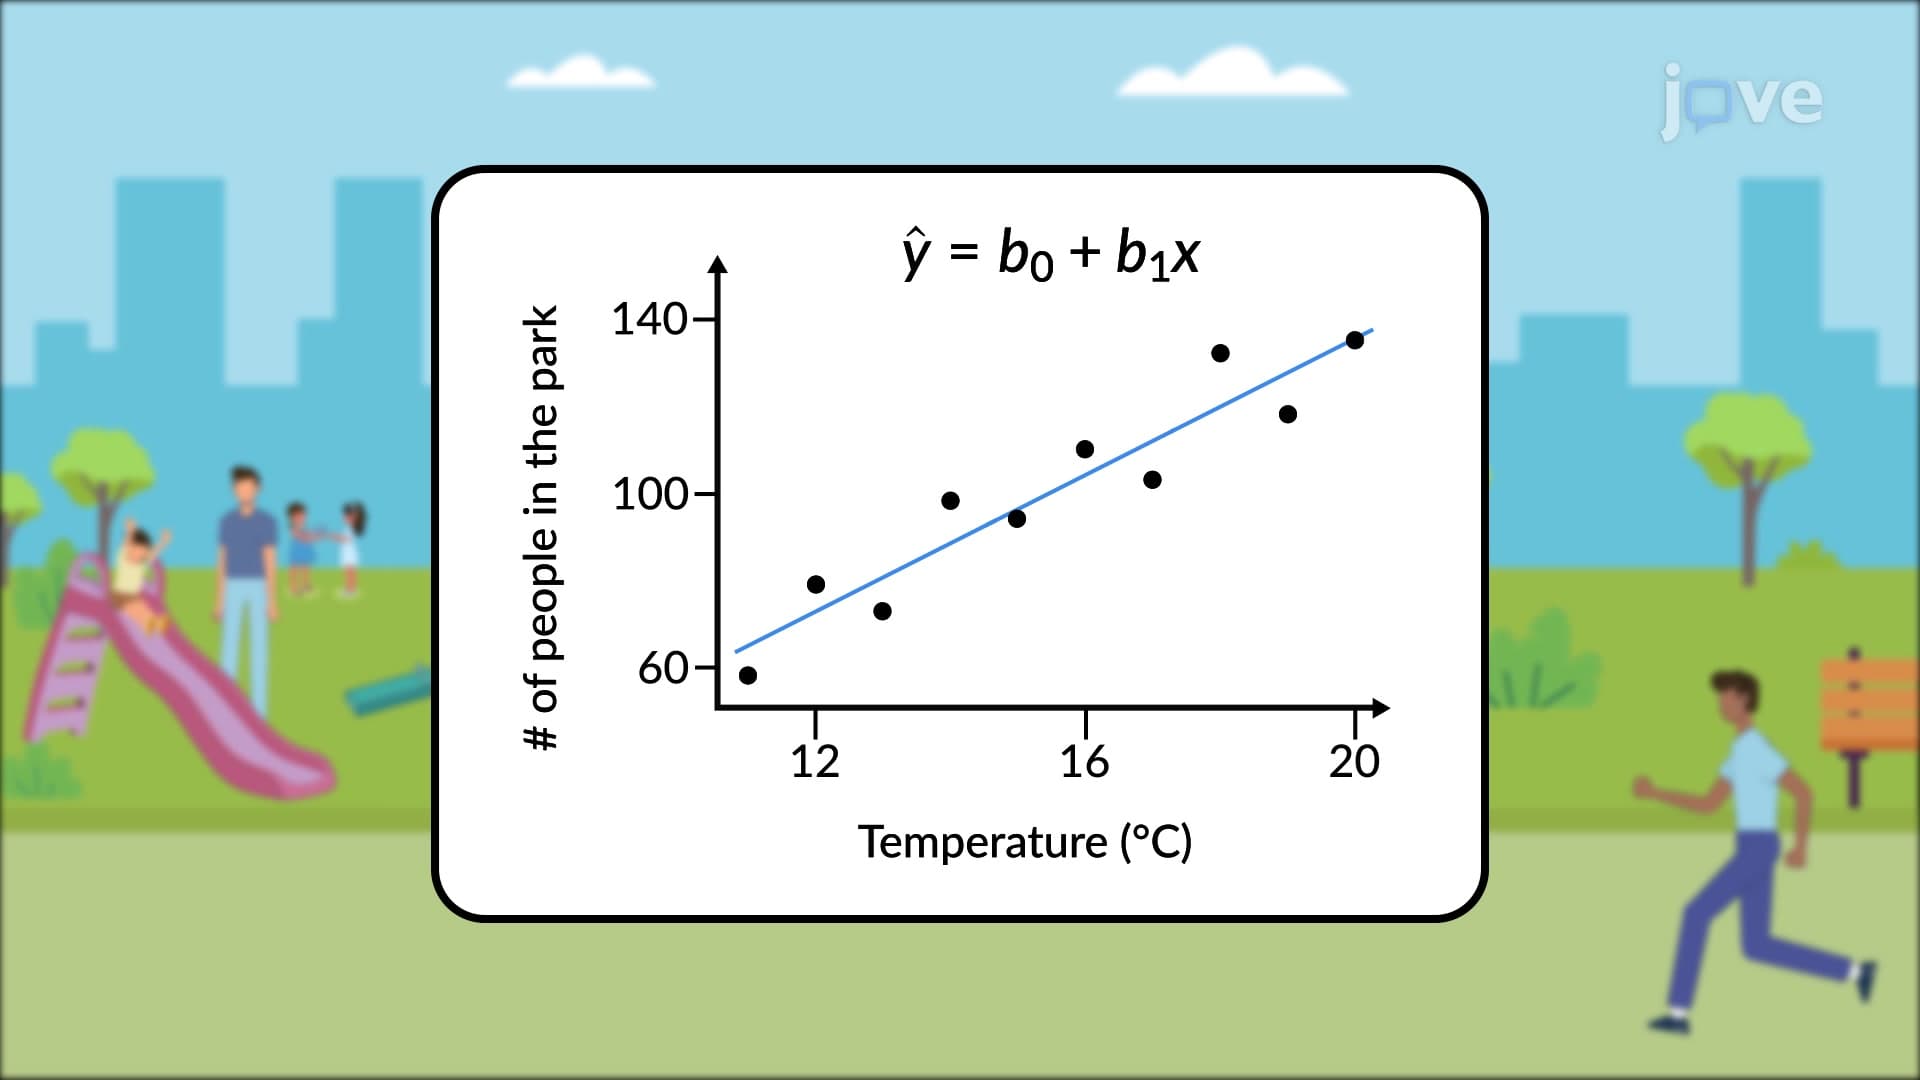
Variation
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
 01:12
Coefficient of Correlation
If you suspect a linear relationship between x and y, then r can measure how strong the linear relationship is.
What the VALUE of r tells us:
The value of r is always between –1 and +1: –1 ≤ r ≤ 1.
The size of the correlation r indicates the...