Related Experiment Video
Updated: May 4, 2026
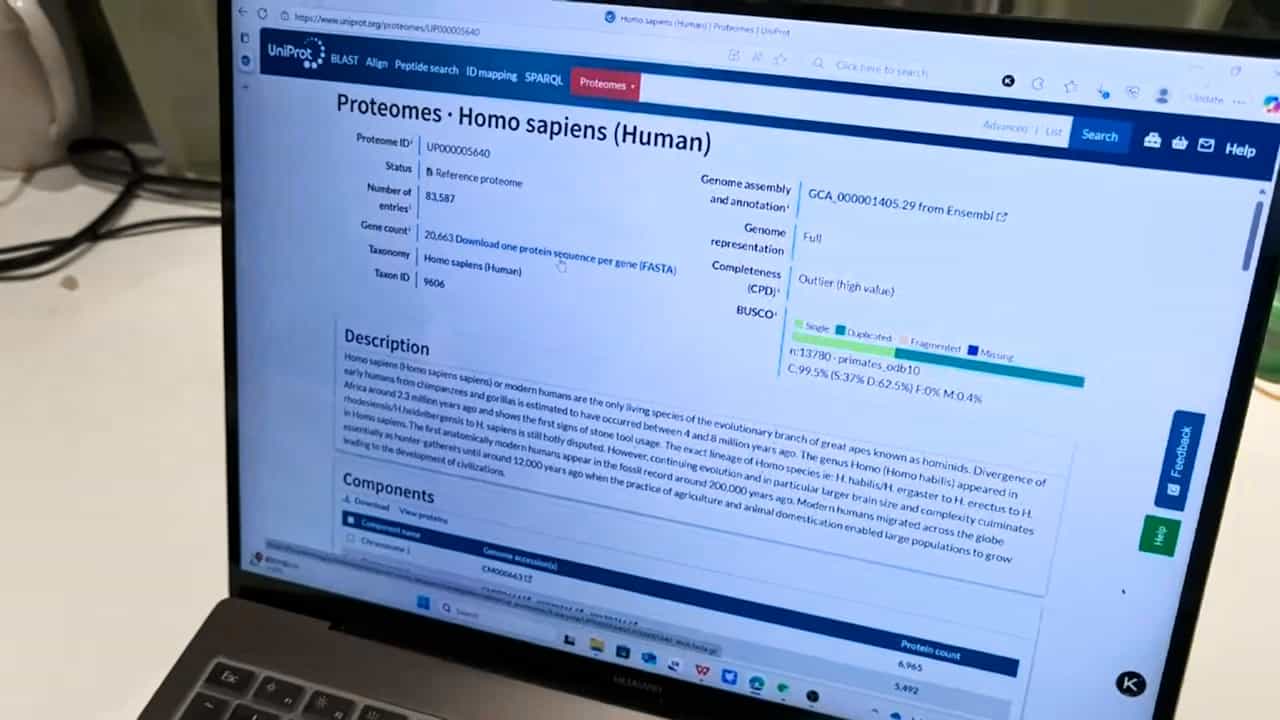

Navigating the Mass Spectrometry-Based Proteomic Data Using Free Computational Tools
Published on: August 19, 2025
MOPED enables discoveries through consistently processed proteomics data

Abstract:
The Model Organism Protein Expression Database (MOPED, http://moped.proteinspire.org) is an expanding proteomics resource to enable biological and biomedical discoveries. MOPED aggregates simple, standardized and consistently processed summaries of protein expression and metadata from proteomics (mass spectrometry) experiments from human and model organisms (mouse, worm, and yeast). The latest version of MOPED adds new estimates of protein abundance and concentration as well as relative (differential) expression data. MOPED provides a new updated query interface that allows users to explore information by organism, tissue, localization, condition, experiment, or keyword. MOPED supports the Human Proteome Project's efforts to generate chromosome- and diseases-specific proteomes by providing links from proteins to chromosome and disease information as well as many complementary resources. MOPED supports a new omics metadata checklist to harmonize data integration, analysis, and use. MOPED's development is driven by the user community, which spans 90 countries and guides future development that will transform MOPED into a multiomics resource. MOPED encourages users to submit data in a simple format. They can use the metadata checklist to generate a data publication for this submission. As a result, MOPED will provide even greater insights into complex biological processes and systems and enable deeper and more comprehensive biological and biomedical discoveries.
Insights
The Model Organism Protein Expression Database (MOPED) is an expanding proteomics resource. It provides standardized protein expression data from various organisms to aid biological and biomedical research.
Area of Science:
- Proteomics
- Bioinformatics
- Systems Biology
Background:
- The Model Organism Protein Expression Database (MOPED) serves as a crucial proteomics resource.
- It aggregates standardized protein expression and metadata from mass spectrometry experiments across human and model organisms.
Purpose of the Study:
- To enhance MOPED with new protein abundance, concentration, and differential expression data.
- To improve the query interface for easier data exploration by organism, tissue, localization, condition, experiment, or keyword.
- To support the Human Proteome Project and facilitate multi-omics data integration.
Main Methods:
- Aggregation of proteomics data from human and model organisms (mouse, worm, yeast).
- Implementation of a new query interface for comprehensive data exploration.
- Integration of links to chromosome and disease information, supporting the Human Proteome Project.
- Development of an omics metadata checklist for data harmonization.
Main Results:
- MOPED now includes updated estimates of protein abundance, concentration, and relative expression.
- An improved query interface allows for detailed exploration of proteomics data.
- Enhanced support for the Human Proteome Project and disease-specific proteomes.
- A new omics metadata checklist promotes standardized data integration and analysis.
Conclusions:
- MOPED's latest version offers expanded proteomics data and improved accessibility for biological discovery.
- Community-driven development is transforming MOPED into a multi-omics resource.
- Standardized data submission and the metadata checklist will foster deeper insights into complex biological systems.
More Related Videos
Related Concept Videos
 01:33
Proteomics
Proteomics is the study of proteomes' function. It involves the large-scale systematic study of the proteome to denote the protein complement expressed by a genome. Scientist Mark Wilkins coined the term...
 01:33
Peptide Identification Using Tandem Mass Spectrometry
This technique helps gather information regarding the protein from which the peptide was obtained and to study the peptides’ amino acid sequence. Identifying peptides from a complex mixture is an important component of the growing field of...