Related Experiment Video
Updated: May 3, 2026

Fluorescence Anisotropy as a Tool to Study Protein-protein Interactions
Published on: October 21, 2016
Does a more precise chemical description of protein-ligand complexes lead to more accurate prediction of binding
Pedro J Ballester1, Adrian Schreyer, Tom L Blundell
1European Bioinformatics Institute , Wellcome Trust Genome Campus, Hinxton - CB10 1SD, United Kingdom.

Abstract:
Predicting the binding affinities of large sets of diverse molecules against a range of macromolecular targets is an extremely challenging task. The scoring functions that attempt such computational prediction are essential for exploiting and analyzing the outputs of docking, which is in turn an important tool in problems such as structure-based drug design. Classical scoring functions assume a predetermined theory-inspired functional form for the relationship between the variables that describe an experimentally determined or modeled structure of a protein-ligand complex and its binding affinity. The inherent problem of this approach is in the difficulty of explicitly modeling the various contributions of intermolecular interactions to binding affinity. New scoring functions based on machine-learning regression models, which are able to exploit effectively much larger amounts of experimental data and circumvent the need for a predetermined functional form, have already been shown to outperform a broad range of state-of-the-art scoring functions in a widely used benchmark. Here, we investigate the impact of the chemical description of the complex on the predictive power of the resulting scoring function using a systematic battery of numerical experiments. The latter resulted in the most accurate scoring function to date on the benchmark. Strikingly, we also found that a more precise chemical description of the protein-ligand complex does not generally lead to a more accurate prediction of binding affinity. We discuss four factors that may contribute to this result: modeling assumptions, codependence of representation and regression, data restricted to the bound state, and conformational heterogeneity in data.

Related Concept Videos
 02:40
Ligand Binding Sites
Protein-ligand interactions are quite specific; even though numerous potential ligands surround a cellular protein at any given time, only a particular ligand can bind to that protein. Moreover, a ligand binds only to a dedicated area on the surface of the protein, known as the...
02:40Ligand Binding Sites
 02:18
The Equilibrium Binding Constant and Binding Strength
02:18The Equilibrium Binding Constant and Binding Strength
 01:49
Conserved Binding Sites
Binding sites are often located in large pockets, and if their location on a protein’s surface is unknown, it can be predicted using various approaches. The energetic method computationally...
 01:22
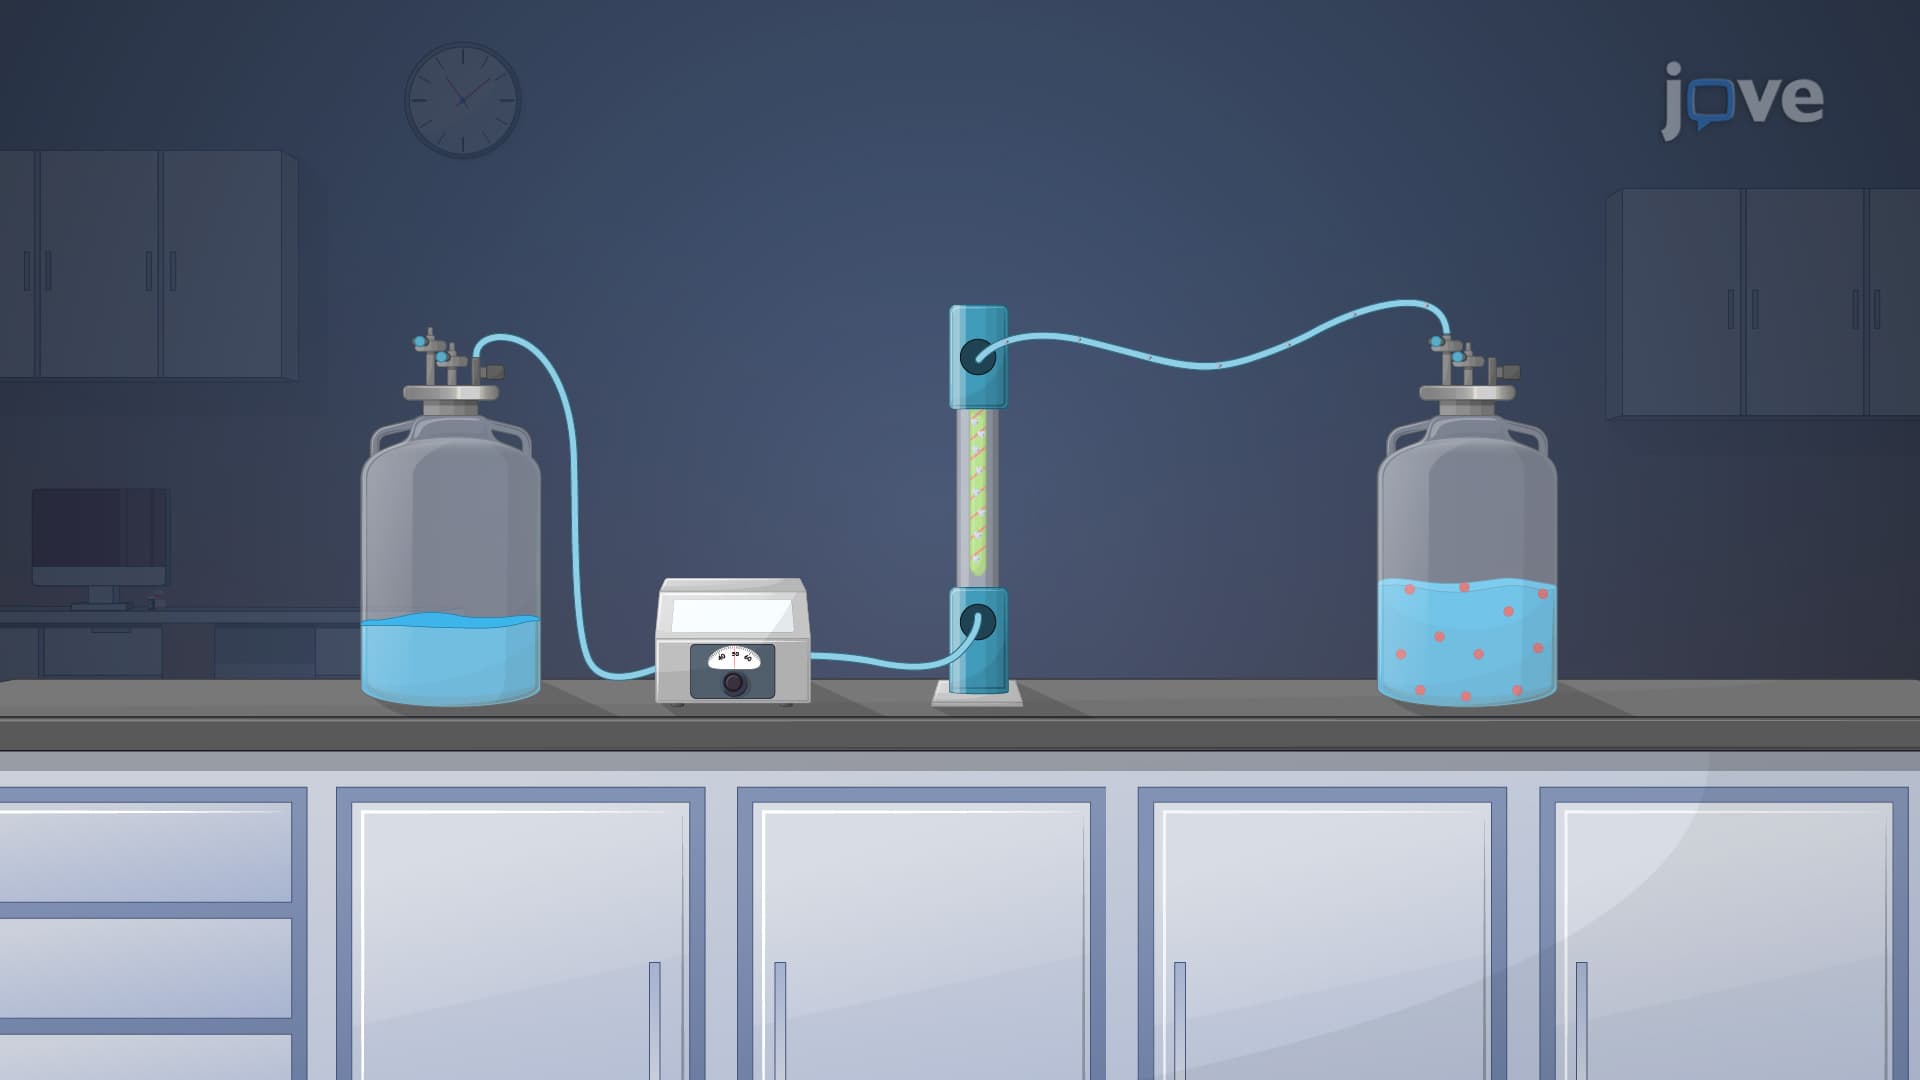
Protein-Drug Binding: Determination Methods
Indirect methods involve isolating the bound drug from its free form in biological samples such as blood, serum, or plasma. These techniques aim to measure the percentage of drugs bound to proteins. Equilibrium dialysis is a commonly used method where the free drug concentration at equilibrium is measured by separating the bound...