Lessons learned in replicating data-driven experiments in multiple medical systems and patient populations
Related Experiment Video
Updated: May 2, 2026
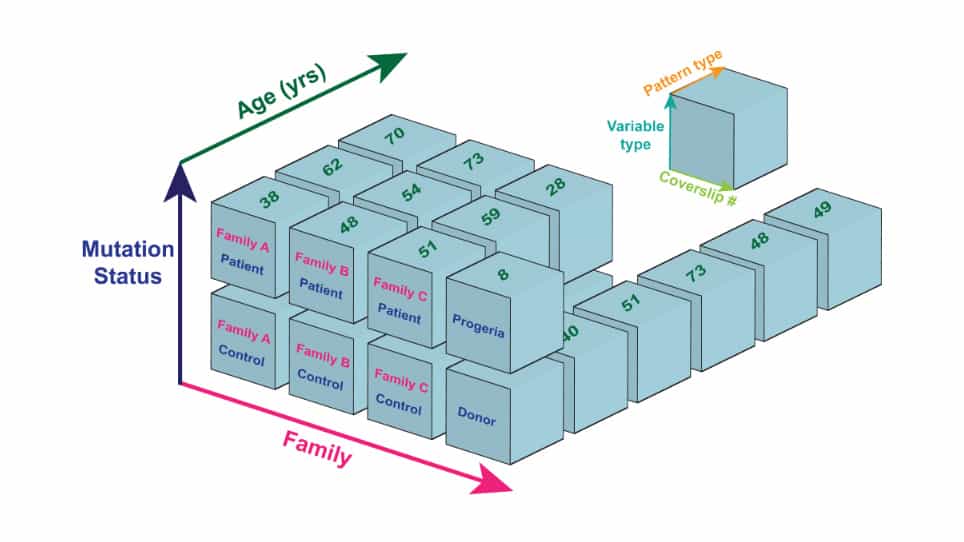
Databases to Efficiently Manage Medium Sized, Low Velocity, Multidimensional Data in Tissue Engineering
Published on: November 22, 2019
Samantha Kleinberg1, Noémie Elhadad2
1Stevens Institute of Technology, Hoboken, NJ;

Abstract:
Electronic health records are an increasingly important source of data for research, allowing for large-scale longitudinal studies on the same population that is being treated. Unlike in controlled studies, though, these data vary widely in quality, quantity, and structure. In order to know whether algorithms can accurately uncover new knowledge from these records, or whether findings can be extrapolated to new populations, they must be validated. One approach is to conduct the same study in multiple sites and compare results, but it is a challenge to determine whether differences are due to artifacts of the medical process, population differences, or failures of the methods used. In this paper we describe the results of replicating a data-driven experiment to infer possible causes of congestive heart failure and their timing using data from two medical systems and two patient populations. We focus on the difficulties faced in this type of work, lessons learned, and recommendations for future research.
Related Concept Videos
 01:13
Data Collection by Experiments
An example of the experimental method is a public...
 01:15
Bioequivalence Experimental Study Designs: Repeated Measures, Cross-Over, Carry-Over, and Latin Square Designs
 01:16
Crossover Experiments
Crossover designs are performed even with smaller sample sizes since the samples can act as their controls. These are better than simple randomized trials since patients are exposed to all the treatments.
 01:12
Analysis of Population Pharmacokinetic Data
 01:15
Bioavailability Study Design: Healthy Subjects Versus Patients
 01:15
Methods of Documentation VI: Case Management Model
For example, a patient with a chronic...