Related Experiment Video
Updated: May 2, 2026

A Knowledge Graph Approach to Elucidate the Role of Organellar Pathways in Disease via Biomedical Reports
Published on: October 13, 2023
Inferring the semantic relationships of words within an ontology using random indexing: applications to
Bethany Percha1, Russ B Altman1
1Stanford University, Stanford, CA.

Abstract:
The biomedical literature presents a uniquely challenging text mining problem. Sentences are long and complex, the subject matter is highly specialized with a distinct vocabulary, and producing annotated training data for this domain is time consuming and expensive. In this environment, unsupervised text mining methods that do not rely on annotated training data are valuable. Here we investigate the use of random indexing, an automated method for producing vector-space semantic representations of words from large, unlabeled corpora, to address the problem of term normalization in sentences describing drugs and genes. We show that random indexing produces similarity scores that capture some of the structure of PHARE, a manually curated ontology of pharmacogenomics concepts. We further show that random indexing can be used to identify likely word candidates for inclusion in the ontology, and can help localize these new labels among classes and roles within the ontology.
More Related Videos
 07:40
A Data Integration Workflow to Identify Drug Combinations Targeting Synthetic Lethal Interactions
Published on: May 27, 2021
 05:47
Evidence-based Knowledge Synthesis and Hypothesis Validation: Navigating Biomedical Knowledge Bases via Explainable AI and Agentic Systems
Published on: June 13, 2025
Related Concept Videos
 01:29
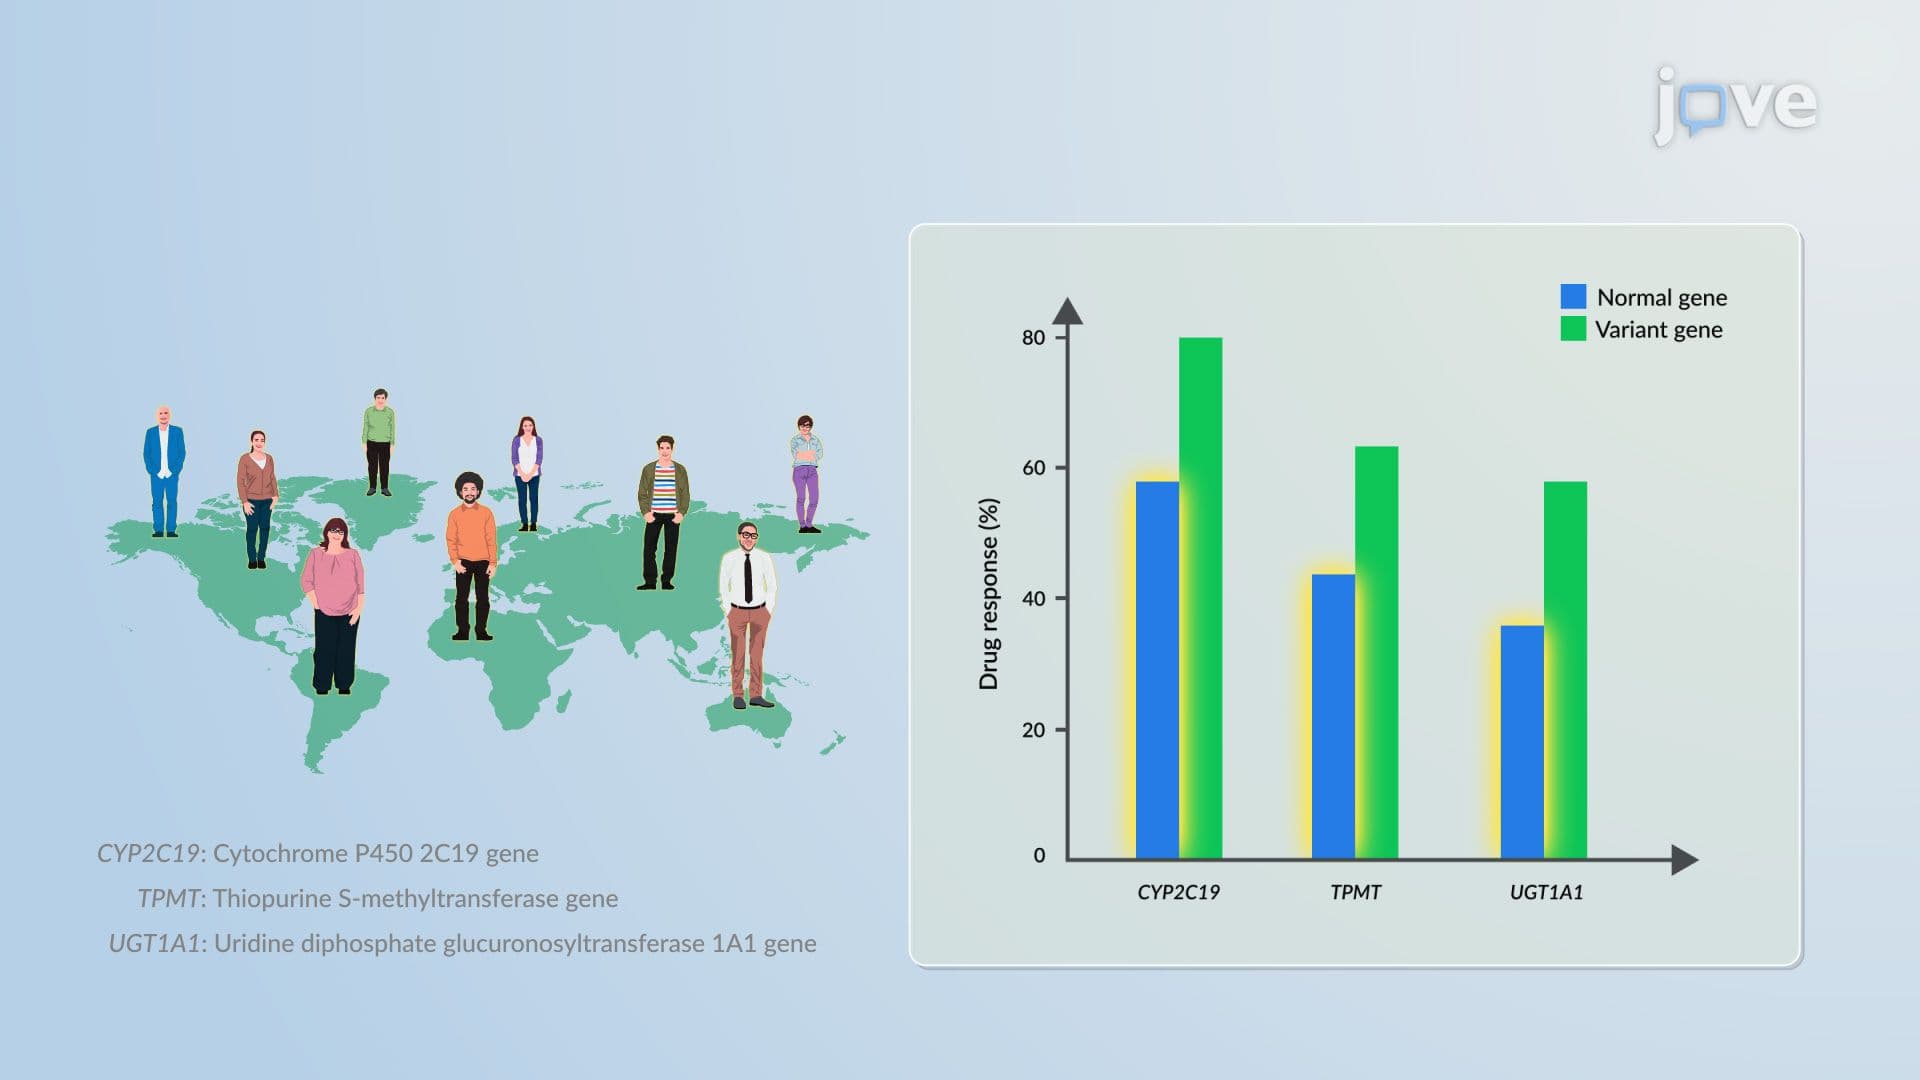
Pharmacogenetics and Pharmacogenomics: Overview
 01:29
Pharmacogenomics: Identification of New Drug Targets
 01:29
Pharmacogenetic Phenotypes: Alterations in Pharmacokinetics, Drug Targets and Biologic Milieu
 01:12
Analysis of Population Pharmacokinetic Data
 01:27
Pharmacogenetics of Drug Metabolism: Overview
 01:27
Principles of Pharmacogenetics: Types of Genetic Variants