Related Experiment Video
Updated: May 2, 2026
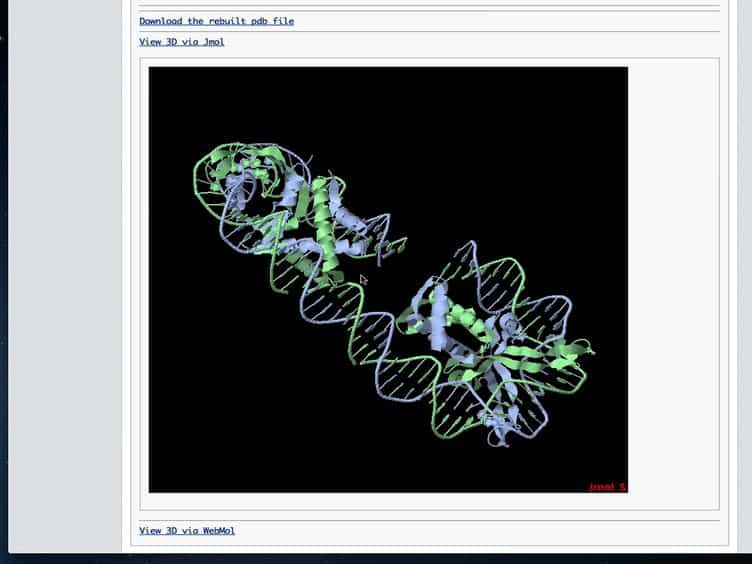

Analyzing and Building Nucleic Acid Structures with 3DNA
Published on: April 26, 2013
A novel technique for analyzing the similarity and dissimilarity of DNA sequences

Abstract:
l(i,j) denotes the distance between the point (xi, yi) and the point (xj, yi) in graphical representation. By classifying li,j, i, j = 1, 2,…, N according to the number of points between (xi, yi) and (xj, yi), N - 1 types are obtained. The average and variance of every type are assembled by the novel invariant v = (a1, d1, a2, d2,…, aN, d>N). Compared with the traditional invariants, the leading eigenvalue, the max-min (eigenvalue), the leading eigenvalue/N, the average matrix element, and the average row sum, this strategy complies with the rule of using the average, extracts more information about biological sequences, and reduces the amounts of computation. It is superior to the traditional invariants in predicting similarity and dissimilarity among different species.
Related Concept Videos
 02:54
Evolutionary Relationships through Genome Comparisons
 01:29
Modern Molecular Taxonomy
 01:57
Sanger Sequencing
 01:20
Applications of Molecular Taxonomy
 01:05
Maxam-Gilbert Sequencing
Challenges of the Maxam-Gilbert Method
The...
 02:57
Southern Blot
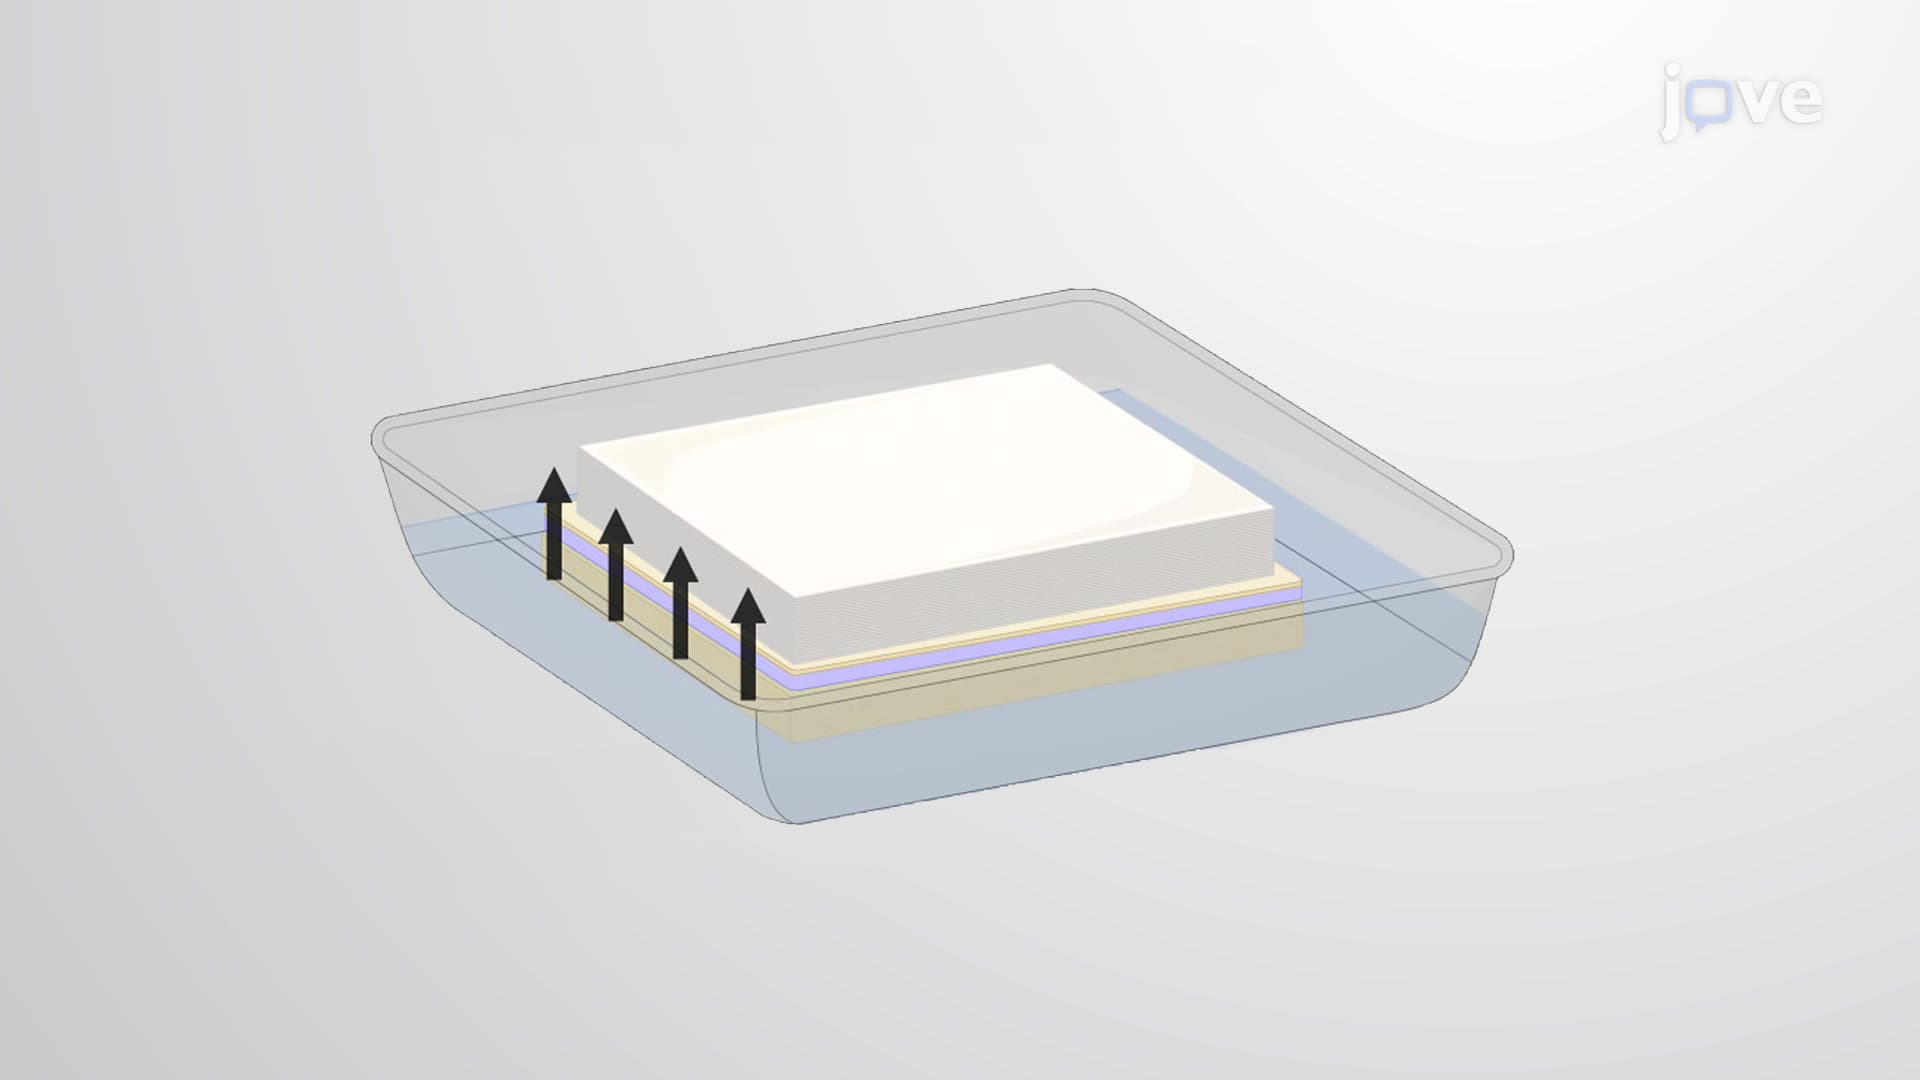
Denatured DNA fragments must be transferred onto a carrier membrane from the gel to make it accessible to a probe - a small ssDNA fragment complementary to the target DNA...