Protein side-chain modeling with a protein-dependent optimized rotamer library
Related Experiment Video
Updated: May 2, 2026
Protein WISDOM: A Workbench for In silico De novo Design of BioMolecules
Published on: July 25, 2013
Patricia Francis-Lyon1, Patrice Koehl
1Department of Computer Science, University of San Francisco, San Francisco, California, 94117.

Abstract:
Despite years of effort, the problem of predicting the conformations of protein side chains remains a subject of inquiry. This problem has three major issues, namely defining the conformations that a side chain may adopt within a protein, developing a sampling procedure for generating possible side-chain packings, and defining a scoring function that can rank these possible packings. To solve the former of these issues, most procedures rely on a rotamer library derived from databases of known protein structures. We introduce an alternative method that is free of statistics. We begin with a rotamer library that is based only on stereochemical considerations; this rotamer library is then optimized independently for each protein under study. We show that this optimization step restores the diversity of conformations observed in native proteins. We combine this protein-dependent rotamer library (PDRL) method with the self-consistent mean field (SCMF) sampling approach and a physics-based scoring function into a new side-chain prediction method, SCMF-PDRL. Using two large test sets of 831 and 378 proteins, respectively, we show that this new method compares favorably with competing methods such as SCAP, OPUS-Rota, and SCWRL4 for energy-minimized structures.
More Related Videos
 06:50
Author Spotlight: A Computational Approach to Decipher Amino Acid Preferences in Multispecific Protein-Protein Interactions
Published on: January 26, 2024
 05:57
Author Spotlight: In Silico Creation and Impact of Carbonylated Amino Acids on Protein Structure and Function
Published on: April 26, 2024
Related Concept Videos
 01:24
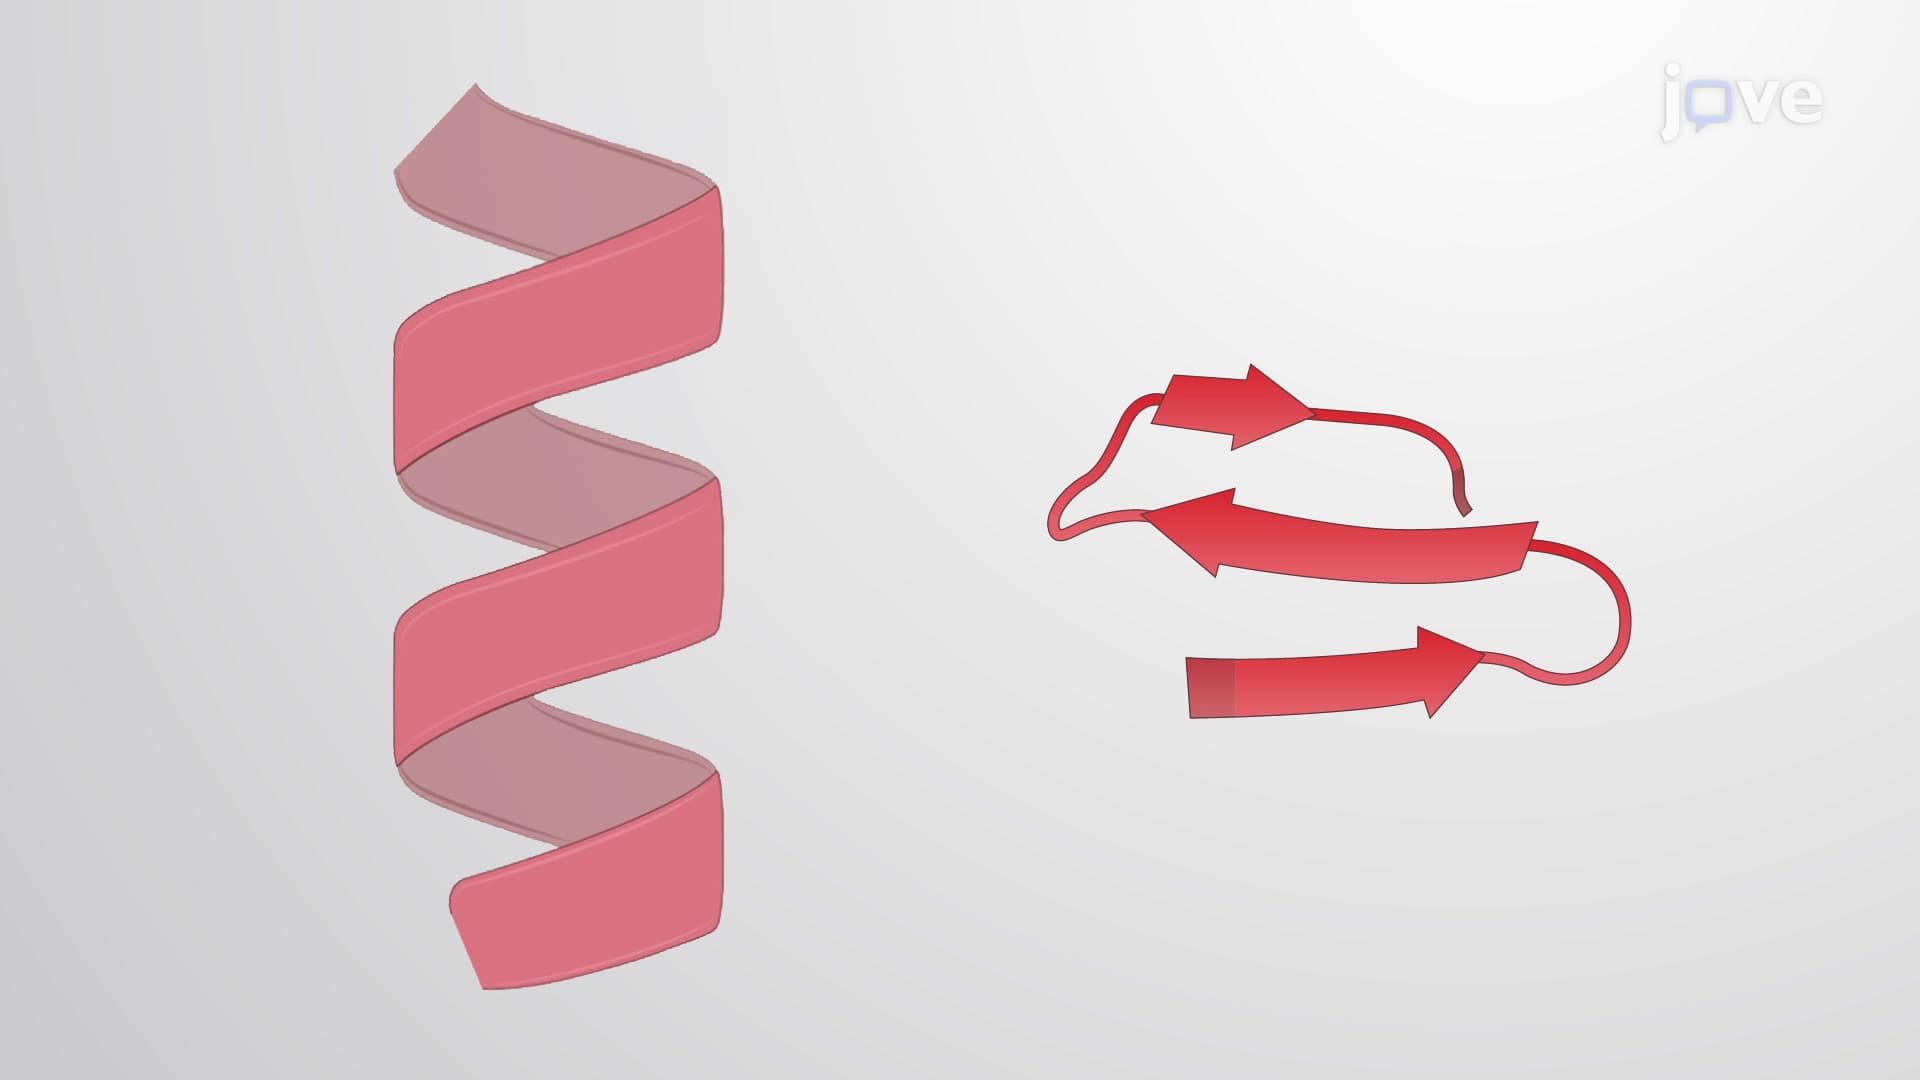
Protein Organization
The primary structure of a protein is its amino acid sequence....
 01:49
Conserved Binding Sites
Binding sites are often located in large pockets, and if their location on a protein’s surface is unknown, it can be predicted using various approaches. The energetic method computationally...
01:49Conserved Binding Sites
 01:13
Induced-fit Model
Enzymes exhibit substrate specificity, meaning that they can only bind to certain substrates. This is mainly determined by the shape and chemical...
 02:40
Ligand Binding Sites
Protein-ligand interactions are quite specific; even though numerous potential ligands surround a cellular protein at any given time, only a particular ligand can bind to that protein. Moreover, a ligand binds only to a dedicated area on the surface of the protein, known as the...
 01:22
Protein Folding