DAFS: a data-adaptive flag method for RNA-sequencing data to differentiate genes with low and high expression
Related Experiment Video
Updated: May 1, 2026
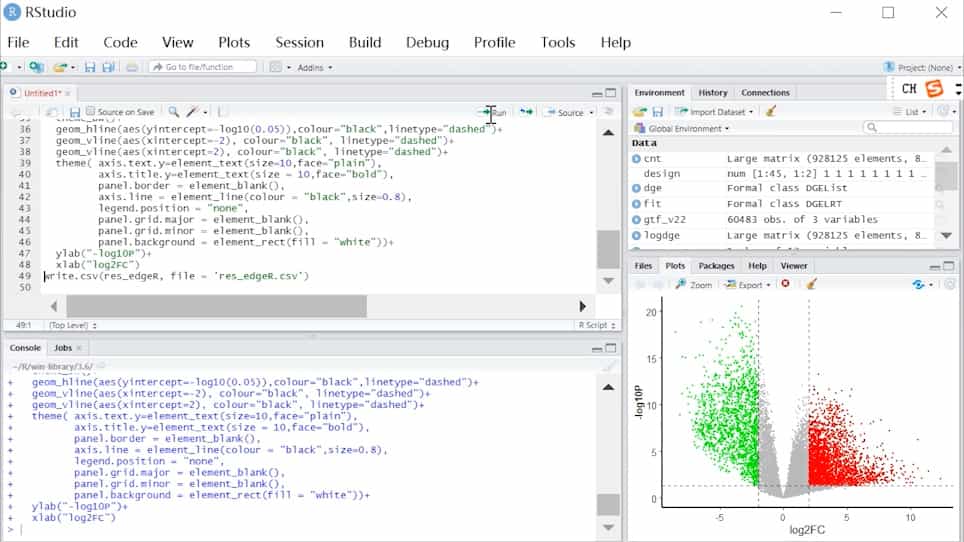
Three Differential Expression Analysis Methods for RNA Sequencing: limma, EdgeR, DESeq2
Published on: September 18, 2021
Nysia I George, Ching-Wei Chang1
1Division of Bioinformatics and Biostatistics, National Center for Toxicological Research, FDA, Jefferson, AR 72079, USA. Ching-Wei.Chang@fda.hhs.gov.

Background:
Next-generation sequencing (NGS) has advanced the application of high-throughput sequencing technologies in genetic and genomic variation analysis. Due to the large dynamic range of expression levels, RNA-seq is more prone to detect transcripts with low expression. It is clear that genes with no mapped reads are not expressed; however, there is ongoing debate about the level of abundance that constitutes biologically meaningful expression. To date, there is no consensus on the definition of low expression. Since random variation is high in regions with low expression and distributions of transcript expression are affected by numerous experimental factors, methods to differentiate low and high expressed data in a sample are critical to interpreting classes of abundance levels in RNA-seq data.
Results:
A data-adaptive approach was developed to estimate the lower bound of high expression for RNA-seq data. The Kolmgorov-Smirnov statistic and multivariate adaptive regression splines were used to determine the optimal cutoff value for separating transcripts with high and low expression. Results from the proposed method were compared to results obtained by estimating the theoretical cutoff of a fitted two-component mixture distribution. The robustness of the proposed method was demonstrated by analyzing different RNA-seq datasets that varied by sequencing depth, species, scale of measurement, and empirical density shape.
Conclusions:
The analysis of real and simulated data presented here illustrates the need to employ data-adaptive methodology in lieu of arbitrary cutoffs to distinguish low expressed RNA-seq data from high expression. Our results also present the drawbacks of characterizing the data by a two-component mixture distribution when classes of gene expression are not well separated. The ability to ascertain stably expressed RNA-seq data is essential in the filtering process of data analysis, and methodologies that consider the underlying data structure demonstrate superior performance in preserving most of the interpretable and meaningful data. The proposed algorithm for classifying low and high regions of transcript abundance promises wide-range application in the continuing development of RNA-seq analysis.
Related Concept Videos
 03:21
RNA-seq
Before the discovery of RNA-seq, microarray-based methods and Sanger sequencing were used for transcriptome analysis. However, while...
 02:34
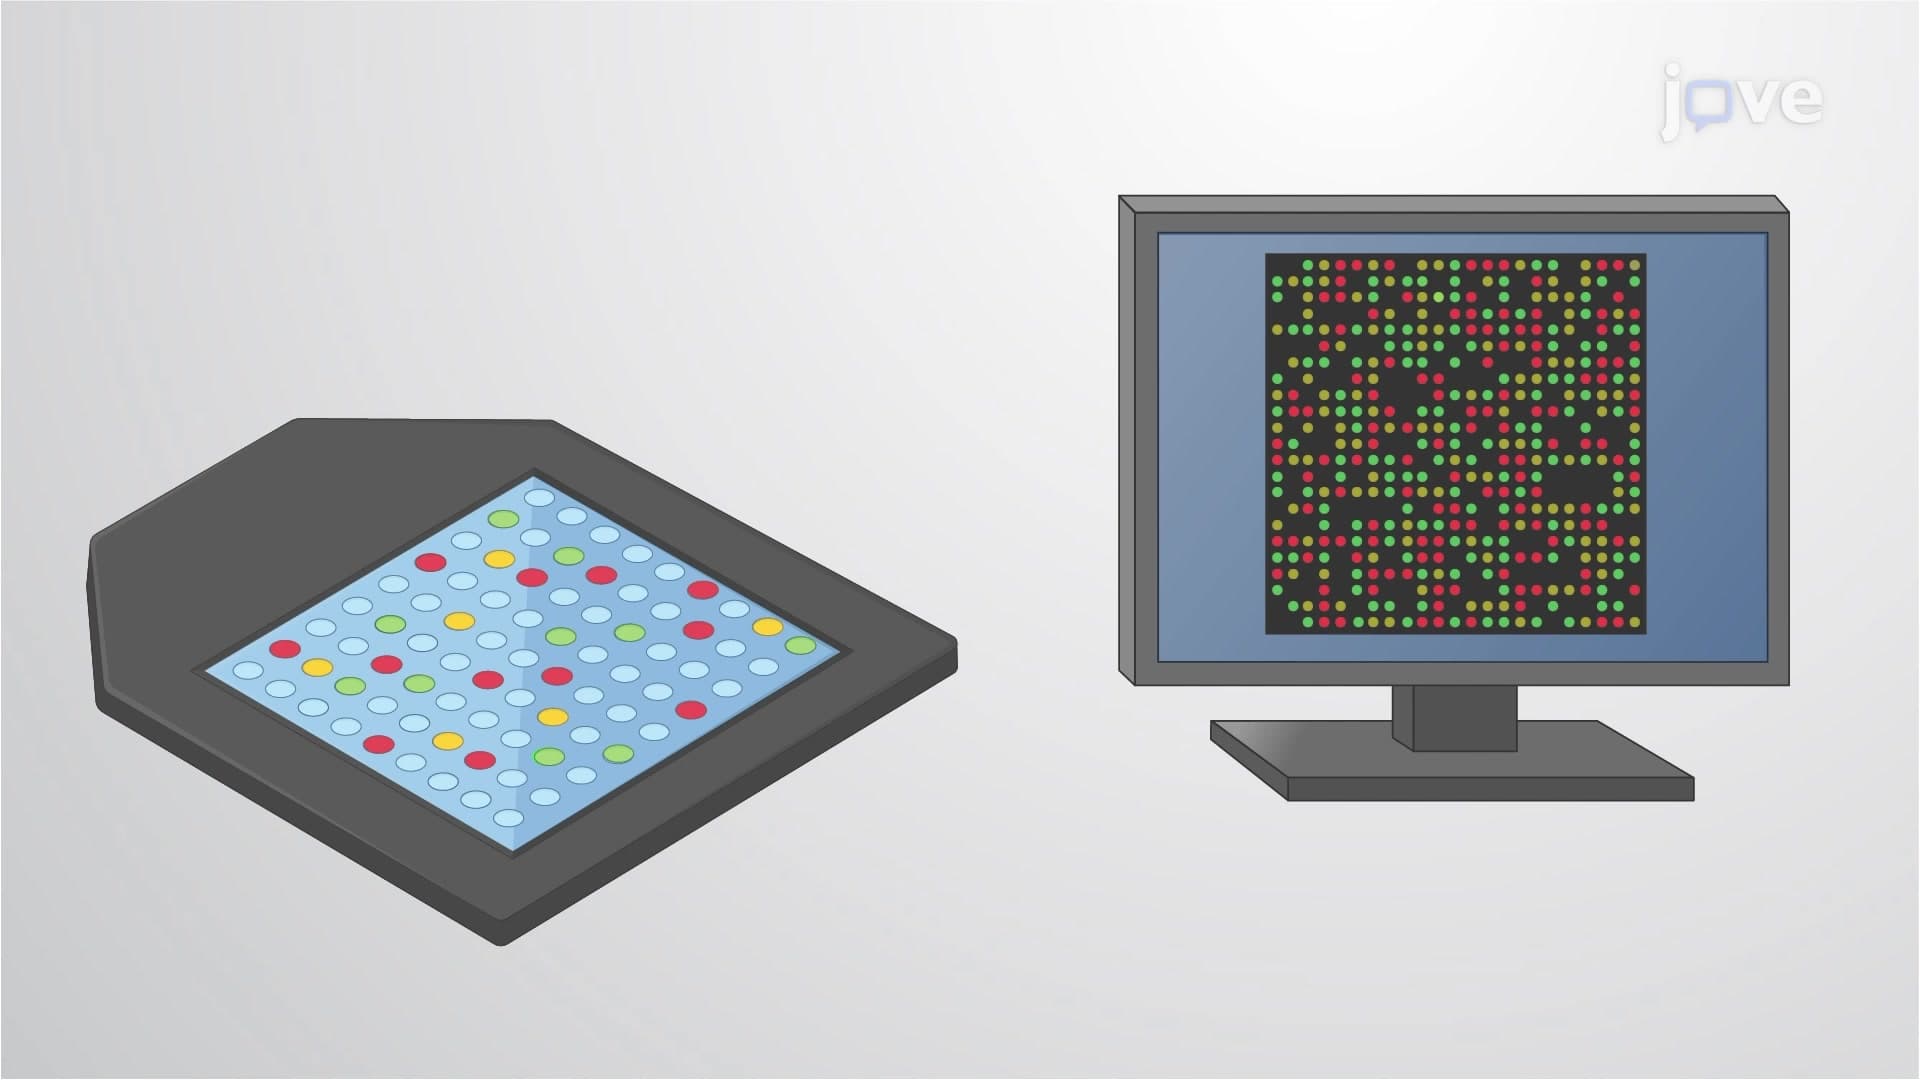
DNA Microarrays
 02:24
Ribosome Profiling
Applications of ribosome profiling
Ribosome profiling has many applications, including in vivo monitoring of translation inside a particular organ or tissue type and quantifying new protein synthesis levels.
The technique...