Related Experiment Video
Updated: Apr 30, 2026


Author Spotlight: Impact of Intergenic Interactions on Disease-Identifying Dark Biomarkers
Published on: March 1, 2024
Fractional norm regularization: learning with very few relevant features

Abstract:
Learning in the presence of a large number of irrelevant features is an important problem in high-dimensional tasks. Previous studies have shown that L1-norm regularization can be effective in such cases while L2-norm regularization is not. Furthermore, work in compressed sensing suggests that regularization by nonconvex (e.g., fractional) semi-norms may outperform L1-regularization. However, for classification it is largely unclear when this may or may not be the case. In addition, the nonconvex problem is harder to solve than the convex L1 problem. In this paper, we provide a more in-depth analysis to elucidate the potential advantages and pitfalls of nonconvex regularization in the context of logistic regression where the regularization term employs the family of Lq semi-norms. First, using results from the phenomenon of concentration of norms and distances in high dimensions, we gain intuition about the working of sparse estimation when the dimensionality is very high. Second, using the probably approximately correct (PAC)-Bayes methodology, we give a data-dependent bound on the generalization error of Lq-regularized logistic regression, which is applicable to any algorithm that implements this model, and may be used to predict its generalization behavior from the training set alone. Third, we demonstrate the usefulness of our approach by experiments and applications, where the PAC-Bayes bound is used to guide the choice of semi-norm in the regularization term. The results support the conclusion that the optimal choice of regularization depends on the relative fraction of relevant versus irrelevant features, and a fractional norm with a small exponent is most suitable when the fraction of relevant features is very small.
Related Concept Videos
 01:28
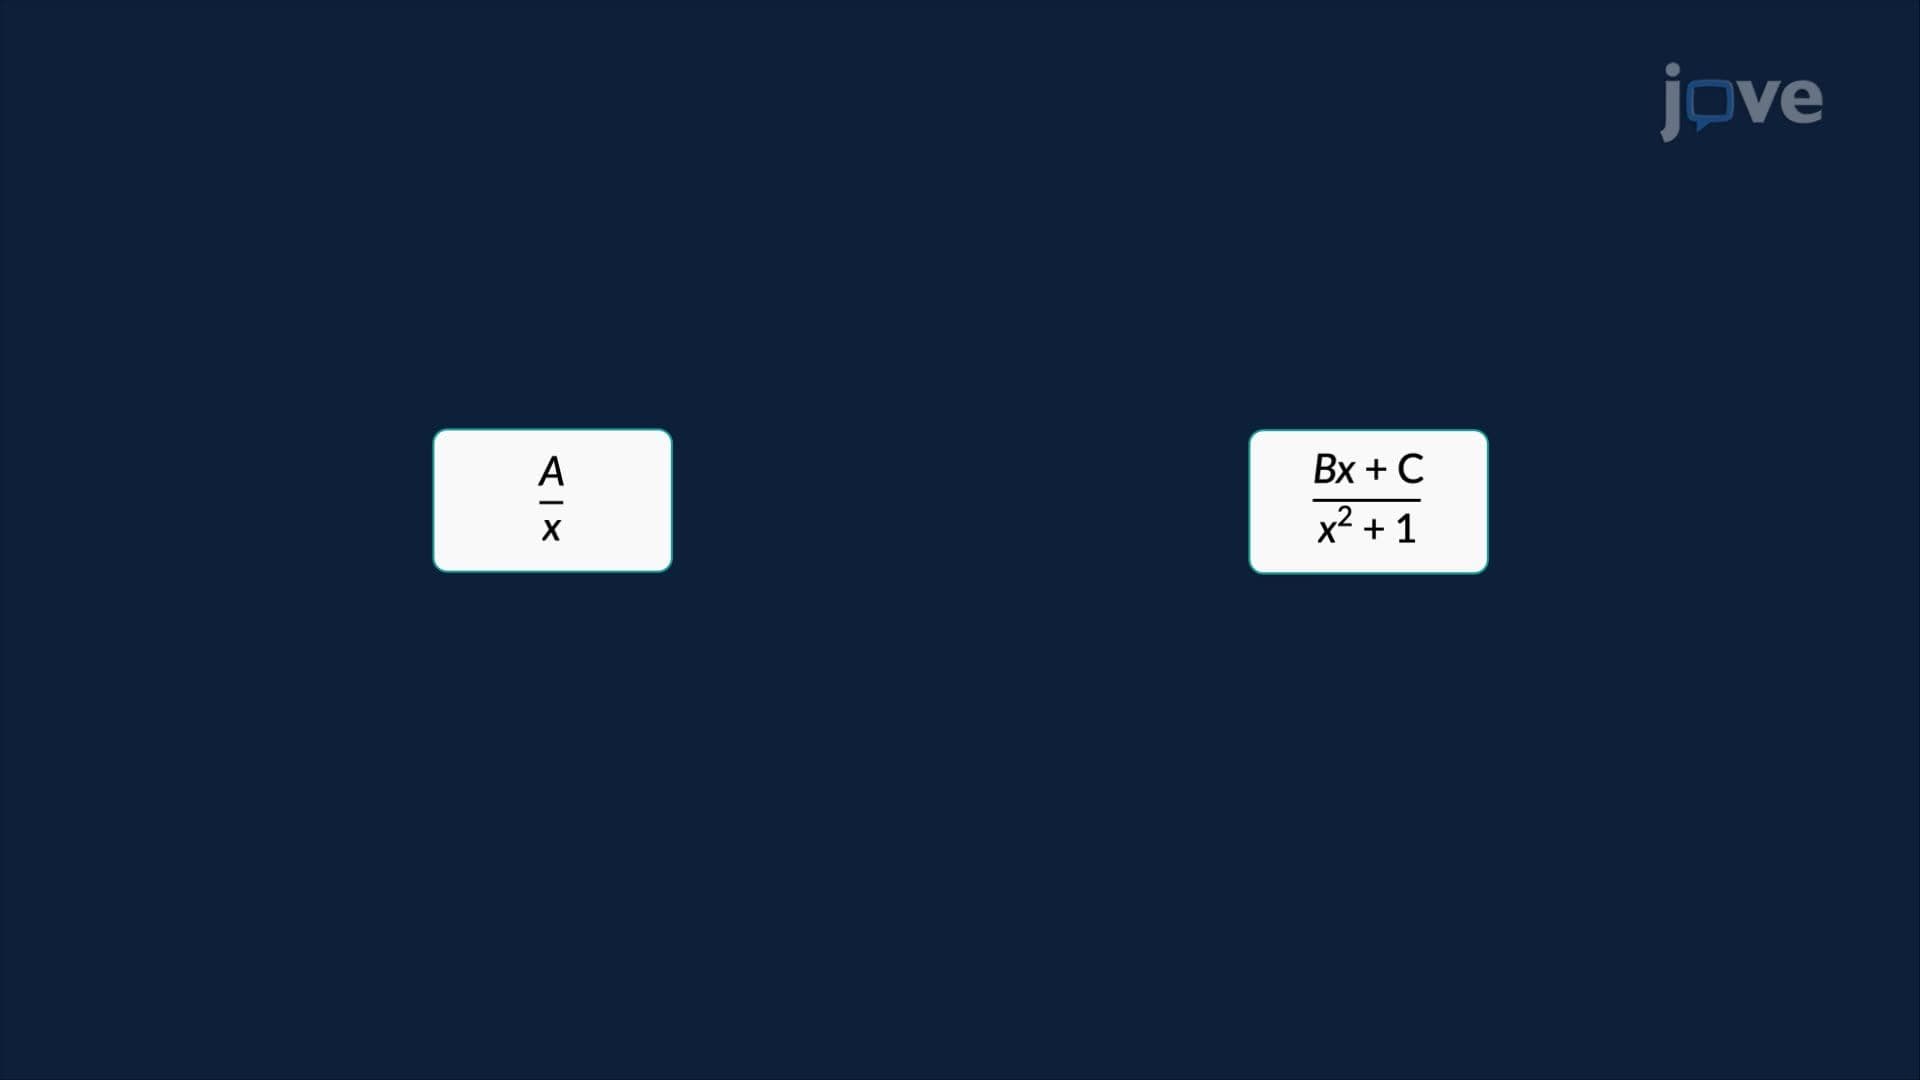
Partial Fractions
 01:26
Linear Approximation in Frequency Domain
In contrast, nonlinear systems do not inherently possess these properties. However, for small deviations around an operating point, a nonlinear system can often be approximated as linear....
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:29
Application of Linearization and Approximation
 01:26
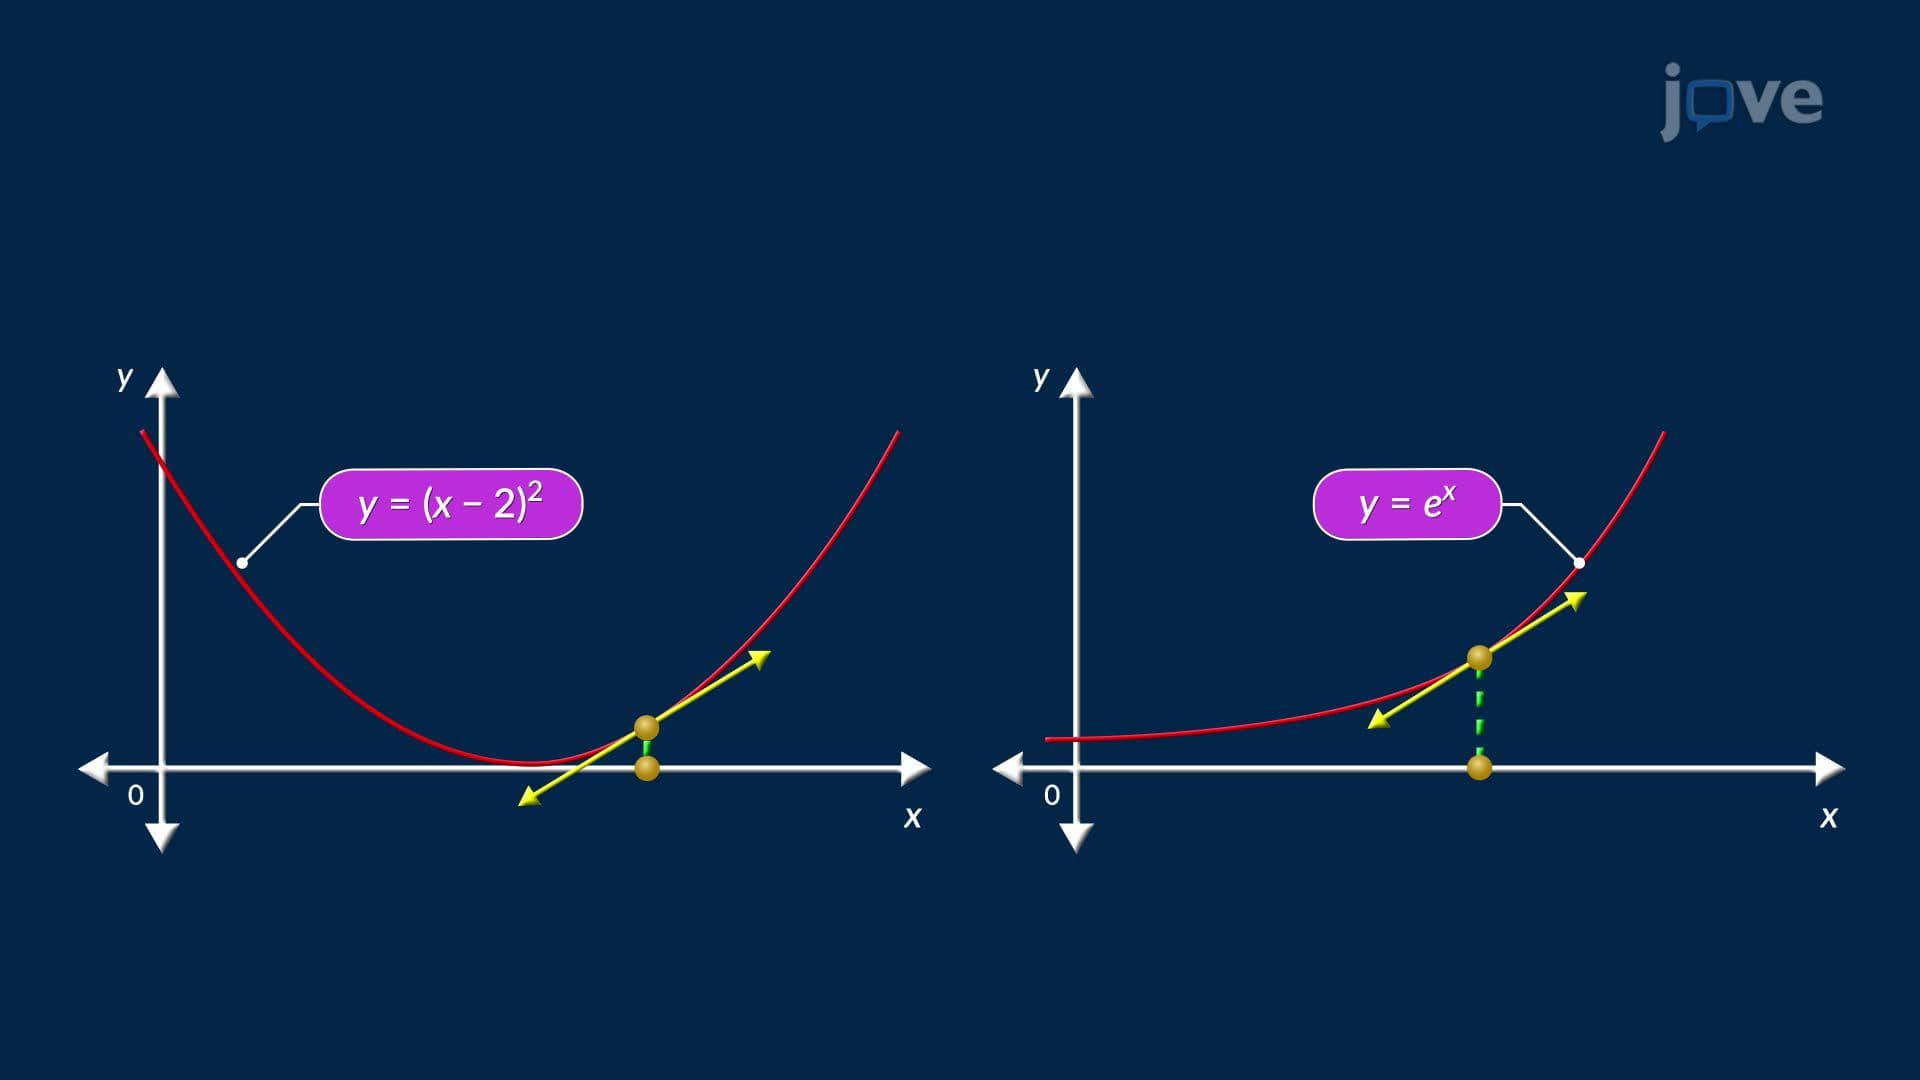
Linearization and Approximation
 01:29
Mechanistic Models: Compartment Models in Algorithms for Numerical Problem Solving
In individual population analyses, different algorithms are employed, such as Cauchy's method, which uses a...