Related Experiment Video
Updated: Apr 28, 2026
Using Cholesky Decomposition to Explore Individual Differences in Longitudinal Relations between Reading Skills
Published on: September 17, 2019
Individual prediction regions for multivariate longitudinal data with small samples
1INRA-ENVT, UMR1331 Toxalim Research Centre in Food Toxicology, Université de Toulouse, F-31027 Toulouse, France.

Abstract:
Follow-up is more and more used in medicine/doping control to identify abnormal results in an individual. Currently, follow-ups are mostly carried out variable by variable using "reference intervals" that contain the values observable in 100(1-α)% of healthy/undoped individuals. Observations of the evolution of the variables over time in a sample of N healthy/undoped individuals, allows these reference intervals to be individualized by taking into account the possible effect of covariables and some previous observations of these variables obtained when the individual was healthy/undoped. For each variable these individualized intervals should contain 100(1-α)% of observable values compatible with previous observed values in this individual. General methods to build these intervals are available, but they allow only a variable by variable follow-up whatever the possible correlations over time between them. In this article, we propose a general method to jointly follow-up several correlated variables over time. This methodology relies on a multivariate linear mixed effects model. We first provide a method to estimate the model's parameters. In an asymptotic framework (N large enough), we then derive a (1-α) individualized prediction region. Sometimes, the sample size N is not large enough for the asymptotic framework to give a reasonable prediction region. It is for this reason, we propose and compare three different prediction regions that should behave better for small N. Finally, the whole methodology is illustrated by the follow-up of kidney insufficiency in cats.
Related Concept Videos
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
 01:26
Longitudinal Studies
 01:19
Survival Tree
Building a Survival Tree
Constructing a...
 01:25
Multiple Regression
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
 01:52
Regression Toward the Mean
 01:19
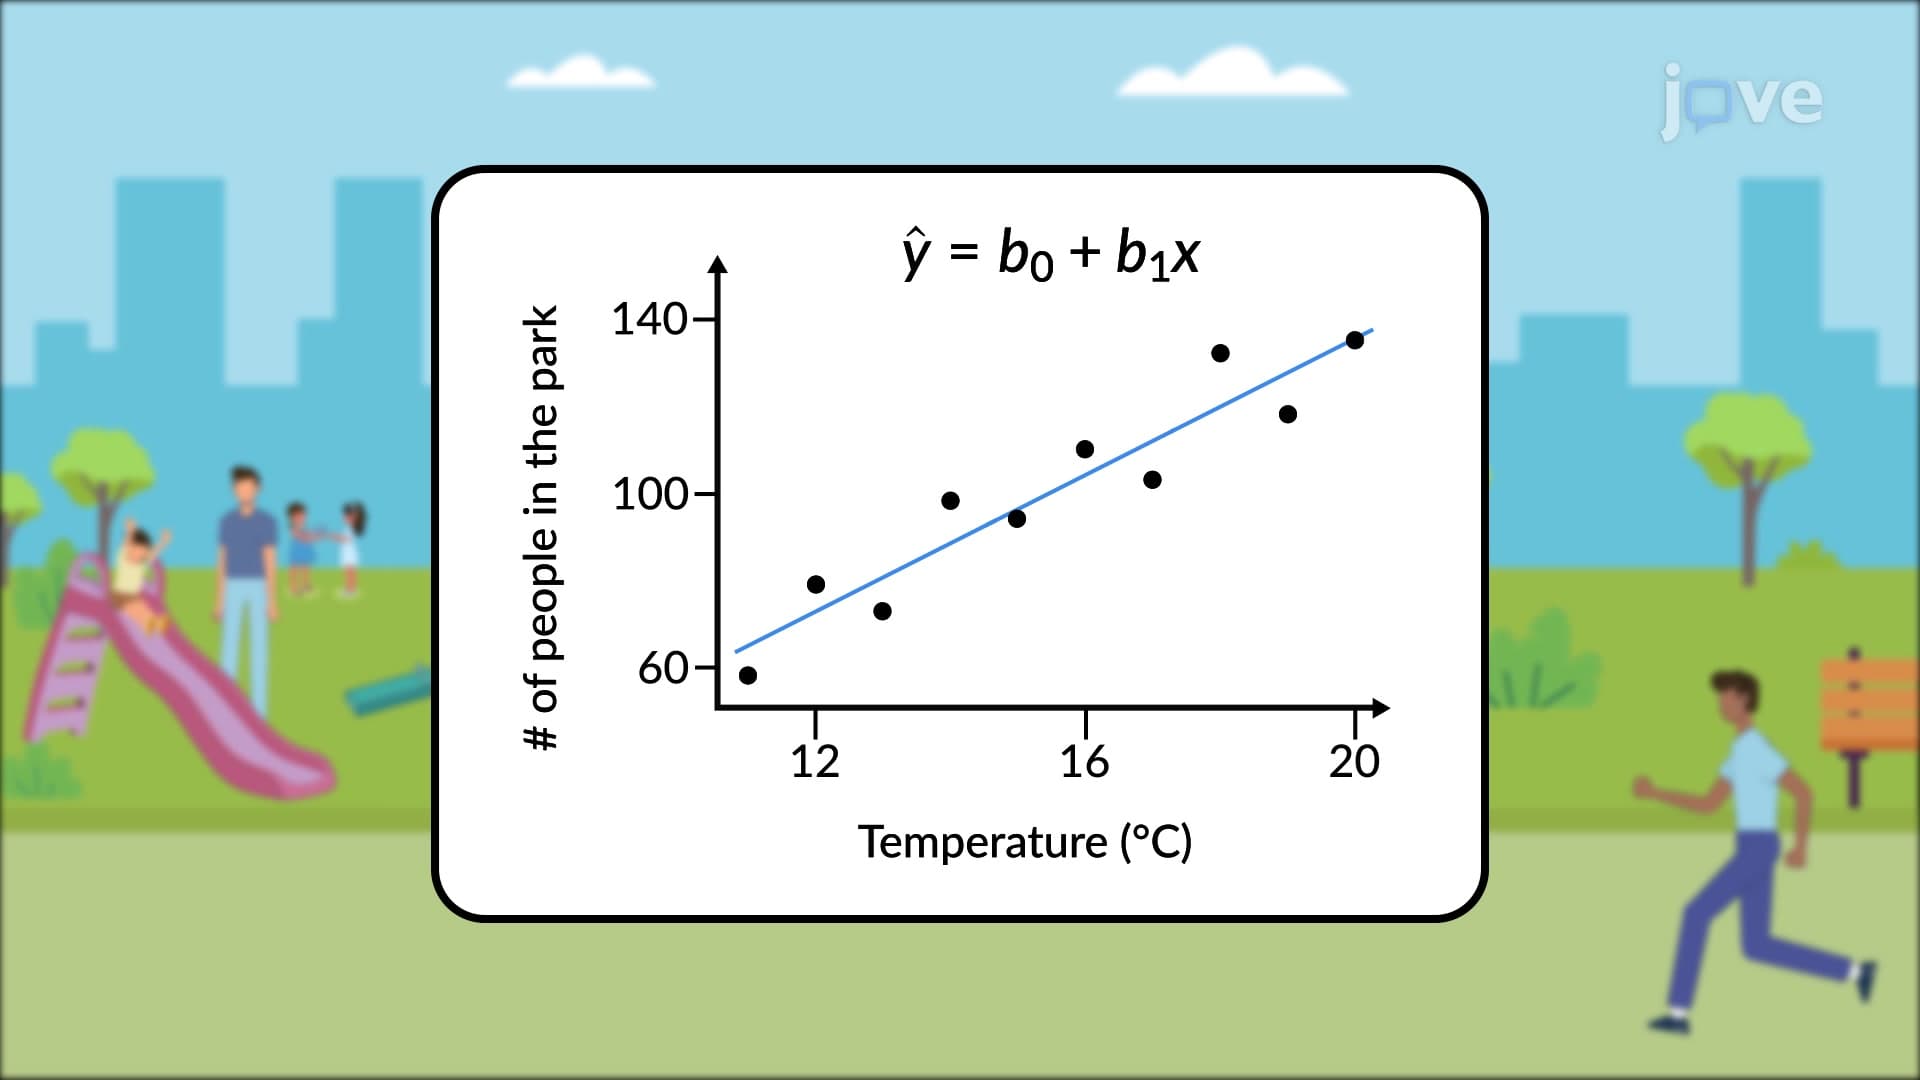
Variation
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...