Related Experiment Videos
Differentially private distributed logistic regression using private and public data

Background:
Privacy protecting is an important issue in medical informatics and differential privacy is a state-of-the-art framework for data privacy research. Differential privacy offers provable privacy against attackers who have auxiliary information, and can be applied to data mining models (for example, logistic regression). However, differentially private methods sometimes introduce too much noise and make outputs less useful. Given available public data in medical research (e.g. from patients who sign open-consent agreements), we can design algorithms that use both public and private data sets to decrease the amount of noise that is introduced.
Methodology:
In this paper, we modify the update step in Newton-Raphson method to propose a differentially private distributed logistic regression model based on both public and private data.
Experiments And Results:
We try our algorithm on three different data sets, and show its advantage over: (1) a logistic regression model based solely on public data, and (2) a differentially private distributed logistic regression model based on private data under various scenarios.
Conclusion:
Logistic regression models built with our new algorithm based on both private and public datasets demonstrate better utility than models that trained on private or public datasets alone without sacrificing the rigorous privacy guarantee.
Related Concept Videos
 01:06
Model Approaches for Pharmacokinetic Data: Distributed Parameter Models
The distributed parameter models are specifically designed to account for variations and differences in some drug classes. This model is particularly useful for assessing regional concentrations of anticancer or...
 01:12
Analysis of Population Pharmacokinetic Data
 01:26
Distributions to Estimate Population Parameter
 01:27
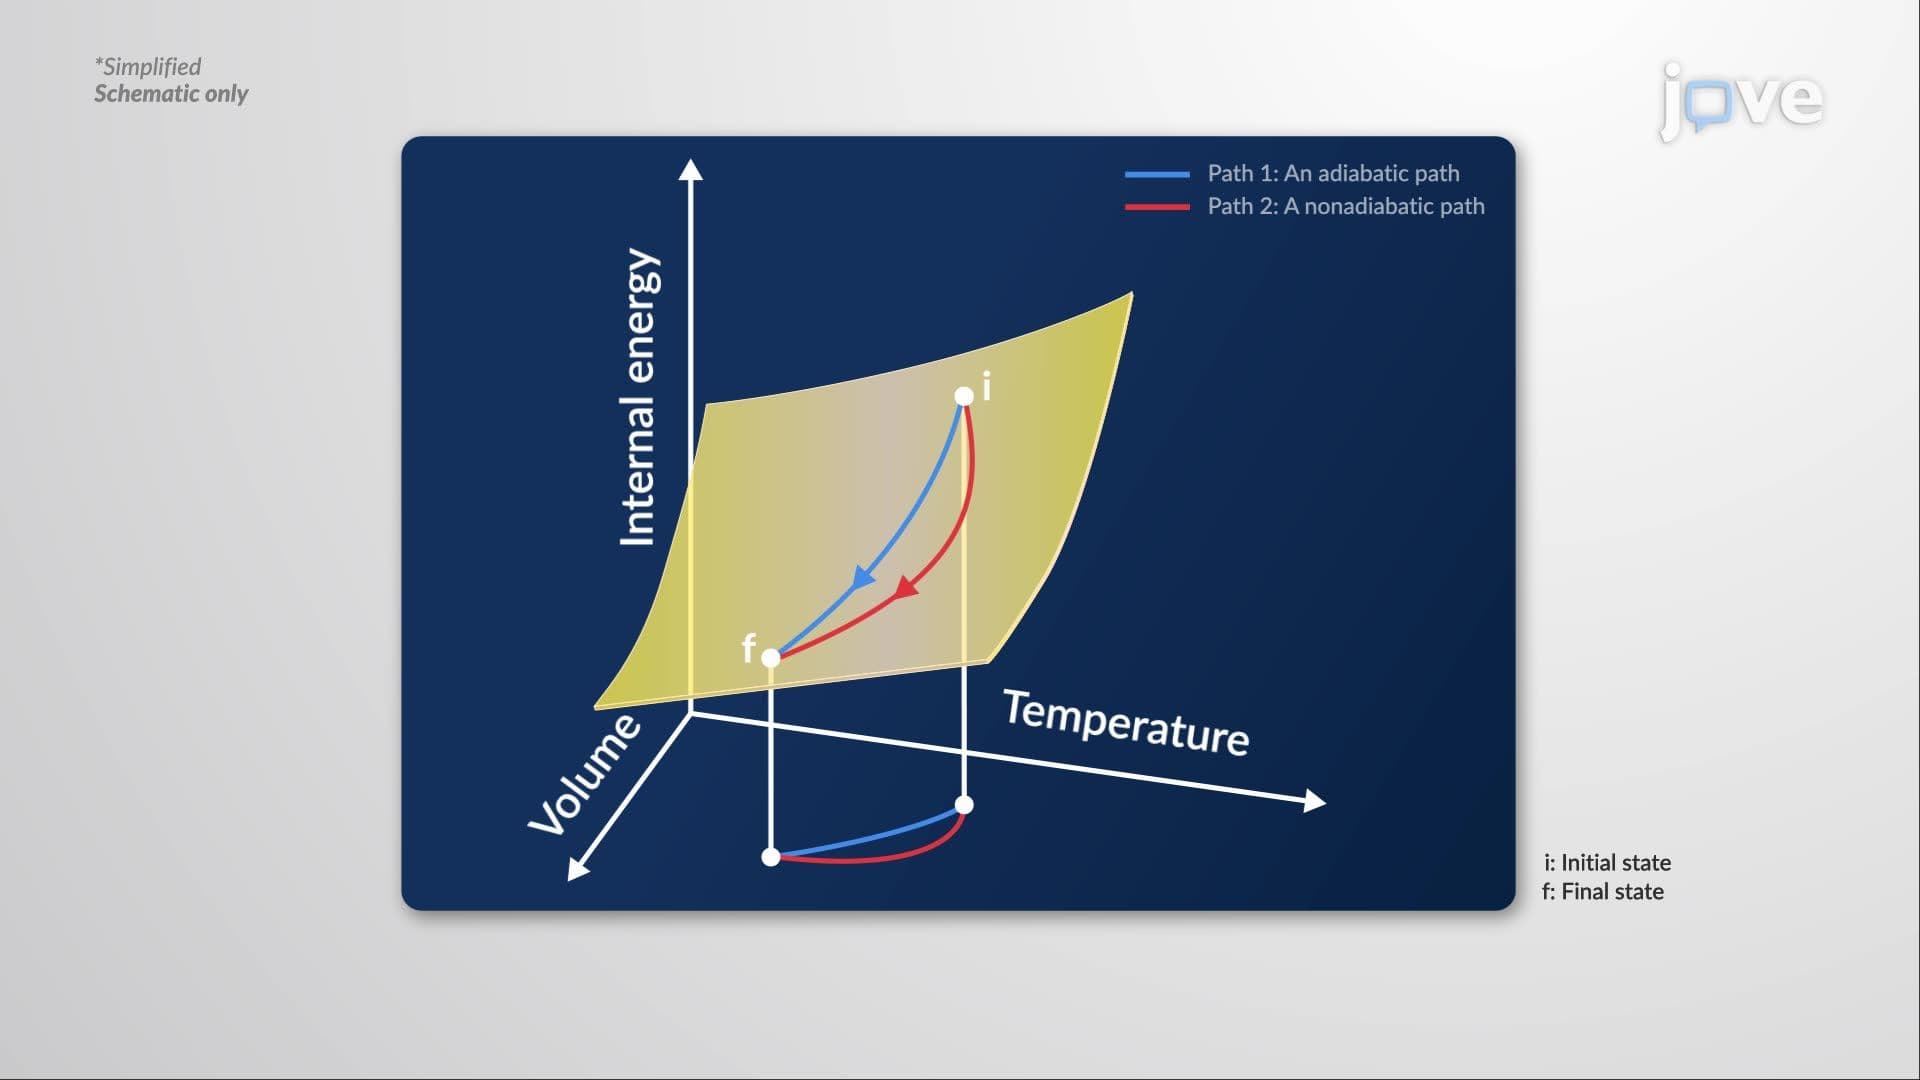
State Function, Exact and Inexact Differentials
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis