Related Experiment Video
Updated: Apr 26, 2026
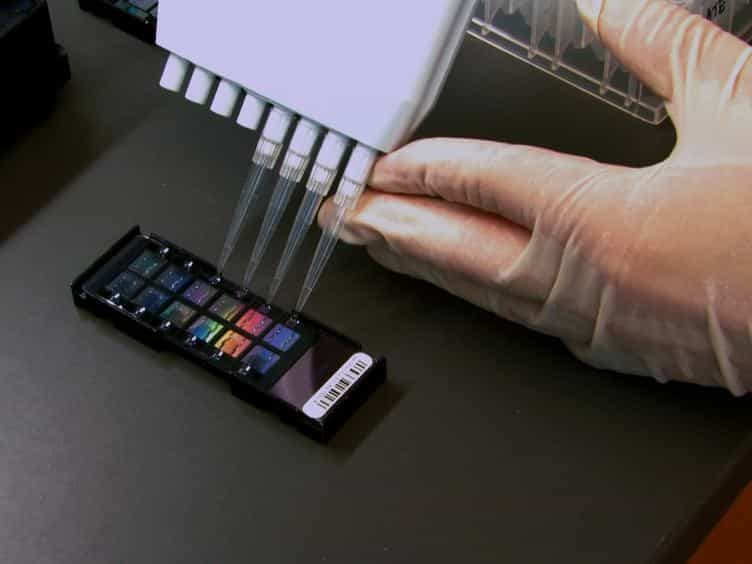
Infinium Assay for Large-scale SNP Genotyping Applications
Published on: November 19, 2013
Value of Mendelian laws of segregation in families: data quality control, imputation, and beyond
Elizabeth M Blue1, Lei Sun, Nathan L Tintle
1Division of Medical Genetics, Department of Medicine, University of Washington, Seattle, Washington, United States of America.

Abstract:
When analyzing family data, we dream of perfectly informative data, even whole-genome sequences (WGSs) for all family members. Reality intervenes, and we find that next-generation sequencing (NGS) data have errors and are often too expensive or impossible to collect on everyone. The Genetic Analysis Workshop 18 working groups on quality control and dropping WGSs through families using a genome-wide association framework focused on finding, correcting, and using errors within the available sequence and family data, developing methods to infer and analyze missing sequence data among relatives, and testing for linkage and association with simulated blood pressure. We found that single-nucleotide polymorphisms, NGS data, and imputed data are generally concordant but that errors are particularly likely at rare variants, for homozygous genotypes, within regions with repeated sequences or structural variants, and within sequence data imputed from unrelated individuals. Admixture complicated identification of cryptic relatedness, but information from Mendelian transmission improved error detection and provided an estimate of the de novo mutation rate. Computationally, fast rule-based imputation was accurate but could not cover as many loci or subjects as more computationally demanding probability-based methods. Incorporating population-level data into pedigree-based imputation methods improved results. Observed data outperformed imputed data in association testing, but imputed data were also useful. We discuss the strengths and weaknesses of existing methods and suggest possible future directions, such as improving communication between data collectors and data analysts, establishing thresholds for and improving imputation quality, and incorporating error into imputation and analytical models.
Related Concept Videos
 01:49
Law of Segregation
 02:03
Law of Independent Assortment
 01:18
Dihybrid Crosses
 01:39
Chromosomal Theory of Inheritance
 01:49
Probability Laws
 02:46
Chi-square Analysis
The chi-square test was developed by Pearson in 1990.
The first step of performing a Chi-square analysis is to establish a null hypothesis, which assumes that there is no real...