Related Experiment Video
Updated: Apr 25, 2026

ExCYT: A Graphical User Interface for Streamlining Analysis of High-Dimensional Cytometry Data
Published on: January 16, 2019
Computationally efficient banding of large covariance matrices for ordered data and connections to banding the
1wang.yanpin@scrippshealth.org , Scripps Health, La Jolla, CA 92037.

Abstract:
In this article, we propose a computationally efficient approach to estimate (large) p-dimensional covariance matrices of ordered (or longitudinal) data based on an independent sample of size n. To do this, we construct the estimator based on a k-band partial autocorrelation matrix with the number of bands chosen using an exact multiple hypothesis testing procedure. This approach is considerably faster than many existing methods and only requires inversion of (k + 1)-dimensional covariance matrices. The resulting estimator is positive definite as long as k < n (where p can be larger than n). We make connections between this approach and banding the Cholesky factor of the modified Cholesky decomposition of the inverse covariance matrix (Wu and Pourahmadi, 2003) and show that the maximum likelihood estimator of the k-band partial autocorrelation matrix is the same as the k-band inverse Cholesky factor. We evaluate our estimator via extensive simulations and illustrate the approach using high-dimensional sonar data.
Related Concept Videos
 01:30
Gaussian Elimination: Problem Solving
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
On...
 01:21
Friedman Two-way Analysis of Variance by Ranks
 01:08
Vector Algebra: Method of Components
In many applications, the magnitudes and directions of...
 01:14
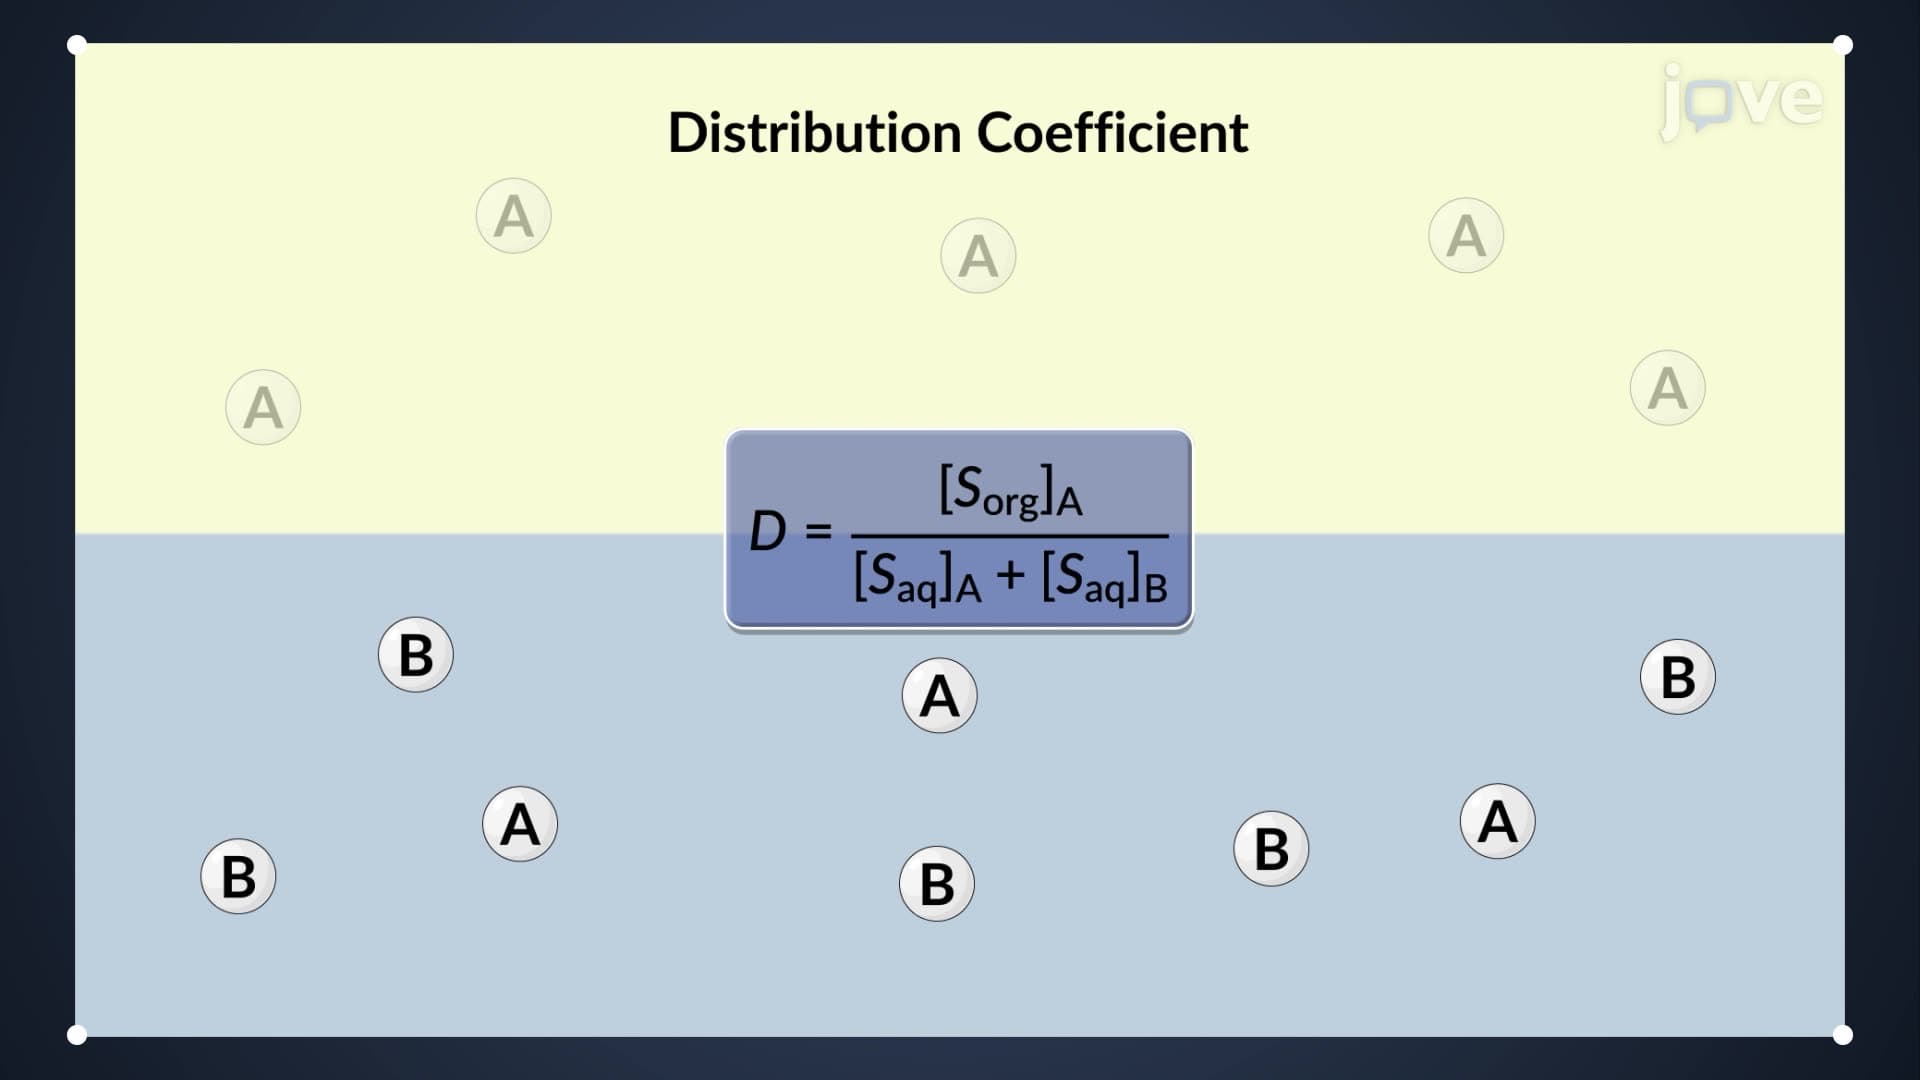
Extraction: Partition and Distribution Coefficients
For extracting a solute from an aqueous phase into an...
 01:11
Calculating and Interpreting the Linear Correlation Coefficient