Related Experiment Video
Updated: Apr 25, 2026
A Novel Bayesian Change-point Algorithm for Genome-wide Analysis of Diverse ChIPseq Data Types
Published on: December 10, 2012
Quality versus accuracy: result of a reanalysis of protein-binding microarrays from the DREAM5 challenge by using
1Pathology Department, Oslo University Hospital - Norwegian Radium Hospital, Montebello, Oslo, 0310, Norway. junbai.wang@rr-research.no.

Background:
Computational modeling transcription factor (TF) sequence specificity is an important research topic in regulatory genomics. A systematic comparison of 26 algorithms to learn TF-DNA binding specificity in in vitro protein-binding microarray (PBM) data was published recently, but the quality of those examined PBMs was not evaluated completely.
Results:
Here, new quality-control parameters such as principal component analysis (PCA) ellipse is proposed to assess the data quality for either single or paired PBMs. Additionally, a biophysical model of TF-DNA interactions including adjacent dinucleotide interdependence was implemented in a new program - BayesPI2, where sparse Bayesian learning and relevance vector machine are used to predict unknown model parameters. Then, 66 mouse TFs from the DREAM5 challenge were classified into two groups (i.e. good vs. bad) based on the paired PBM quality-control parameters. Subsequently, computational methods to model TF sequence specificity were evaluated between the two groups.
Conclusion:
Results indicate that both the algorithm performance and the predicted TF-binding energy-level of a motif are significantly influenced by PBM data quality, where poor PBM data quality is linked to specific protein domains (e.g. C2H2 DNA-binding domain). Especially, the new dinucleotide energy-dependent model (BayesPI2) offers great improvement in testing prediction accuracy over the simple energy-independent model, for at least 21% of analyzed the TFs.
Related Concept Videos
 02:34
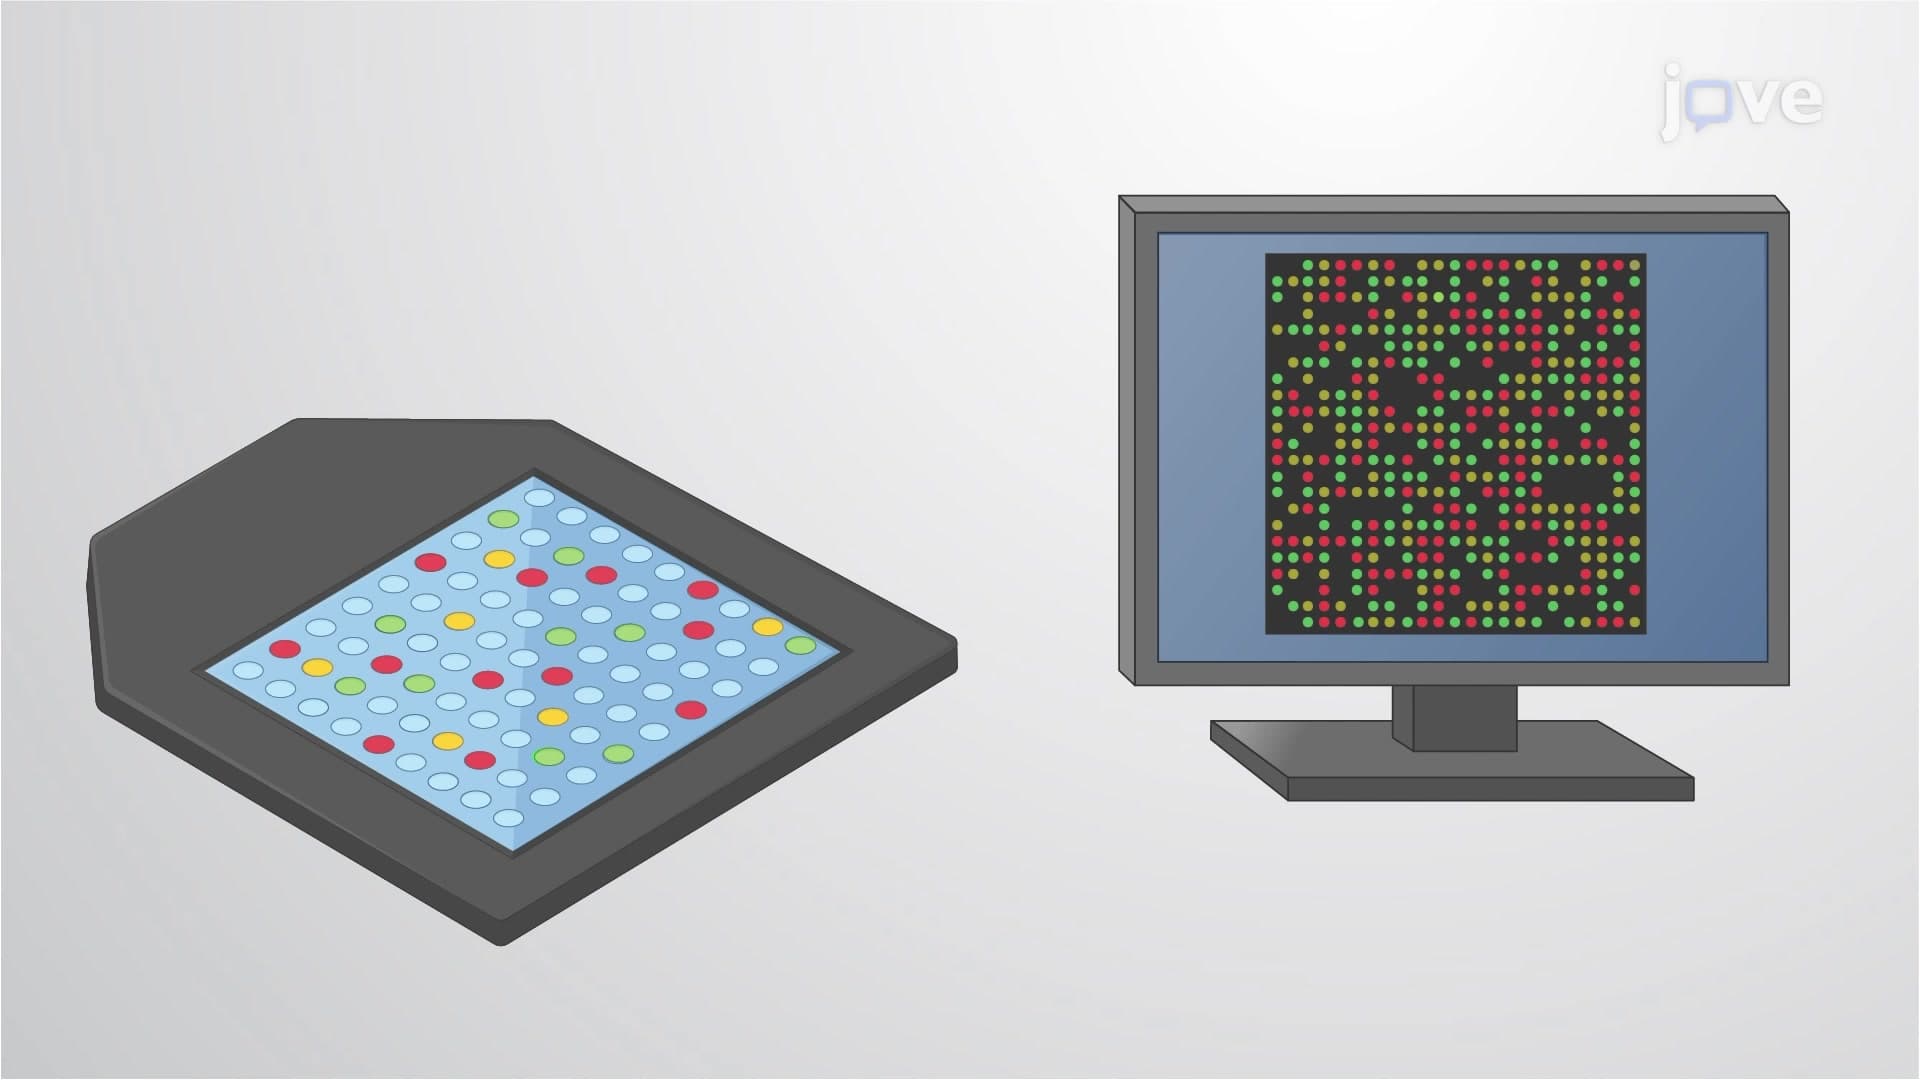
DNA Microarrays
 02:04
Protein-protein Interfaces