Related Experiment Video
Updated: Apr 15, 2026
Probing the Limits of Egg Recognition Using Egg Rejection Experiments Along Phenotypic Gradients
Published on: August 22, 2018
Refined Generalization Bounds of Gradient Learning over Reproducing Kernel Hilbert Spaces
1Statistics School, Southwestern University of Finance and Economics, ChengDu, China, and Institute of Statistical Mathematics, Tachikawa, Tokyo 190-8562, Japan lvsg716@swufe.edu.cn.

Abstract:
Gradient learning (GL), initially proposed by Mukherjee and Zhou (2006) has been proved to be a powerful tool for conducting variable selection and dimensional reduction simultaneously. This approach presents a nonparametric version of a gradient estimator with positive definite kernels without estimating the true function itself, so that the proposed version has wide applicability and allows for complex effects between predictors. In terms of theory, however, existing generalization bounds for GL depend on capacity-independent techniques, and the capacity of kernel classes cannot be characterized completely. Thus, this letter considers GL estimators that minimize the empirical convex risk. We prove generalization bounds for such estimators with rates that are faster than previous results. Moreover, we provide a novel upper bound for Rademacher chaos complexity of order two, which also plays an important role in general pairwise-type estimations, including ranking and score problems.
Related Concept Videos
 01:29
Application of Linearization and Approximation
 01:24
Generalization, Discrimination, and Extinction
Generalization occurs when a behavior reinforced in one context is performed in similar situations. For instance, a student who studies diligently for calculus and receives excellent grades might apply the same study habits to psychology and history, expecting similar results. Generalization shows how learning in one setting can influence behavior in...
 01:26
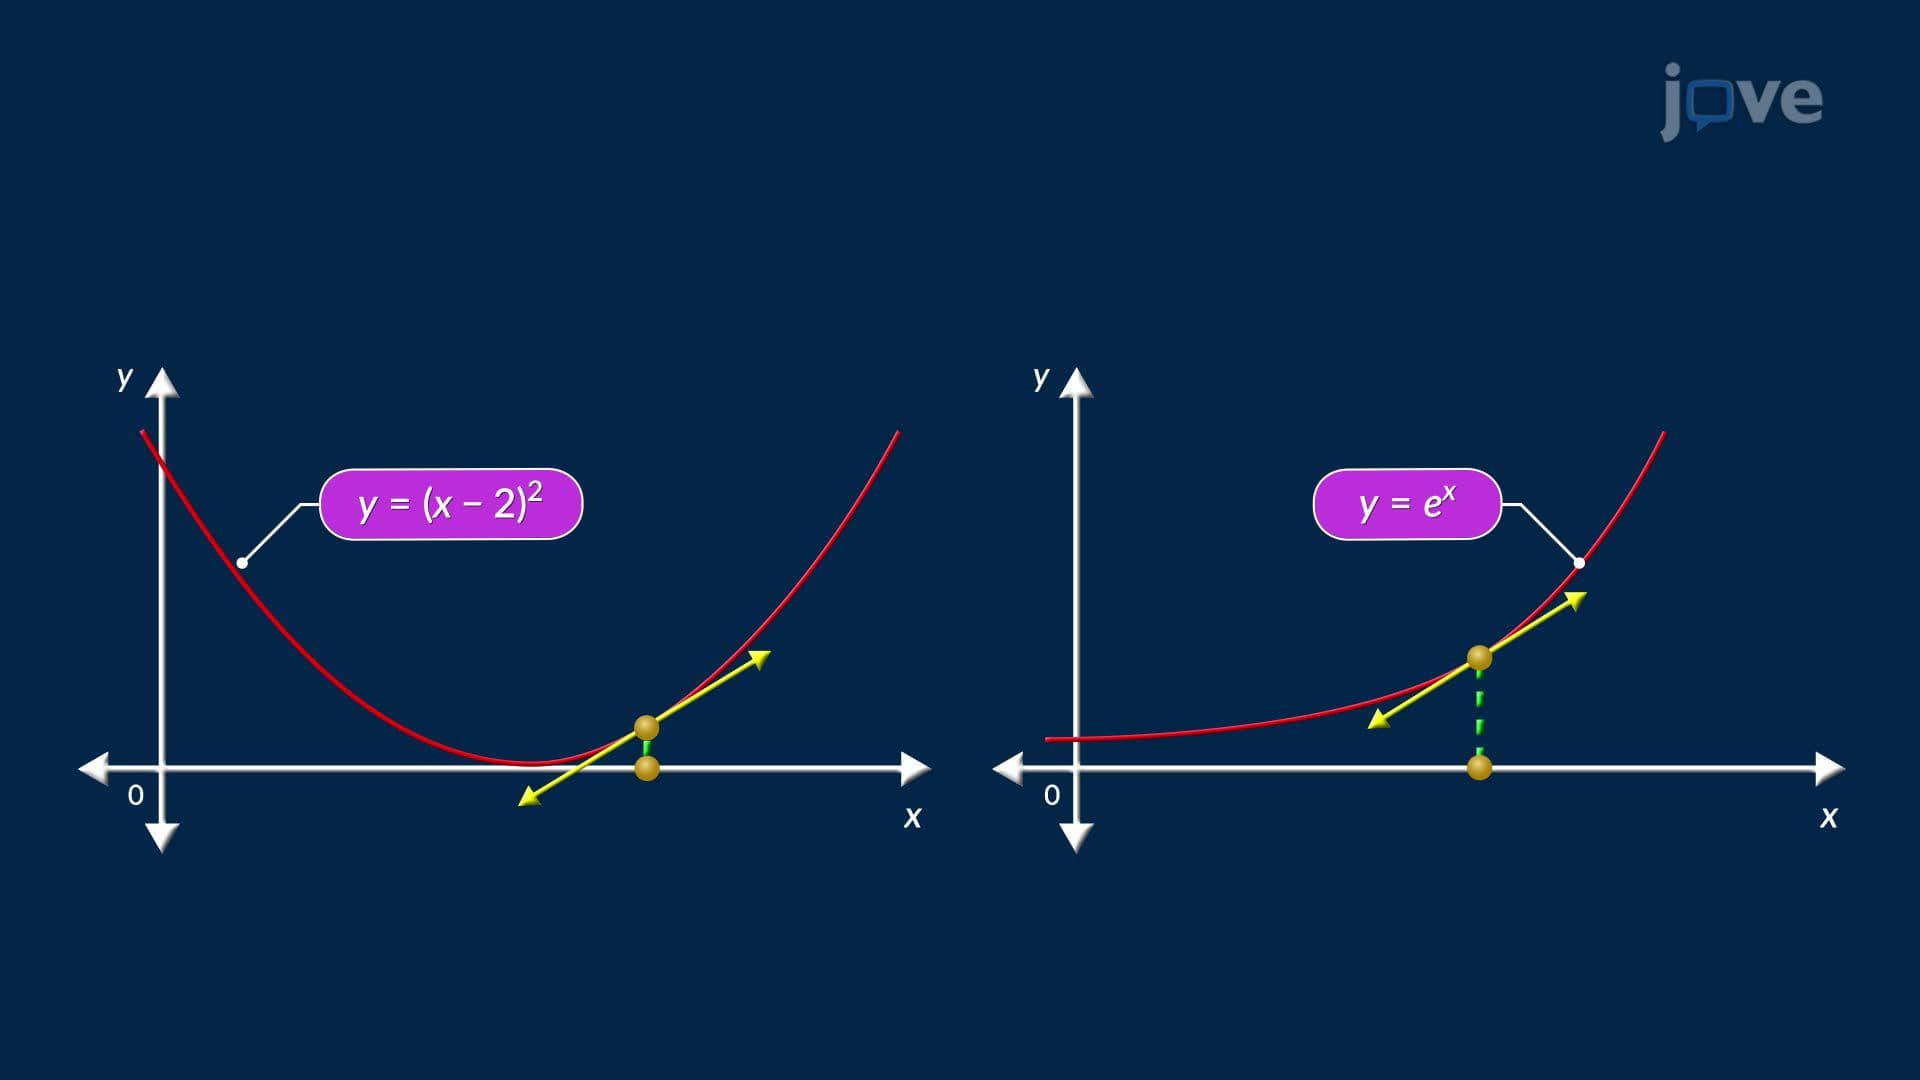
Linearization and Approximation
 01:19
Routh-Hurwitz Criterion II
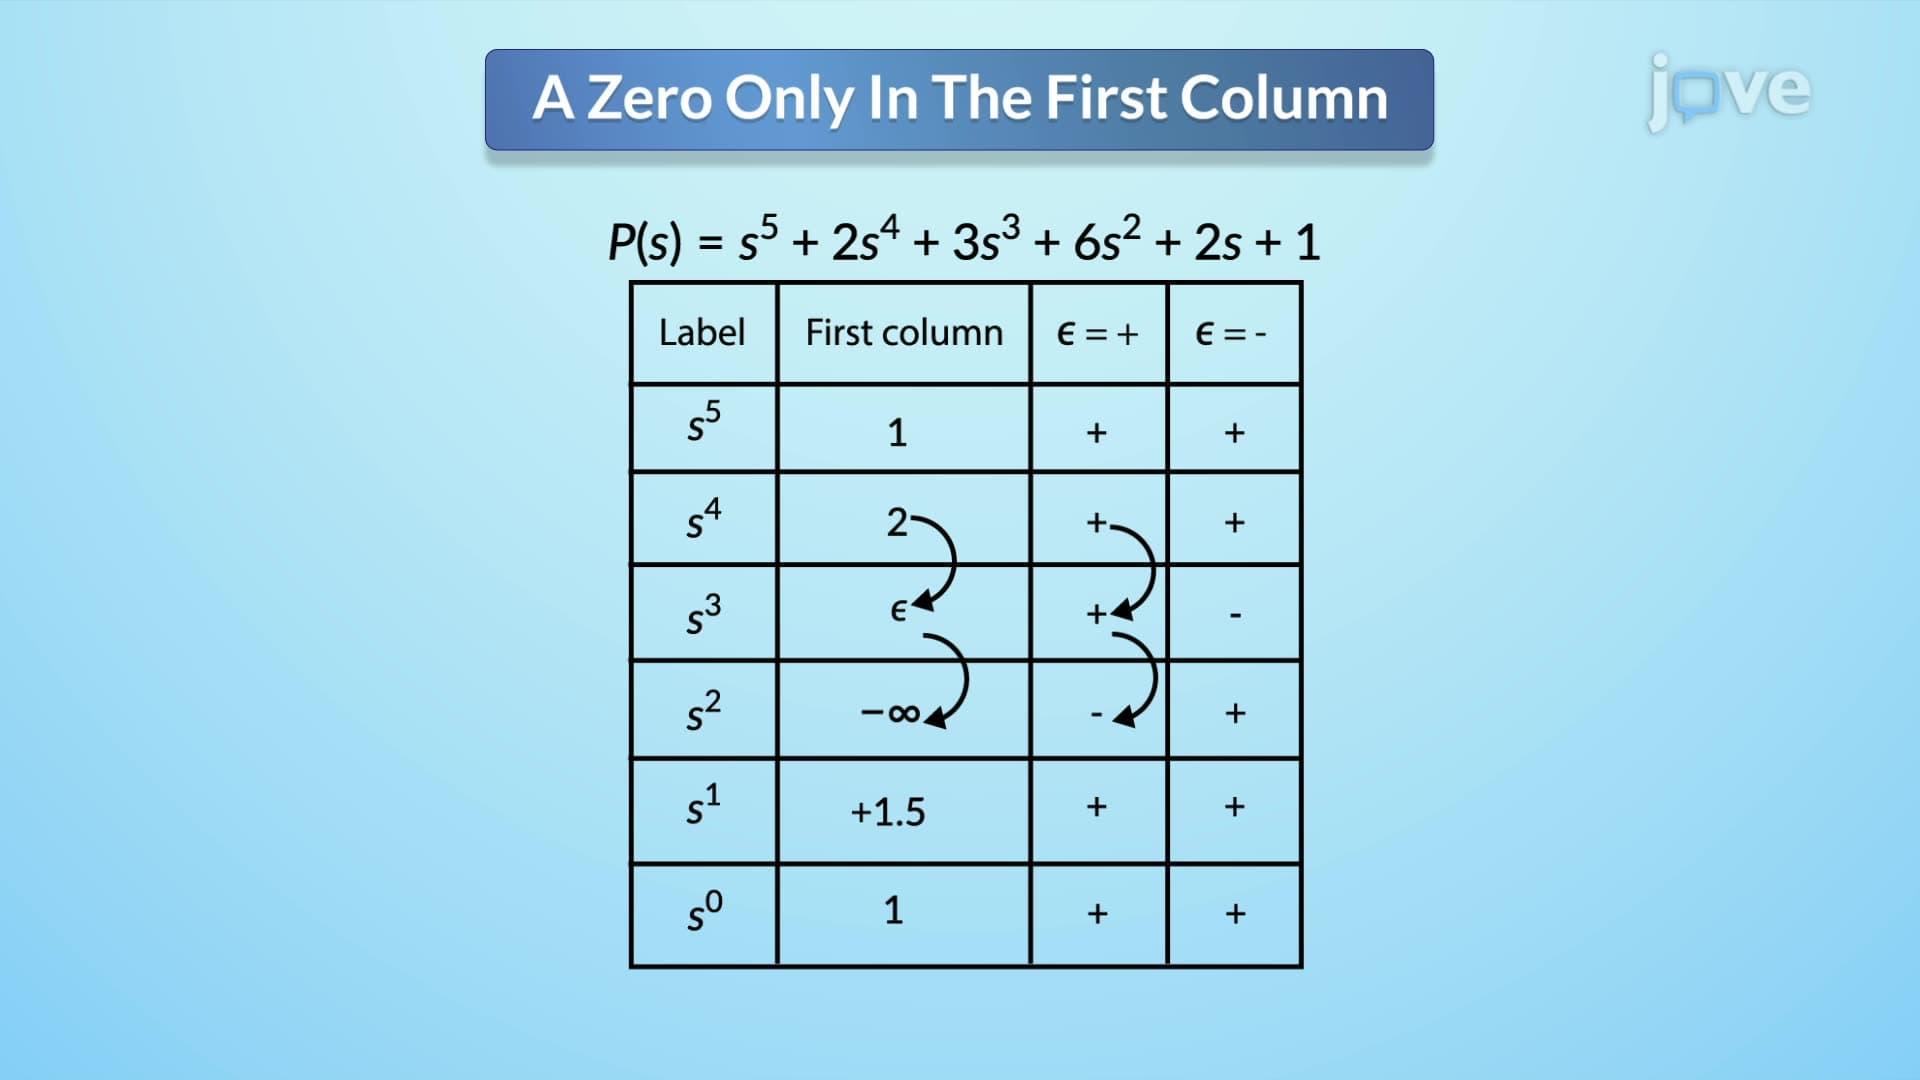
The first scenario occurs when a singular zero appears in the first column of the Routh table. This situation creates a division by zero issues. To resolve this, a small positive or negative number, denoted as epsilon (∈), is substituted for the zero. The stability analysis proceeds by assuming a sign for ∈. If ∈ is positive, any sign change in the first...
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:26
Linear Approximation in Frequency Domain
In contrast, nonlinear systems do not inherently possess these properties. However, for small deviations around an operating point, a nonlinear system can often be approximated as linear....