Related Experiment Video
Updated: Apr 11, 2026
Establishing a Competing Risk Regression Nomogram Model for Survival Data
Published on: October 23, 2020
Robust variance estimation in meta-regression with binary dependent effects
1Teachers College, Columbia University, New York, NY, USA.

Abstract:
Dependent effect size estimates are a common problem in meta-analysis. Recently, a robust variance estimation method was introduced that can be used whenever effect sizes in a meta-analysis are not independent. This problem arises, for example, when effect sizes are nested or when multiple measures are collected on the same individuals. In this paper, we investigate the robustness of this method in small samples when the effect size of interest is the risk difference, log risk ratio, or log odds ratio. This simulation study examines the accuracy of 95% confidence intervals constructed using the robust variance estimator across a large variety of parameter values. We report results for both estimations of the mean effect (intercept) and of a slope. The results indicate that the robust variance estimator performs well even when the number of studies is as small as 10, although coverage is generally less than nominal in the slope estimation case. Throughout, an example based on a meta-analysis of cognitive behavior therapy is used for motivation. Copyright © 2013 John Wiley & Sons, Ltd.
More Related Videos
Related Concept Videos
 01:21
Friedman Two-way Analysis of Variance by Ranks
 01:25
Multiple Regression
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
 01:20
Comparing the Survival Analysis of Two or More Groups
 01:19
Variation
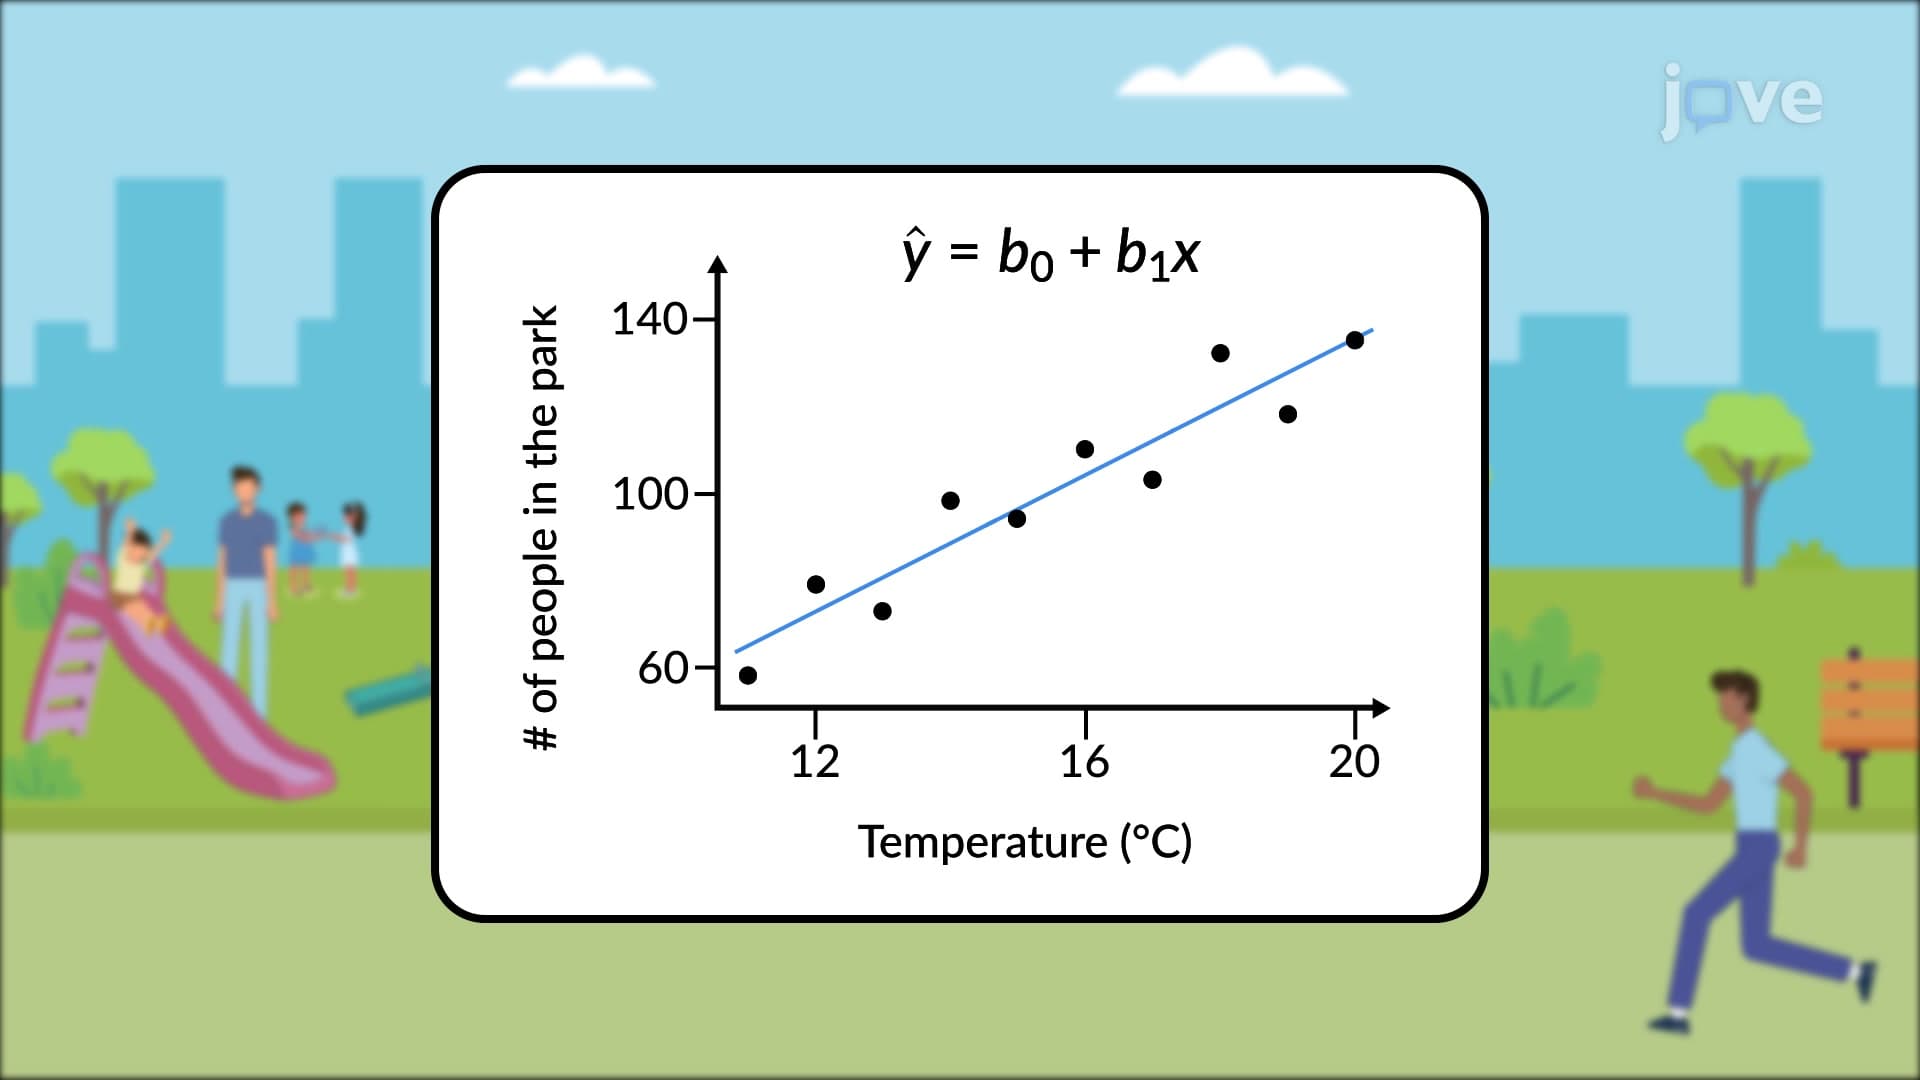
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
 01:11
Regression Analysis
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
 01:19
Expected Frequencies in Goodness-of-Fit Tests