Related Experiment Video
Updated: Apr 10, 2026

Morphology-Based Distinction Between Healthy and Pathological Cells Utilizing Fourier Transforms and Self-Organizing Maps
Published on: October 28, 2018
Text mixing shapes the anatomy of rank-frequency distributions
Jake Ryland Williams1, James P Bagrow1, Christopher M Danforth1
1Department of Mathematics & Statistics, Vermont Complex Systems Center, Computational Story Lab, & the Vermont Advanced Computing Core, The University of Vermont, Burlington, Vermont 05401, USA.

Abstract:
Natural languages are full of rules and exceptions. One of the most famous quantitative rules is Zipf's law, which states that the frequency of occurrence of a word is approximately inversely proportional to its rank. Though this "law" of ranks has been found to hold across disparate texts and forms of data, analyses of increasingly large corpora since the late 1990s have revealed the existence of two scaling regimes. These regimes have thus far been explained by a hypothesis suggesting a separability of languages into core and noncore lexica. Here we present and defend an alternative hypothesis that the two scaling regimes result from the act of aggregating texts. We observe that text mixing leads to an effective decay of word introduction, which we show provides accurate predictions of the location and severity of breaks in scaling. Upon examining large corpora from 10 languages in the Project Gutenberg eBooks collection, we find emphatic empirical support for the universality of our claim.

Related Concept Videos
 01:14
Relative Frequency Histogram
 00:55
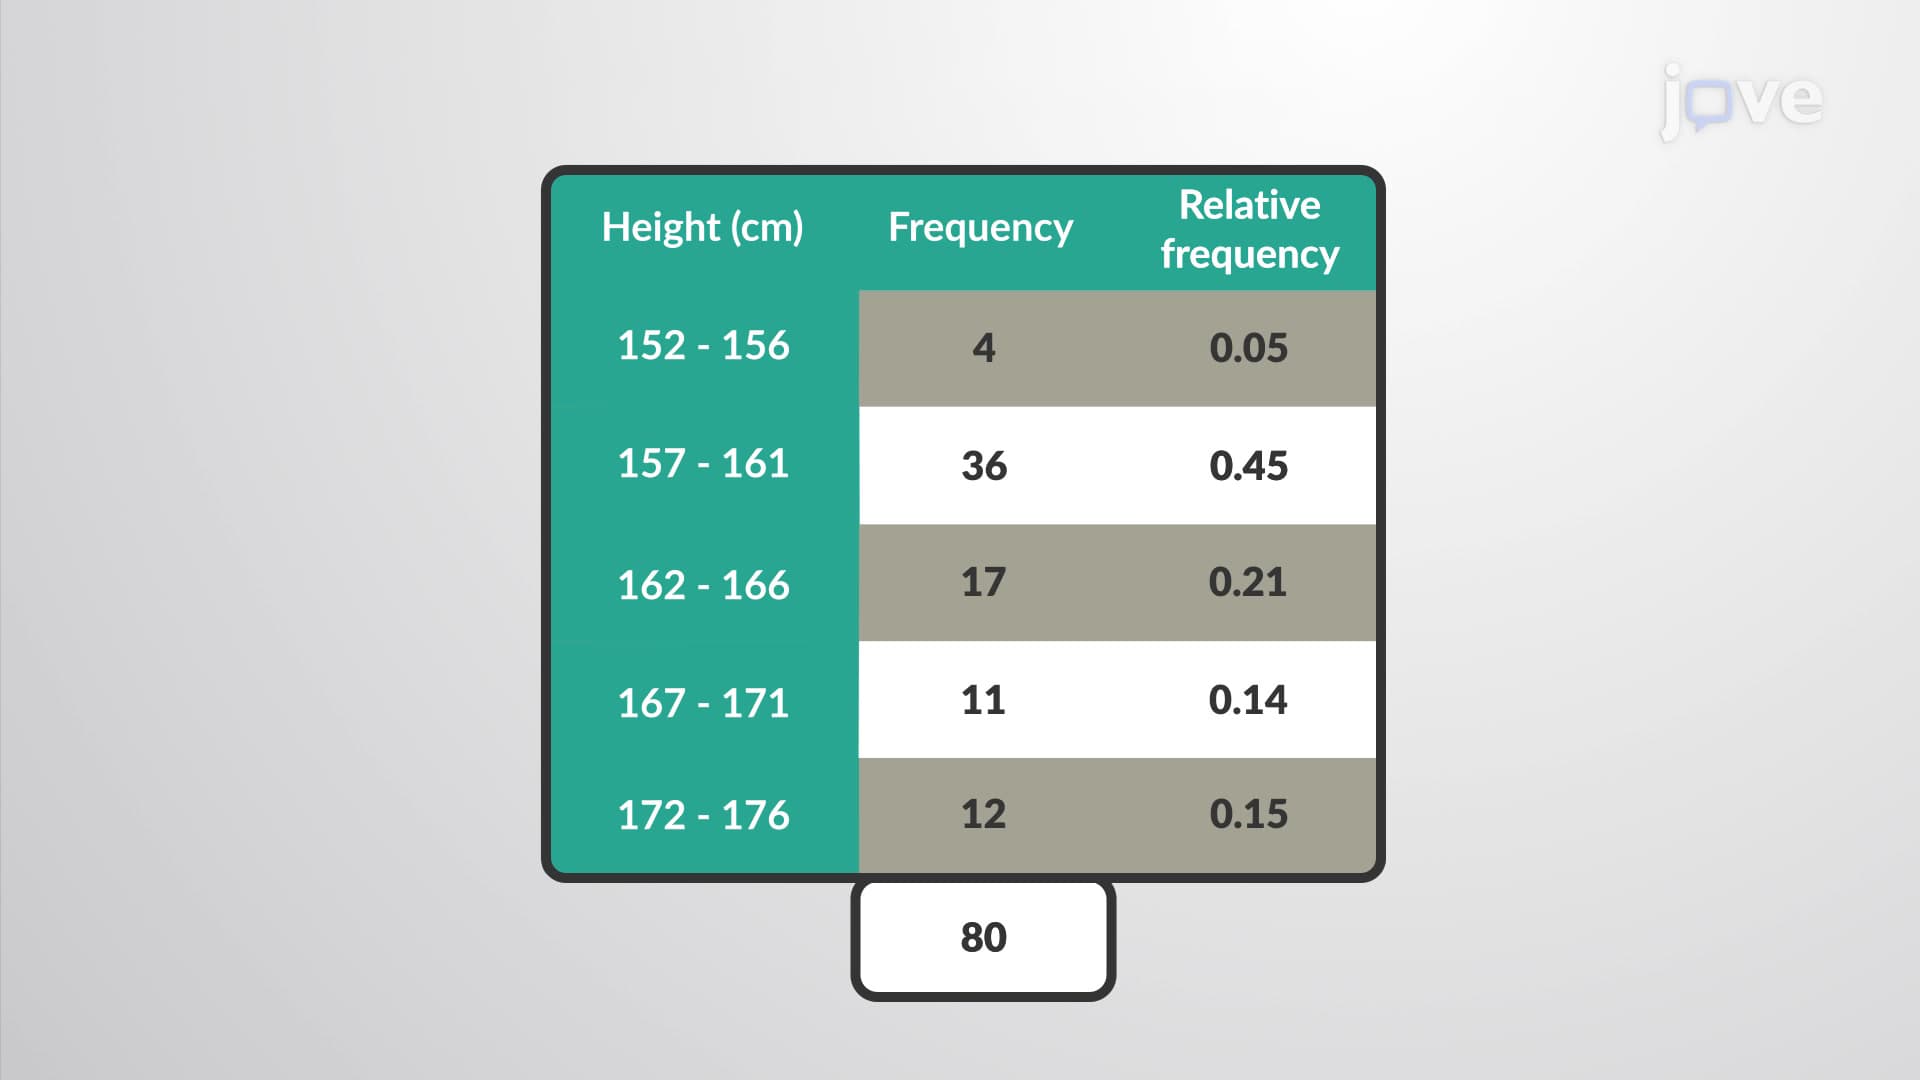
Relative Frequency Distribution
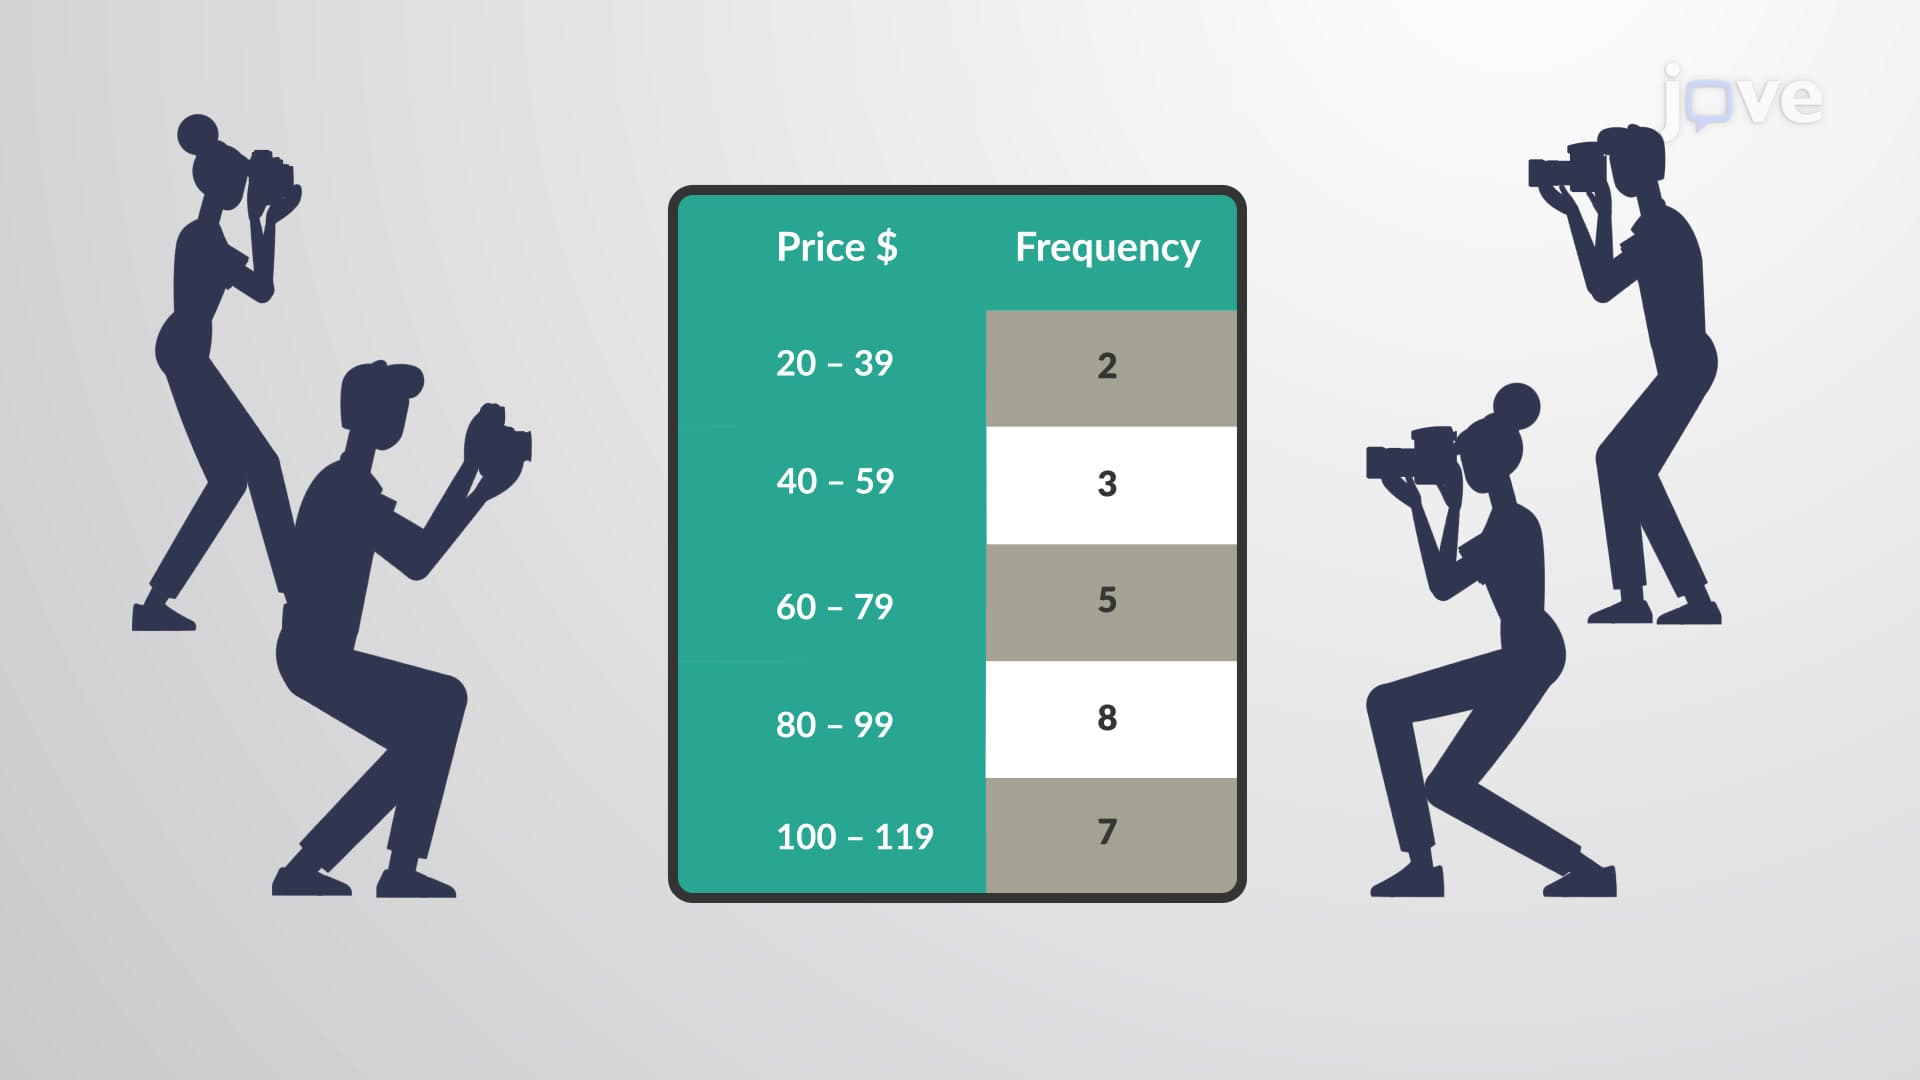 01:04
Cumulative Frequency Distribution
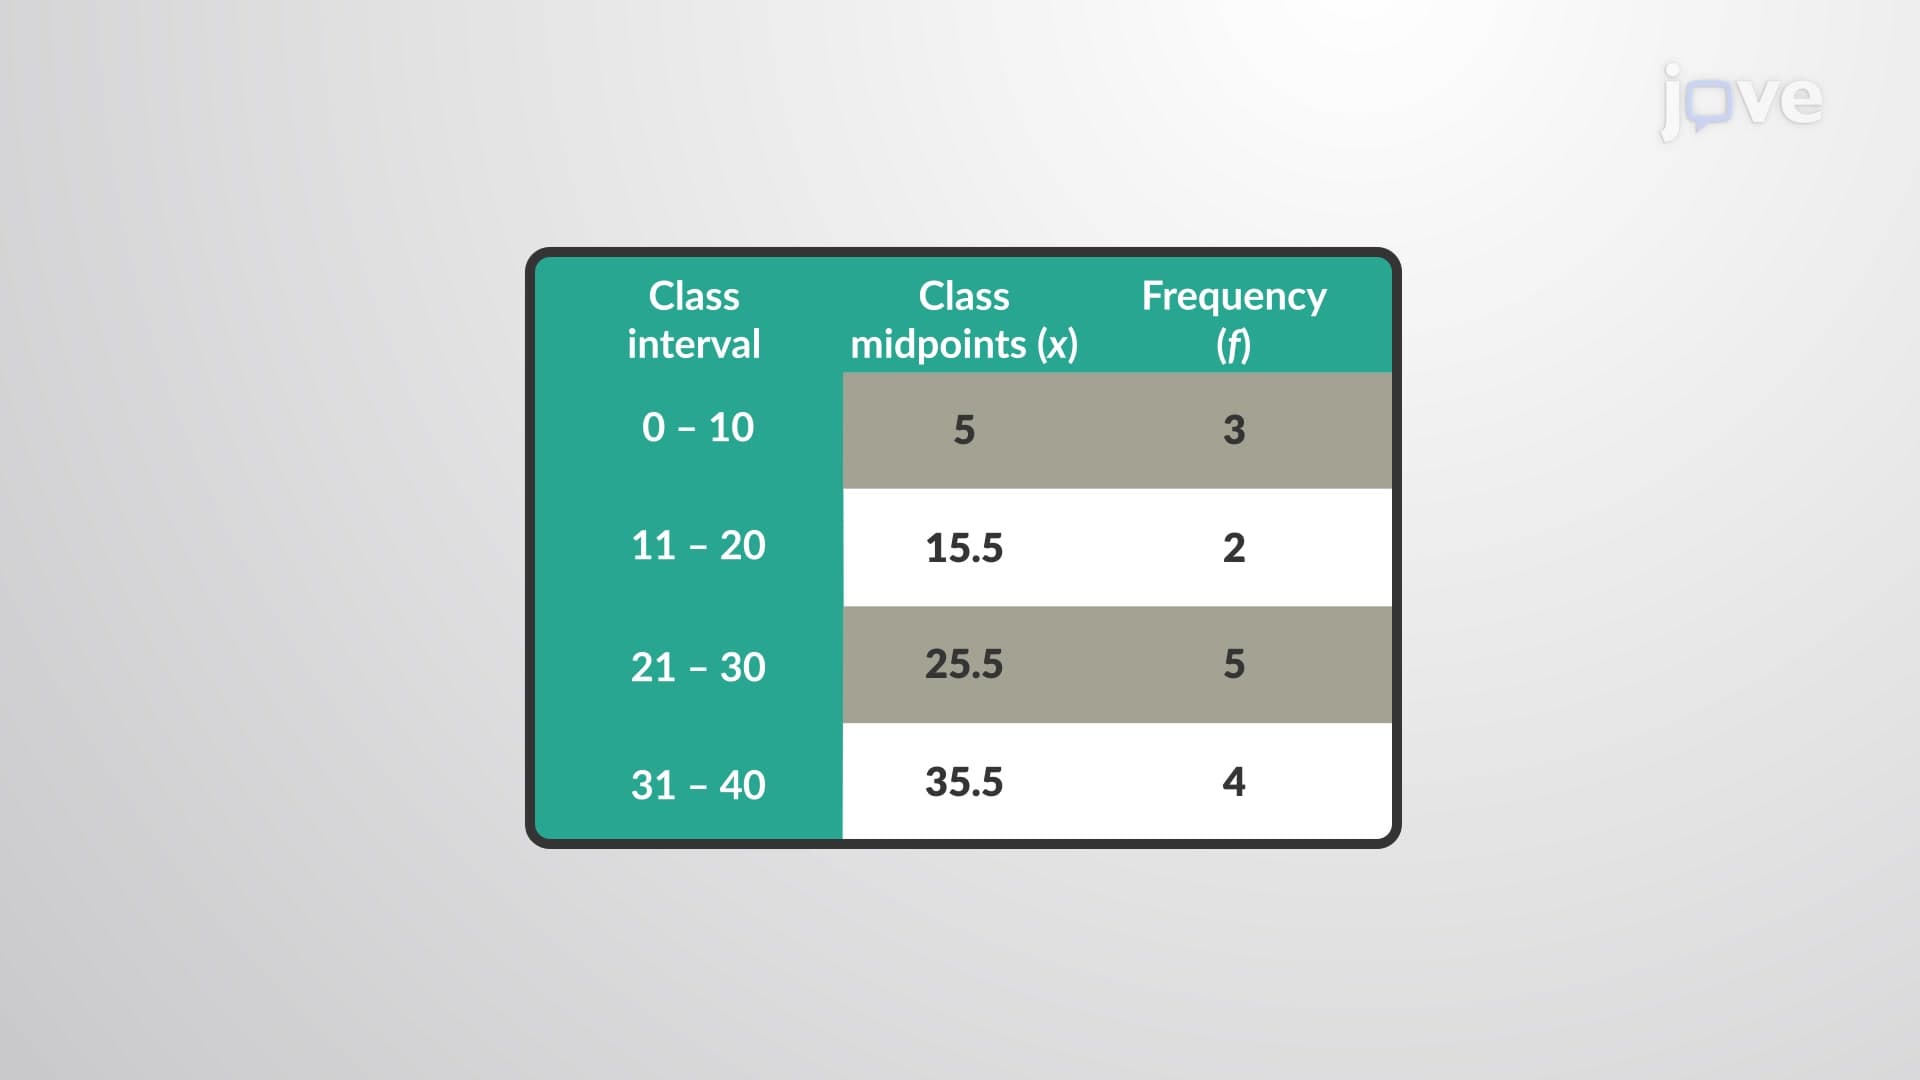 01:11
Mean From a Frequency Distribution
When such a data set is encountered,...
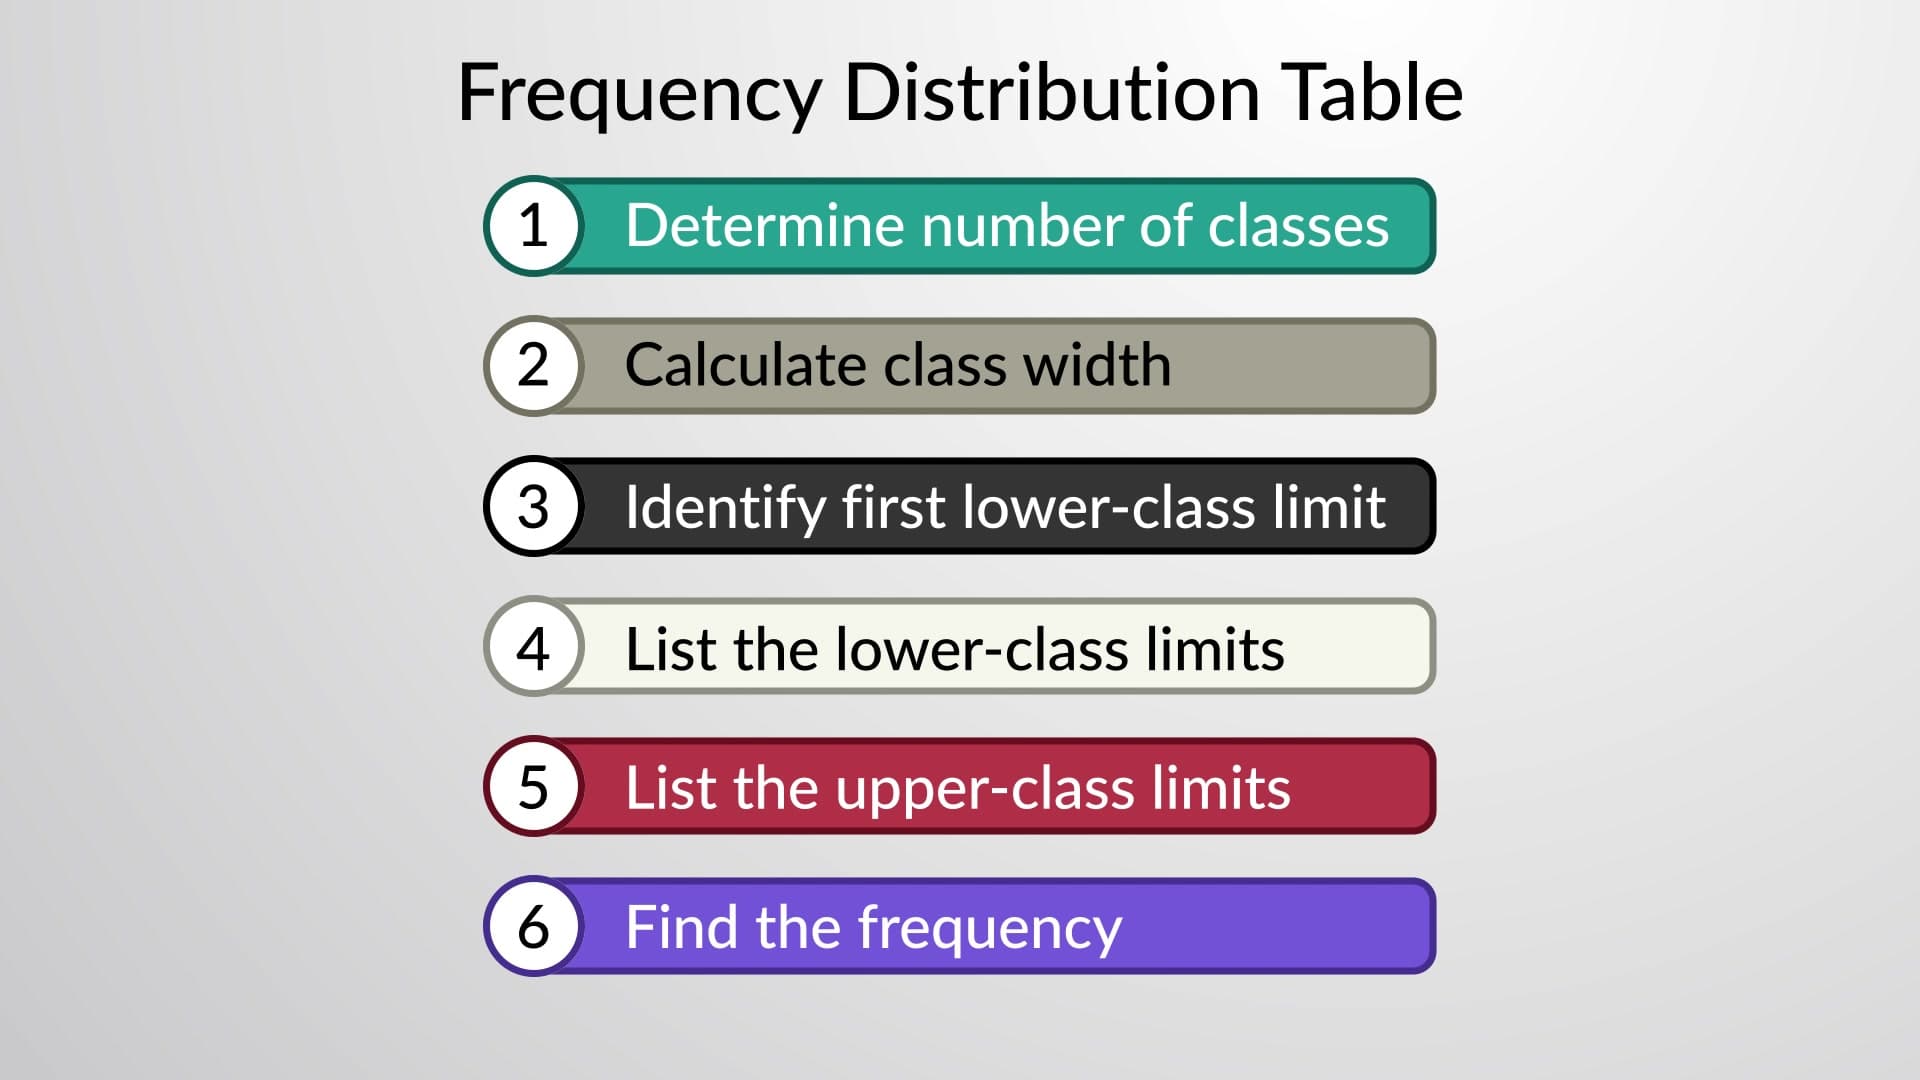 01:15
Construction of Frequency Distribution
First, make a table with two columns—one with the title of the data that needs to be organized, and the other column for frequency. [Draw a third column for tally marks if needed]. Then, take a look at the items given in the data set and decide if an ungrouped frequency distribution table or a grouped frequency distribution table would be more suitable. If there are large sets of different values, then it is...
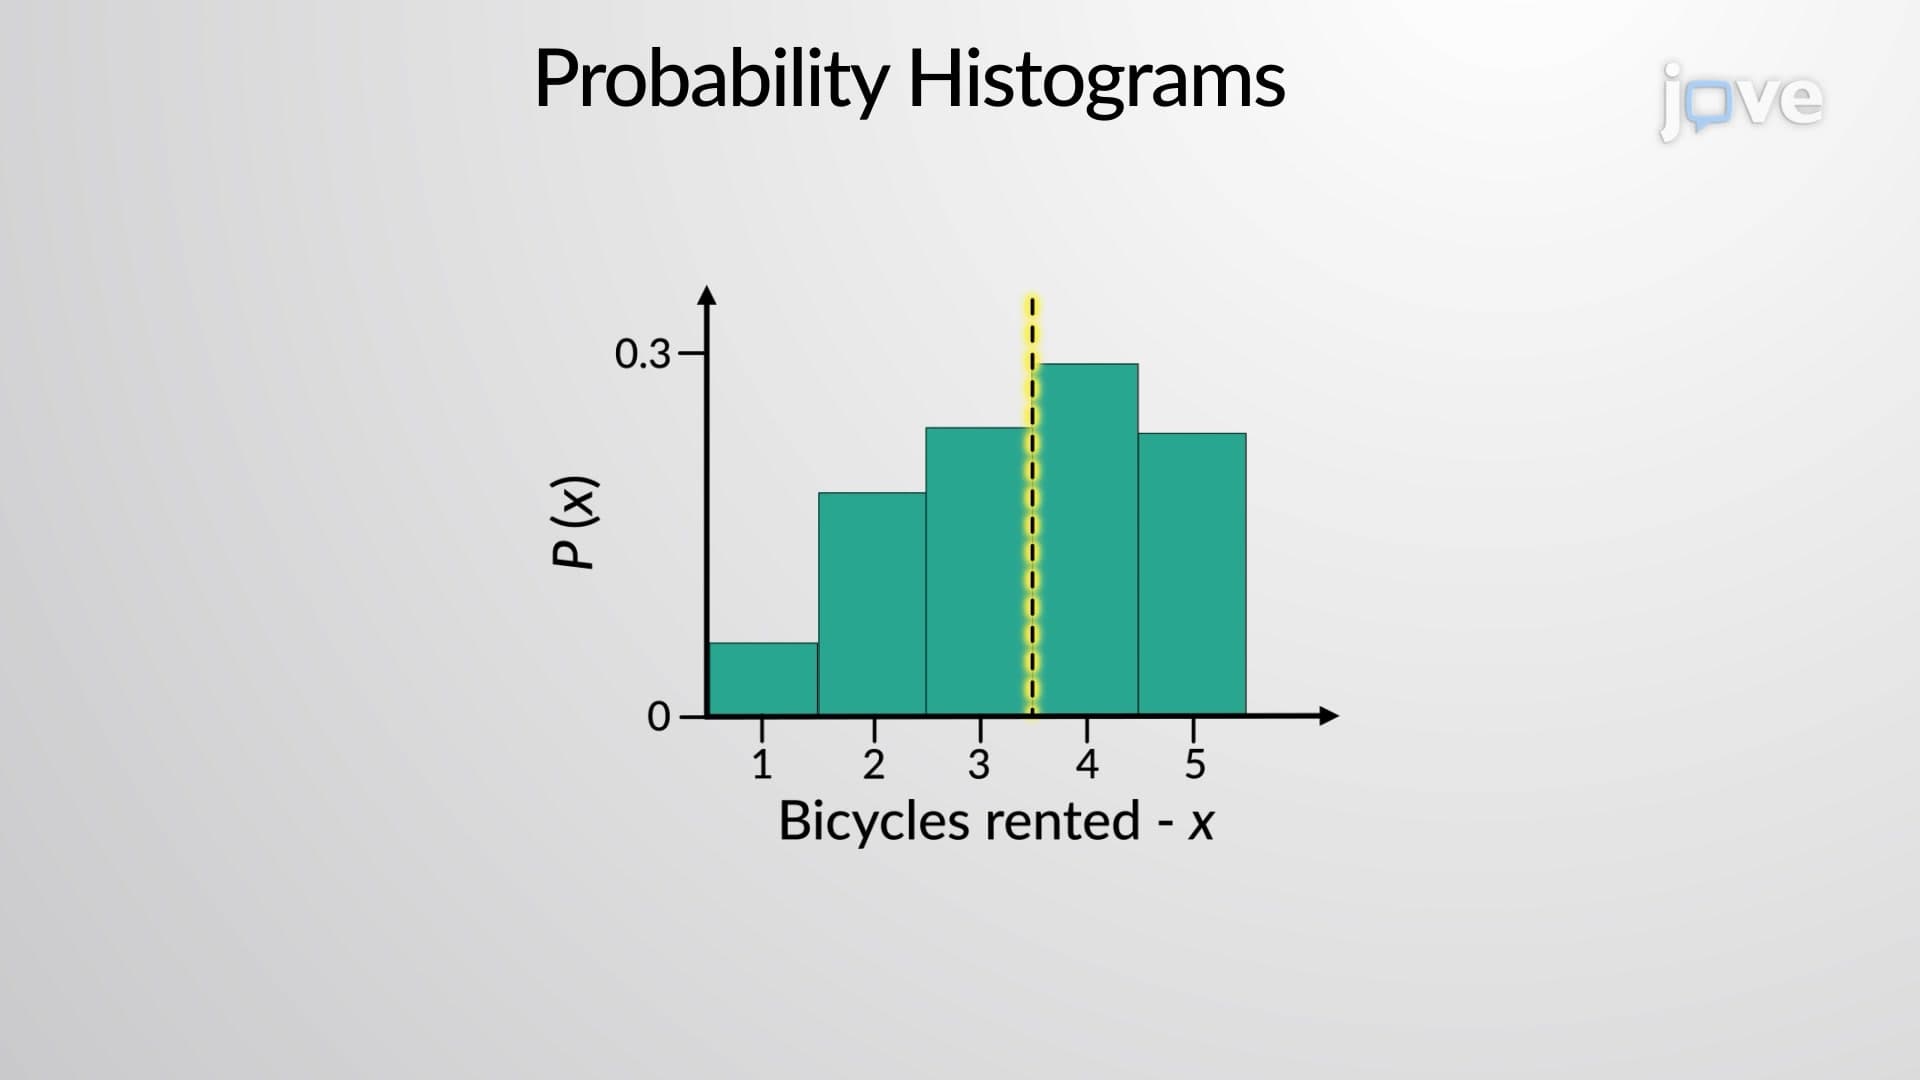 01:17
Probability Histograms