Towards Making Unlabeled Data Never Hurt
Related Experiment Video
Updated: Apr 4, 2026
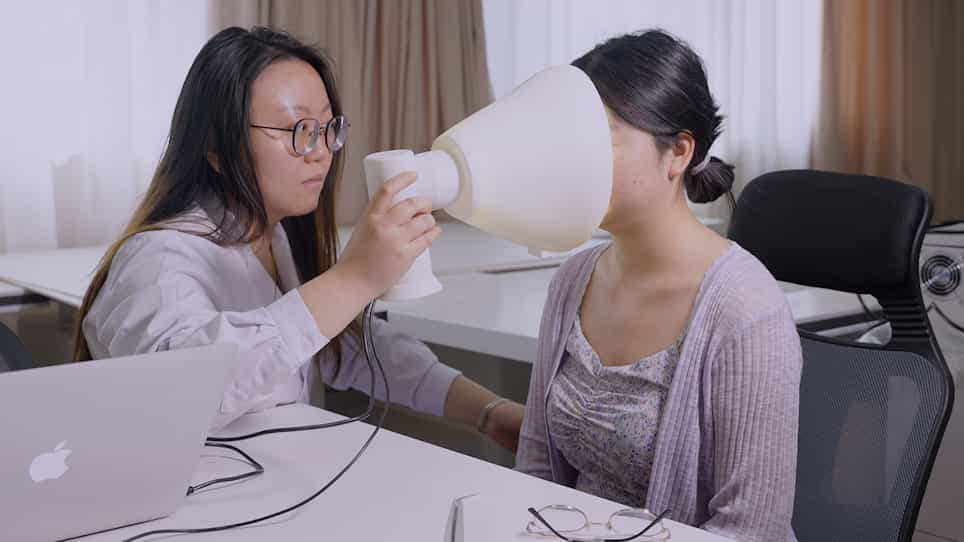
Objectification of Tongue Diagnosis in Traditional Medicine, Data Analysis, and Study Application
Published on: April 14, 2023

Abstract:
It is usually expected that learning performance can be improved by exploiting unlabeled data, particularly when the number of labeled data is limited. However, it has been reported that, in some cases existing semi-supervised learning approaches perform even worse than supervised ones which only use labeled data. For this reason, it is desirable to develop safe semi-supervised learning approaches that will not significantly reduce learning performance when unlabeled data are used. This paper focuses on improving the safeness of semi-supervised support vector machines (S3VMs). First, the S3VM-us approach is proposed. It employs a conservative strategy and uses only the unlabeled instances that are very likely to be helpful, while avoiding the use of highly risky ones. This approach improves safeness but its performance improvement using unlabeled data is often much smaller than S3VMs. In order to develop a safe and well-performing approach, we examine the fundamental assumption of S3VMs, i.e., low-density separation. Based on the observation that multiple good candidate low-density separators may be identified from training data, safe semi-supervised support vector machines (S4VMs) are here proposed. This approach uses multiple low-density separators to approximate the ground-truth decision boundary and maximizes the improvement in performance of inductive SVMs for any candidate separator. Under the assumption employed by S3VMs, it is here shown that S4VMs are provably safe and that the performance improvement using unlabeled data can be maximized. An out-of-sample extension of S4VMs is also presented. This extension allows S4VMs to make predictions on unseen instances. Our empirical study on a broad range of data shows that the overall performance of S4VMs is highly competitive with S3VMs, whereas in contrast to S3VMs which hurt performance significantly in many cases, S4VMs rarely perform worse than inductive SVMs.
More Related Videos

Related Concept Videos
 01:20
Labeling Emotion
 01:19
Survival Tree
Building a Survival Tree
Constructing a...
 01:11
How Data are Classified: Categorical Data
Data are classified based on whether they are measurable or not. Categorical data cannot be measured; instead, it can be divided into categories. For example, if Y denotes a person's party affiliation, some examples of Y include...
 03:31
Labeling DNA Probes
Radioisotopes, fluorophores, or small molecule binding partners like biotin or digoxigenin, are the most widely used reporter tags for labeling DNA probes. These labels can be attached to the probe DNA molecule via...