Related Experiment Video
Updated: Apr 4, 2026
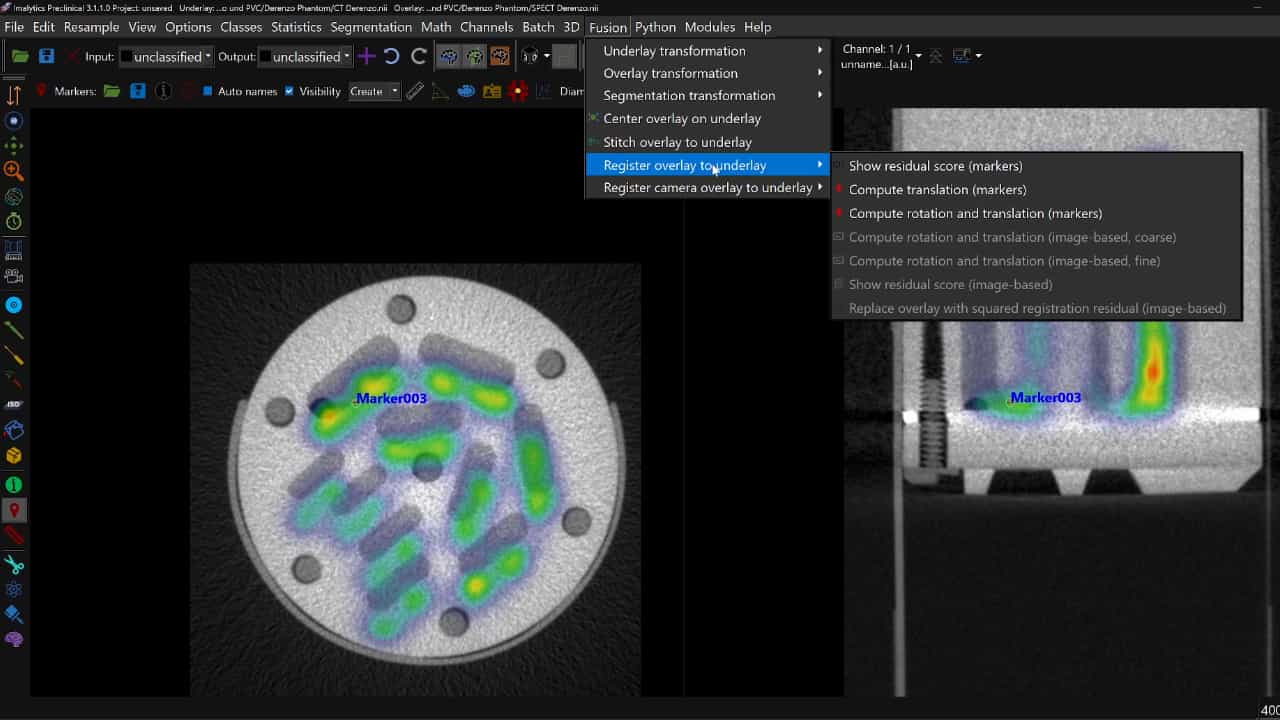
Author Spotlight: An Efficient and Robust Software for Automated Fusion of Multiple Preclinical Imaging Modalities
Published on: October 27, 2023
The Inverted Multi-Index

Abstract:
A new data structure for efficient similarity search in very large datasets of high-dimensional vectors is introduced. This structure called the inverted multi-index generalizes the inverted index idea by replacing the standard quantization within inverted indices with product quantization. For very similar retrieval complexity and pre-processing time, inverted multi-indices achieve a much denser subdivision of the search space compared to inverted indices, while retaining their memory efficiency. Our experiments with large datasets of SIFT and GIST vectors demonstrate that because of the denser subdivision, inverted multi-indices are able to return much shorter candidate lists with higher recall. Augmented with a suitable reranking procedure, multi-indices were able to significantly improve the speed of approximate nearest neighbor search on the dataset of 1 billion SIFT vectors compared to the best previously published systems, while achieving better recall and incurring only few percent of memory overhead.
More Related Videos
Related Concept Videos
 01:09
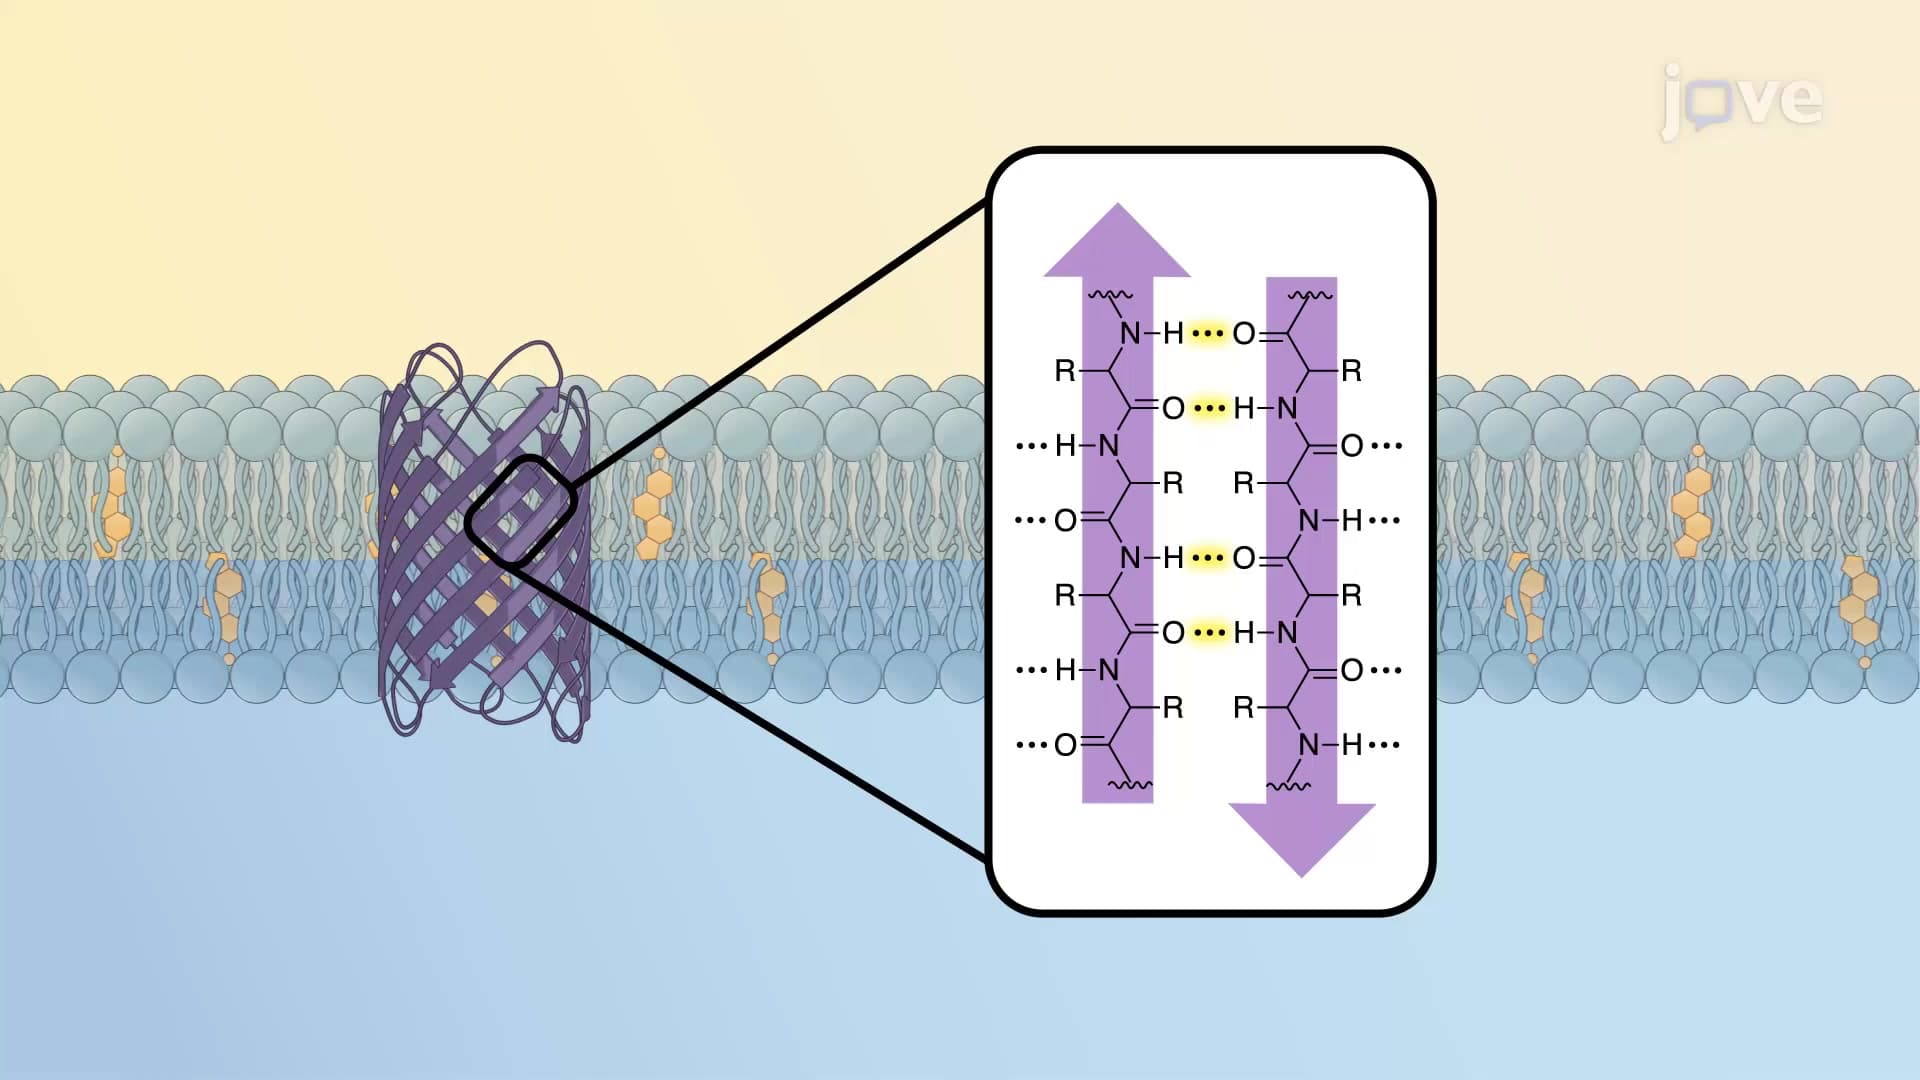
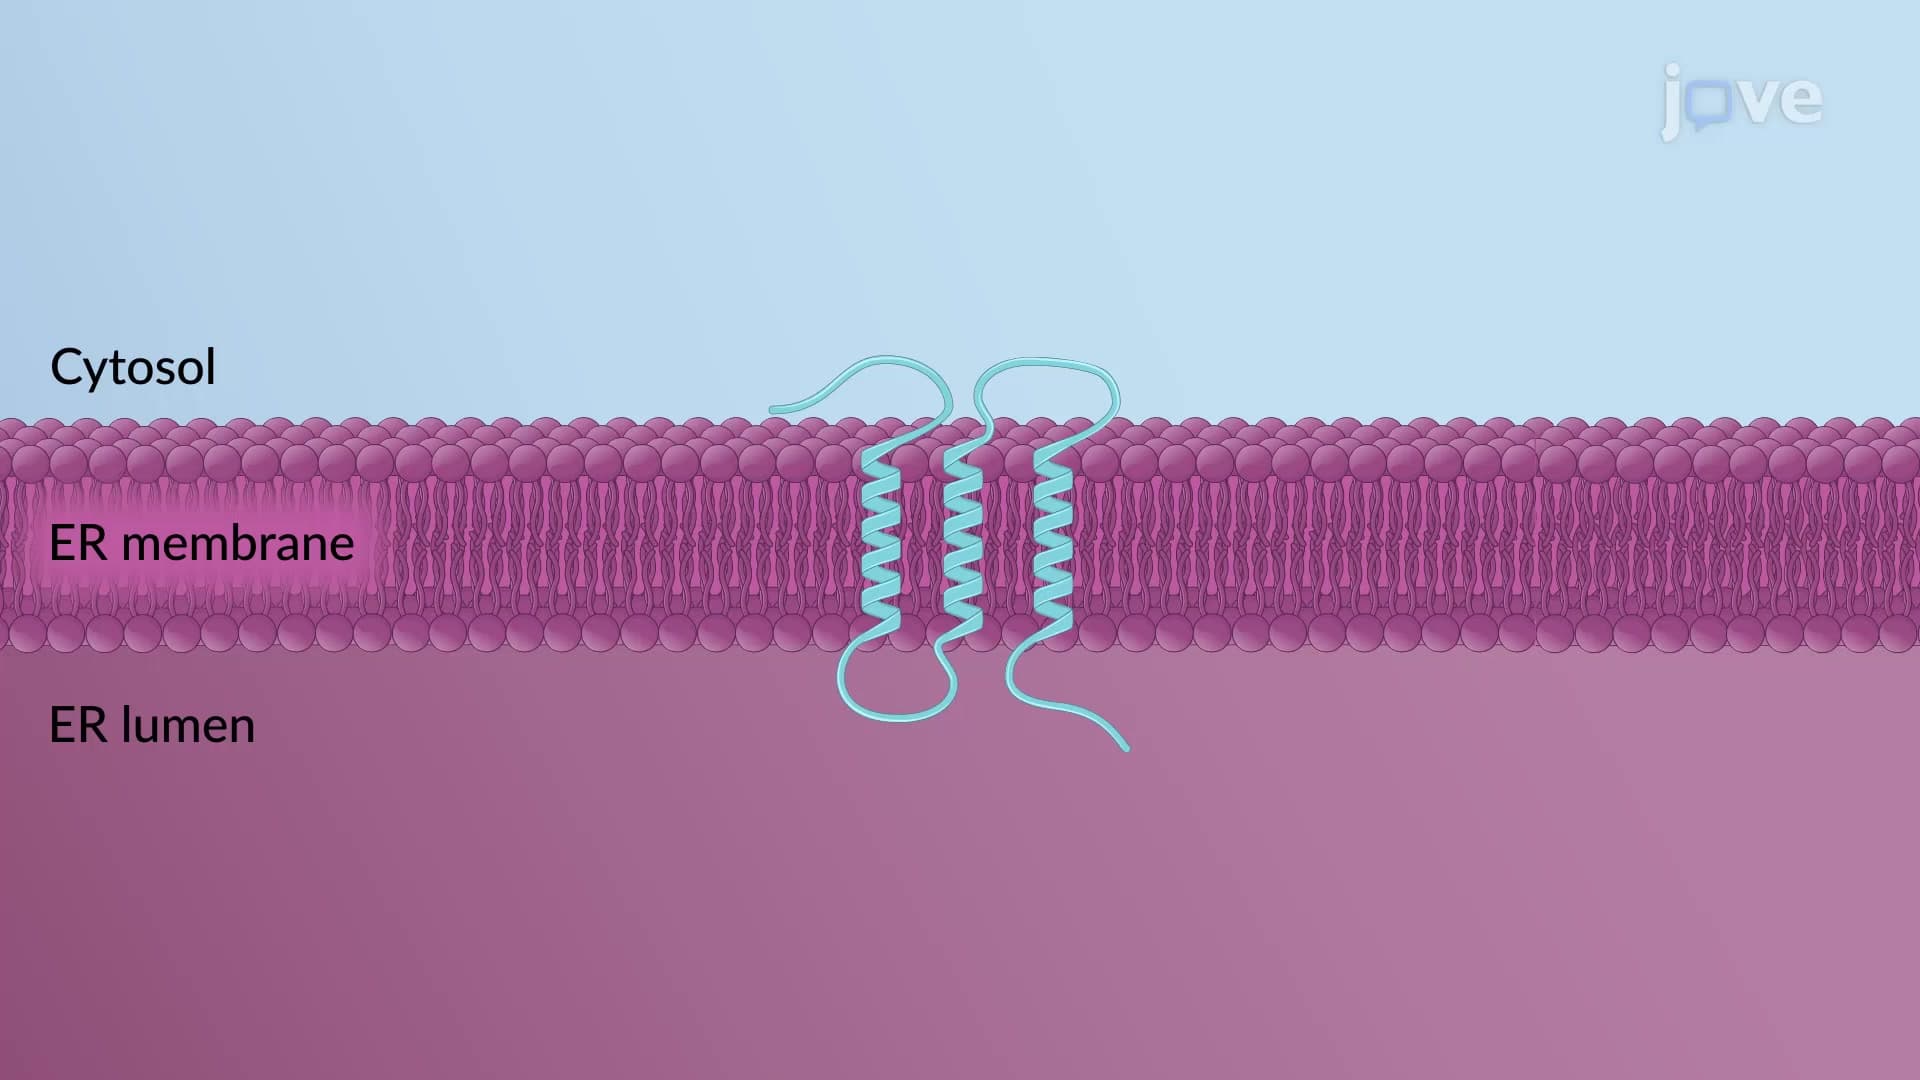
Multi-pass Transmembrane Proteins and β-barrels
α-Helix containing multi-pass transmembrane proteins
Multi-pass transmembrane proteins such as...
 01:29
Insertion of Multi-pass Transmembrane Proteins in the RER
The multipass transmembrane proteins are the type IV integral membrane proteins with multiple topogenic sequences determining their spatial arrangement in the ER membrane. Nearly all multipass proteins lack a cleavable signal sequence and use...
 01:20
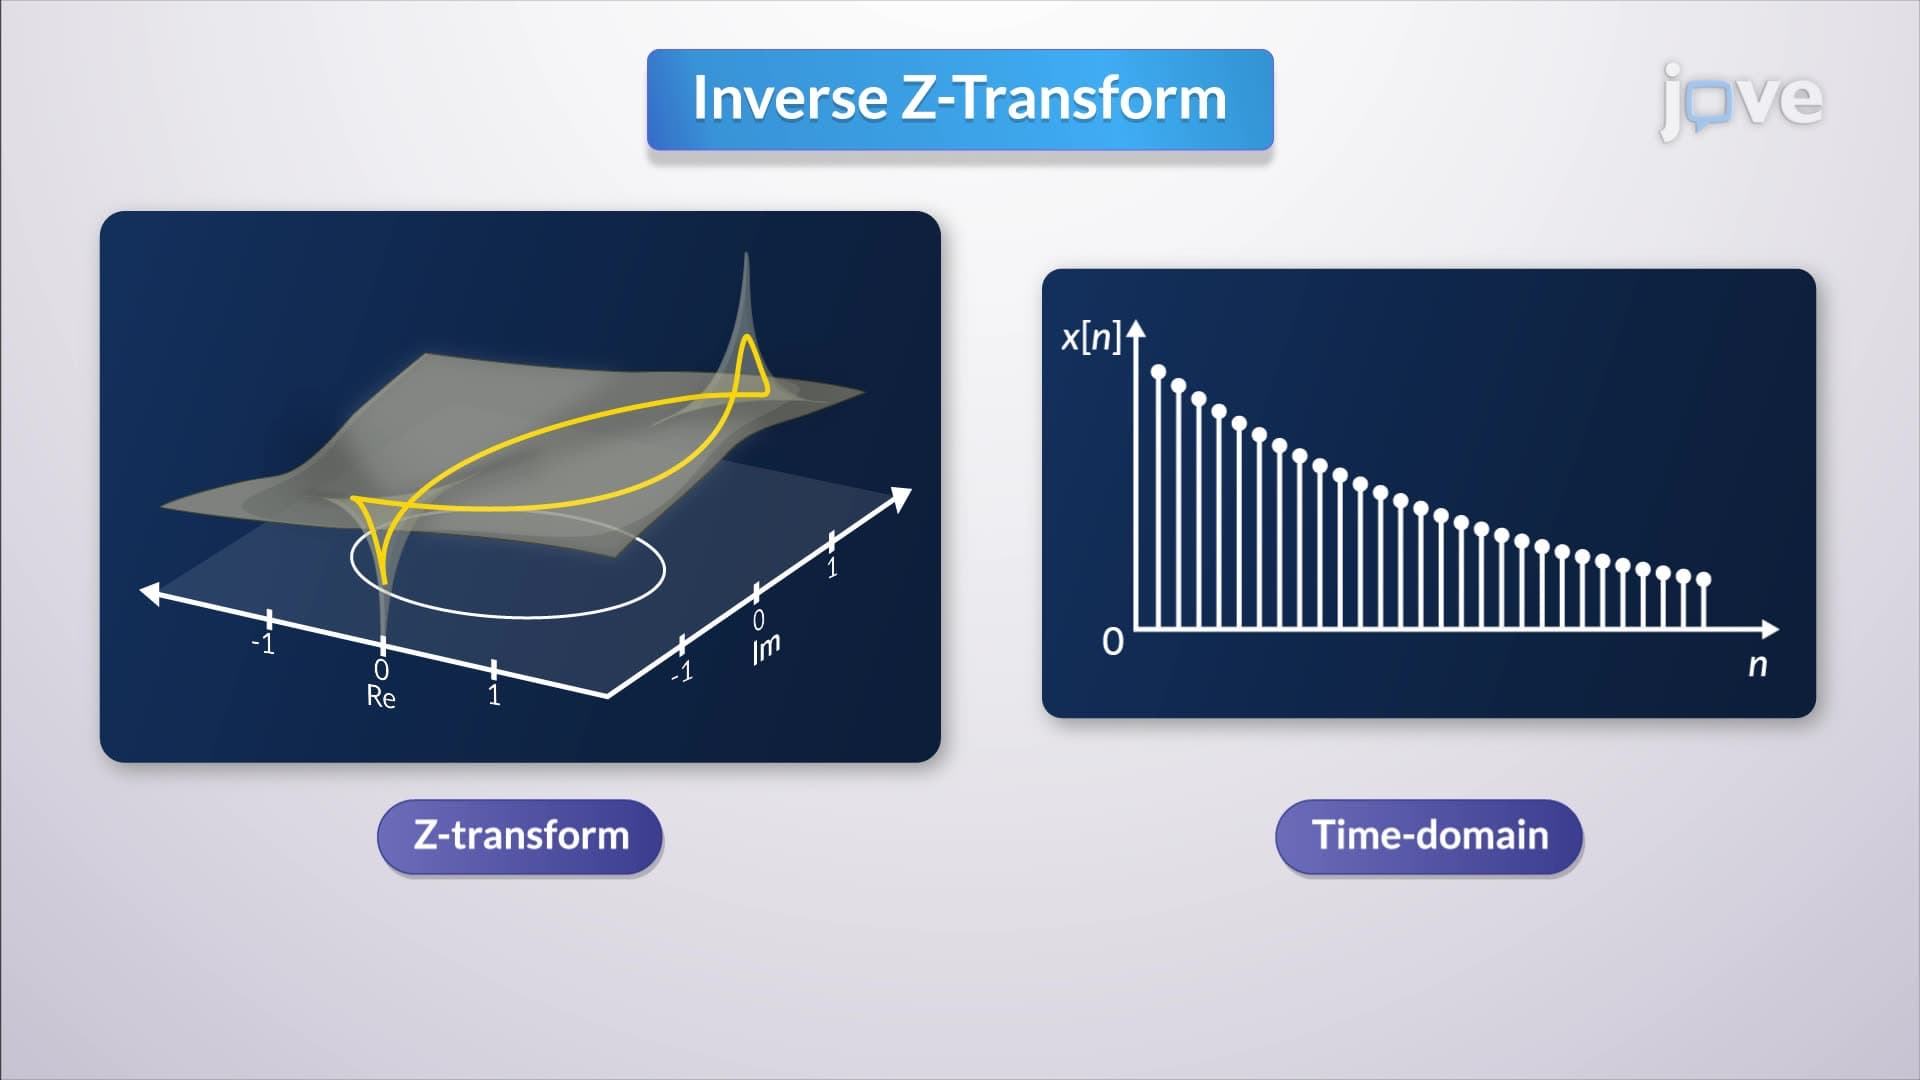
Inverse z-Transform by Partial Fraction Expansion
To begin the process, the poles of the function are identified and the function is...
 01:20
Inverting and Non-inverting OpAmps
 01:13
Therapeutic Index
 01:21
Friedman Two-way Analysis of Variance by Ranks