Related Experiment Video
Updated: Apr 3, 2026

A Virtual Machine Platform for Non-Computer Professionals for Using Deep Learning to Classify Biological Sequences of Metagenomic Data
Published on: September 25, 2021
Deep Question Answering for protein annotation
Julien Gobeill1, Arnaud Gaudinat2, Emilie Pasche3
1BiTeM group, University of Applied Sciences-HEG, Library and Information Sciences, SIBTex group, Swiss Institute of Bioinformatics, julien.gobeill@hesge.ch.

Abstract:
Biomedical professionals have access to a huge amount of literature, but when they use a search engine, they often have to deal with too many documents to efficiently find the appropriate information in a reasonable time. In this perspective, question-answering (QA) engines are designed to display answers, which were automatically extracted from the retrieved documents. Standard QA engines in literature process a user question, then retrieve relevant documents and finally extract some possible answers out of these documents using various named-entity recognition processes. In our study, we try to answer complex genomics questions, which can be adequately answered only using Gene Ontology (GO) concepts. Such complex answers cannot be found using state-of-the-art dictionary- and redundancy-based QA engines. We compare the effectiveness of two dictionary-based classifiers for extracting correct GO answers from a large set of 100 retrieved abstracts per question. In the same way, we also investigate the power of GOCat, a GO supervised classifier. GOCat exploits the GOA database to propose GO concepts that were annotated by curators for similar abstracts. This approach is called deep QA, as it adds an original classification step, and exploits curated biological data to infer answers, which are not explicitly mentioned in the retrieved documents. We show that for complex answers such as protein functional descriptions, the redundancy phenomenon has a limited effect. Similarly usual dictionary-based approaches are relatively ineffective. In contrast, we demonstrate how existing curated data, beyond information extraction, can be exploited by a supervised classifier, such as GOCat, to massively improve both the quantity and the quality of the answers with a +100% improvement for both recall and precision. Database URL: http://eagl.unige.ch/DeepQA4PA/.

Related Concept Videos
 03:36
Genome Annotation and Assembly
 02:26
Conservation of Protein Domains Over Different Proteins
A limited set of protein domains often duplicate and recombine during evolution. These domains can be organized in different combinations to...
02:26Conservation of Protein Domains
 02:26
Protein Networks
These interactions can be represented through maps depicting protein-protein interaction networks, represented as nodes and edges. Nodes are circles that are representative of a protein,...
02:26Protein Networks
 02:15
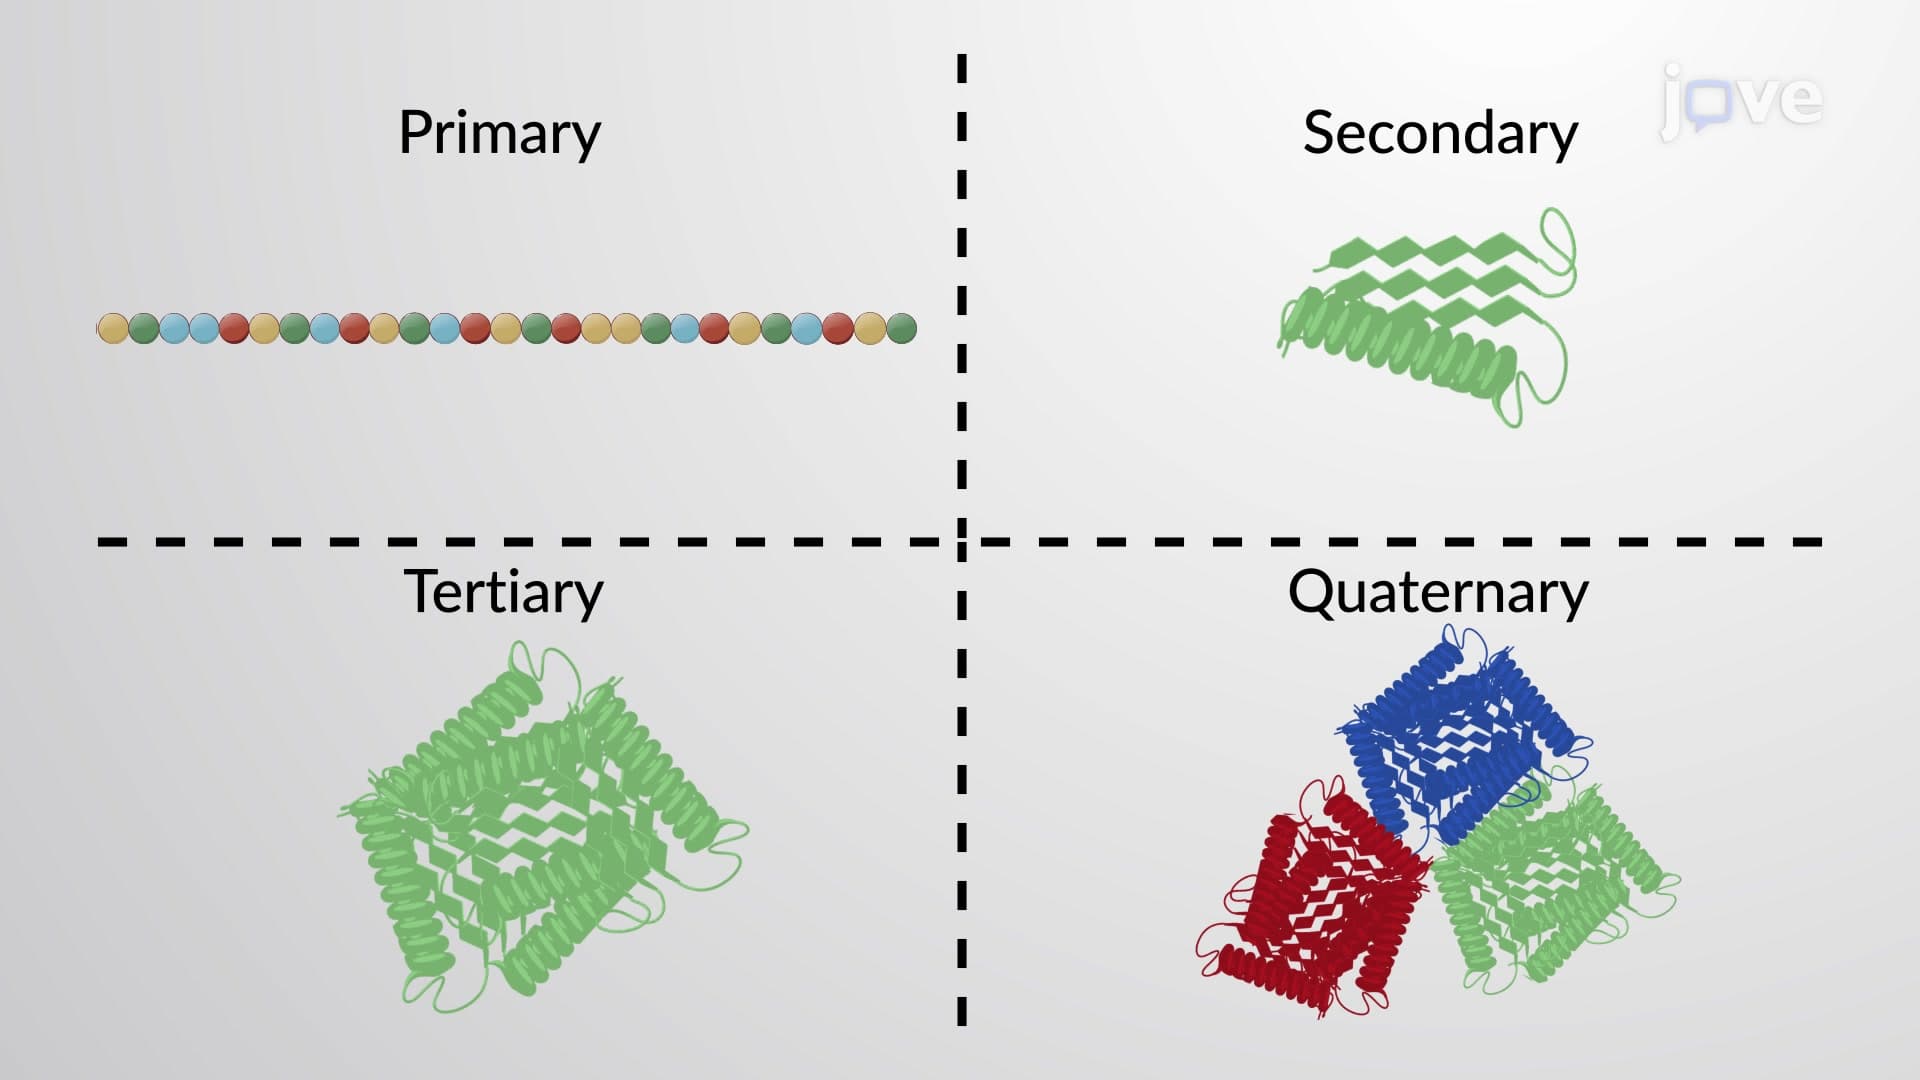
Protein and Protein Structure
A protein's shape is critical to its function. For example, an enzyme...