Related Experiment Video
Updated: Mar 30, 2026
Constructing and Visualizing Models using Mime-based Machine-learning Framework
Published on: July 22, 2025
Synthesis of clinical prediction models under different sets of covariates with one individual patient data
Daisuke Yoneoka1, Masayuki Henmi2, Norie Sawada3
1Department of Statistical Science, School of Multidisciplinary Sciences, SOKENDAI (The Graduate University for Advanced Studies), Tokyo, Japan. yoneoka.daisuke@ism.ac.jp.

Background:
Recently, increased development of clinical prediction models has been reported in the medical literature. However, evidence synthesis methodologies for these prediction models have not been sufficiently studied, especially for practical situations such as a meta-analyses where only aggregated summaries of important predictors are available. Also, in general, the covariate sets involved in the prediction models are not common across studies. As in ordinary model misspecification problems, dropping relevant covariates would raise potentially serious biases to the prediction models, and consequently to the synthesized results.
Methods:
We developed synthesizing methods for logistic clinical prediction models with possibly different sets of covariates. In order to aggregate the regression coefficient estimates from different prediction models, we adopted a generalized least squares approach with non-linear terms (a sort of generalization of multivariate meta-analysis). Firstly, we evaluated omitted variable biases in this approach. Then, under an assumption of homogeneity of studies, we developed bias-corrected estimating procedures for regression coefficients of the synthesized prediction models.
Results:
Numerical evaluations with simulations showed that our approach resulted in smaller biases and more precise estimates compared with conventional methods, which use only studies with common covariates or which utilize a mean imputation method for omitted coefficients. These methods were also applied to a series of Japanese epidemiologic studies on the incidence of a stroke.
Conclusions:
Our proposed methods adequately correct the biases due to different sets of covariates between studies, and would provide precise estimates compared with the conventional approach. If the assumption of homogeneity within studies is plausible, this methodology would be useful for incorporating prior published information into the construction of new prediction models.
Related Concept Videos
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis
 01:26
Pharmacokinetic Models: Comparison and Selection Criterion
Physiological models take a detailed approach by considering specific molecular processes. They can predict drug distribution, metabolism, and elimination changes, providing a comprehensive understanding of how drugs interact with the body.
 01:14
Analysis Methods of Pharmacokinetic Data: Model and Model-Independent Approaches
The model approach uses mathematical models to describe changes in drug concentration over time. Pharmacokinetic models help characterize drug behavior in patients, predict drug concentration in the body fluids, calculate optimum dosage regimens, and evaluate the risk of toxicity. However, ensuring that the model fits the experimental data accurately...
 01:09
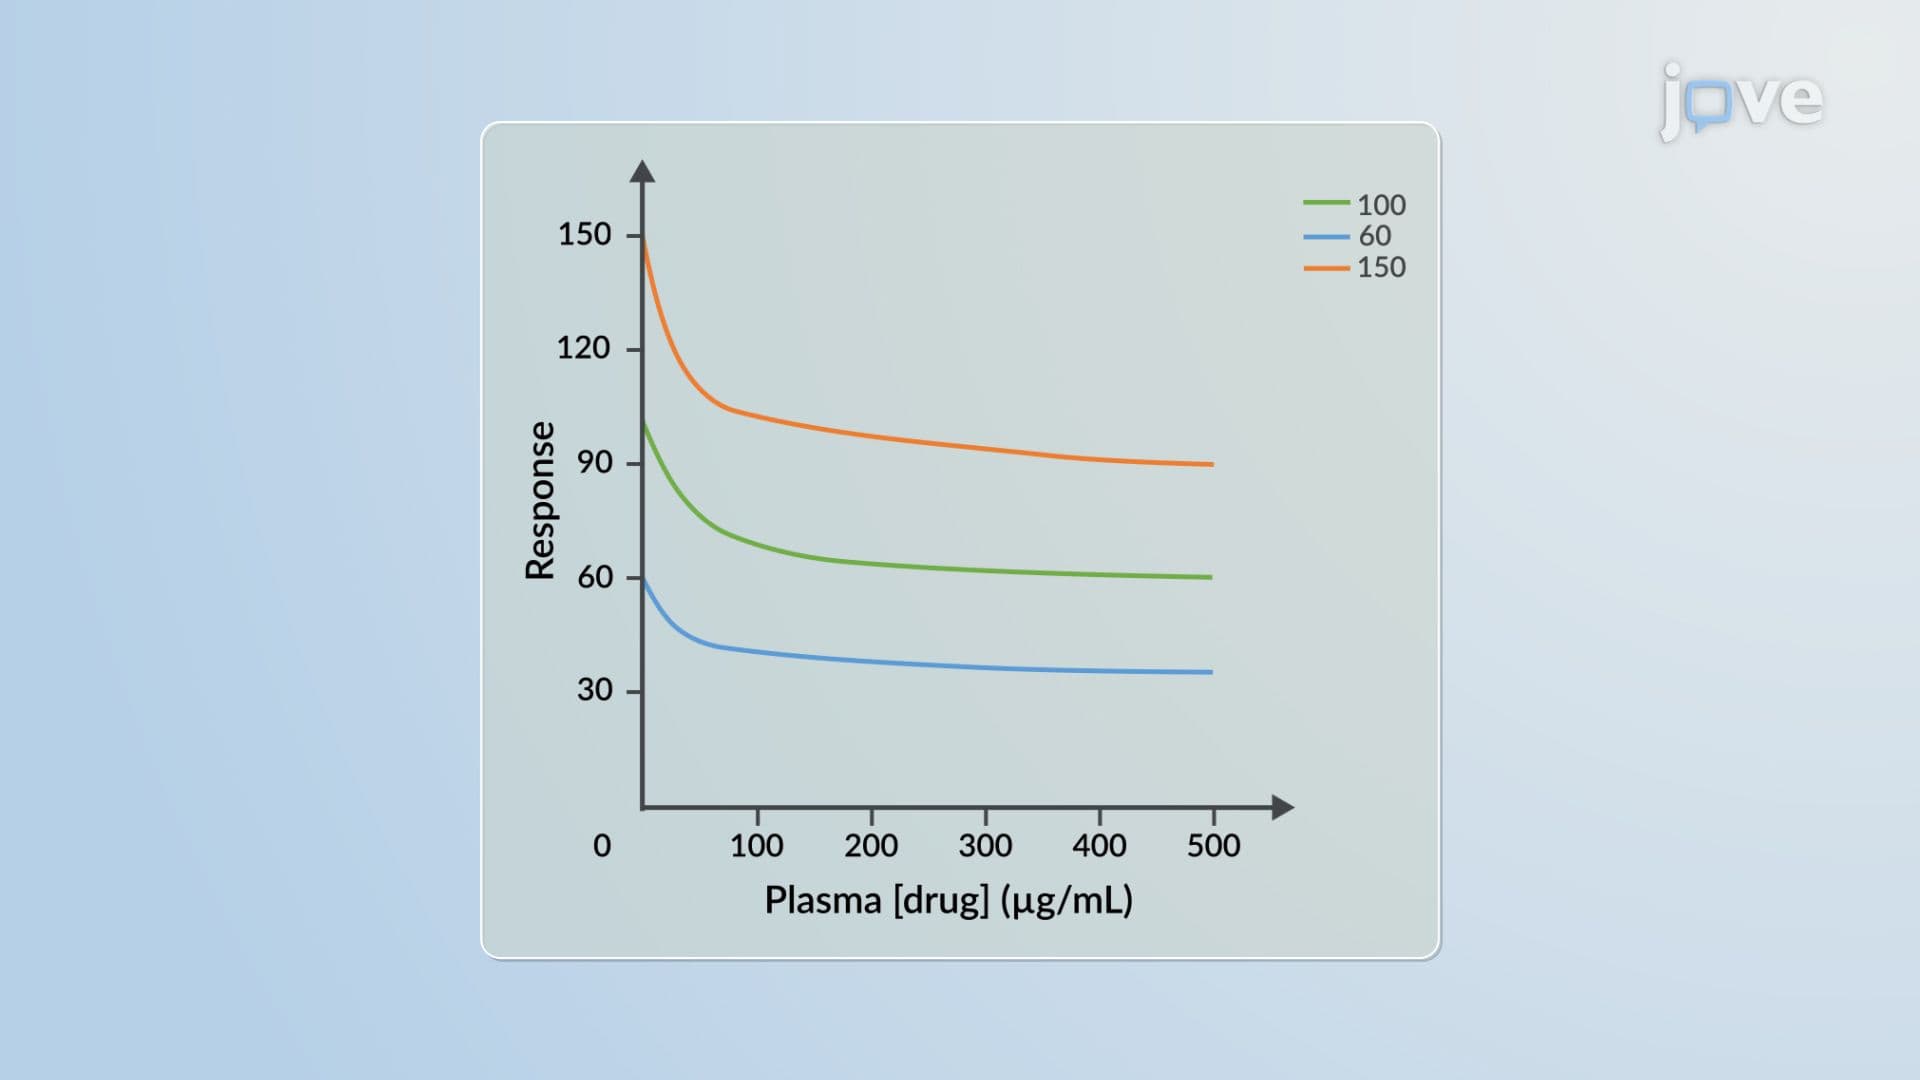
Pharmacodynamic Models: Additive and Proportional Drug Effect Model
 01:12
Analysis of Population Pharmacokinetic Data