Related Concept Videos

Identifying Statistically Significant Differences: The F-Test01:14

Identifying Statistically Significant Differences: The F-Test

The F-test is used to compare two sample variances to each other or compare the sample variance to the population variance. It is used to decide whether an indeterminate error can explain the difference in their values. The underlying assumptions that allow the use of the F-test include the data set or sets are normally distributed, and the data sets are independent of each other. The test statistic F is calculated by dividing one variance by another. In other words, the square of one standard...
4.2K
Friedman Two-way Analysis of Variance by Ranks01:21

Friedman Two-way Analysis of Variance by Ranks
Friedman's Two-Way Analysis of Variance by Ranks is a nonparametric test designed to identify differences across multiple test attempts when traditional assumptions of normality and equal variances do not apply. Unlike conventional ANOVA, which requires normally distributed data with equal variances, Friedman's test is ideal for ordinal or non-normally distributed data, making it particularly useful for analyzing dependent samples, such as matched subjects over time or repeated measures...
561
F Distribution01:19

F Distribution

The F distribution was named after Sir Ronald Fisher, an English statistician. The F statistic is a ratio (a fraction) with two sets of degrees of freedom; one for the numerator and one for the denominator. The F distribution is derived from the Student's t distribution. The values of the F distribution are squares of the corresponding values of the t distribution. One-Way ANOVA expands the t test for comparing more than two groups. The scope of that derivation is beyond the level of this...
10.9K
One-Way ANOVA: Equal Sample Sizes01:15

One-Way ANOVA: Equal Sample Sizes

One-Way ANOVA can be performed on three or more samples with equal or unequal sample sizes. When one-way ANOVA is performed on two datasets with samples of equal sizes, it can be easily observed that the computed F statistic is highly sensitive to the sample mean.
Different sample means can result in different values for the variance estimate: variance between samples. This is because the variance between samples is calculated as the product of the sample size and the variance between the...
4.4K
Expected Frequencies in Goodness-of-Fit Tests01:19

Expected Frequencies in Goodness-of-Fit Tests
A goodness-of-fit test is conducted to determine whether the observed frequency values are statistically similar to the frequencies expected for the dataset. Suppose the expected frequencies for a dataset are equal such as when predicting the frequency of any number appearing when casting a die. In that case, the expected frequency is the ratio of the total number of observations (n)  to the number of categories (k).
8.8K
Standard Deviation of Calculated Results01:14

Standard Deviation of Calculated Results

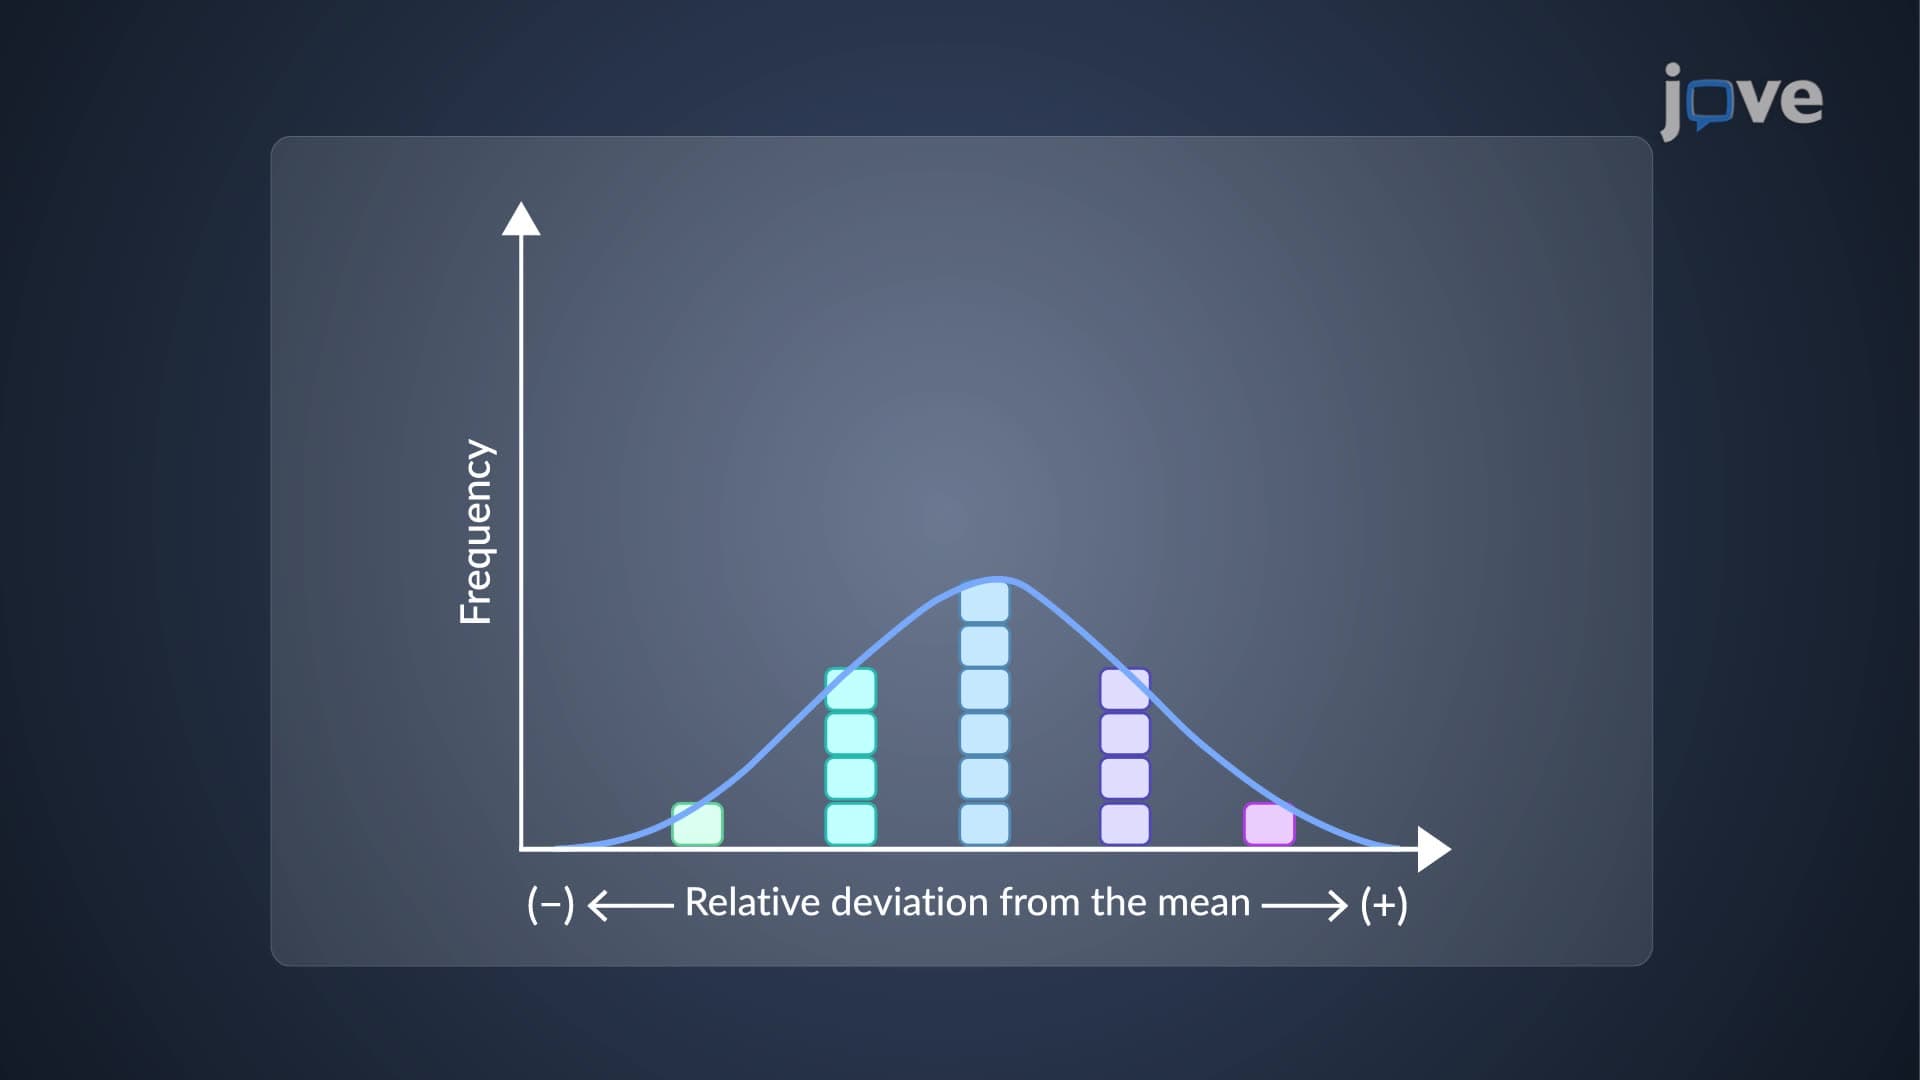
Standard deviation measures the spread of data around the mean value. Many large data sets follow a Gaussian distribution, also known as a normal distribution. This distribution is bell-shaped curved, with the most frequently observed value (mean or central value) in the middle. The farther away from the central value, the greater the deviation from the central value, and the lower the frequency.
A broad Gaussian distribution curve has a wider standard deviation, representing a data set with...
9.2K