Related Experiment Video
Updated: Mar 28, 2026

Basics of Multivariate Analysis in Neuroimaging Data
Published on: July 24, 2010
On the degrees of freedom of reduced-rank estimators in multivariate regression
A Mukherjee1, K Chen2, N Wang3
1Smart Forecasting Team, @WalmartLabs, 850 Cherry Avenue, San Bruno, California 94066, U.S.A.

Abstract:
We study the effective degrees of freedom of a general class of reduced-rank estimators for multivariate regression in the framework of Stein's unbiased risk estimation. A finite-sample exact unbiased estimator is derived that admits a closed-form expression in terms of the thresholded singular values of the least-squares solution and hence is readily computable. The results continue to hold in the high-dimensional setting where both the predictor and the response dimensions may be larger than the sample size. The derived analytical form facilitates the investigation of theoretical properties and provides new insights into the empirical behaviour of the degrees of freedom. In particular, we examine the differences and connections between the proposed estimator and a commonly-used naive estimator. The use of the proposed estimator leads to efficient and accurate prediction risk estimation and model selection, as demonstrated by simulation studies and a data example.

Related Concept Videos
 01:02
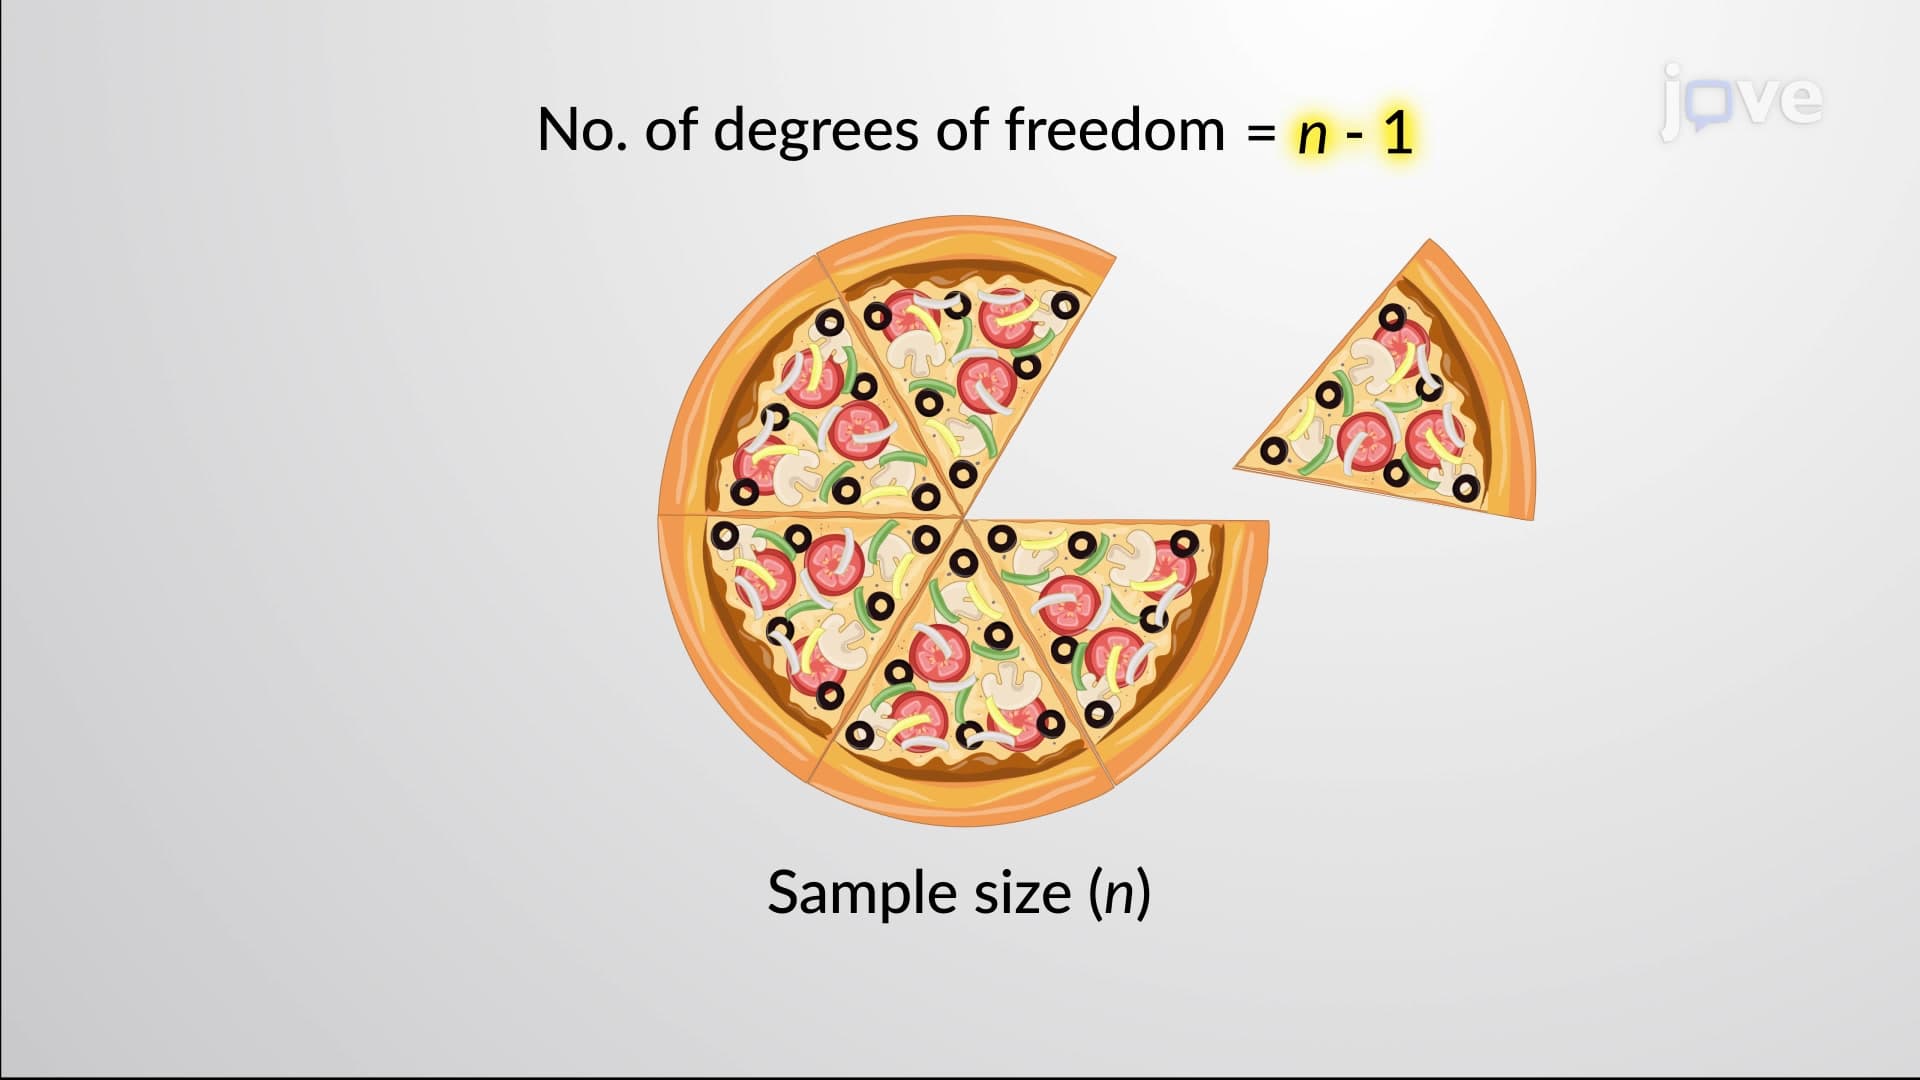
Degrees of Freedom
For example, suppose there are three unknown numbers whose mean is 10; although we can freely assign values to the first and second numbers, the value of the last number can not be arbitrarily assigned.
 01:02
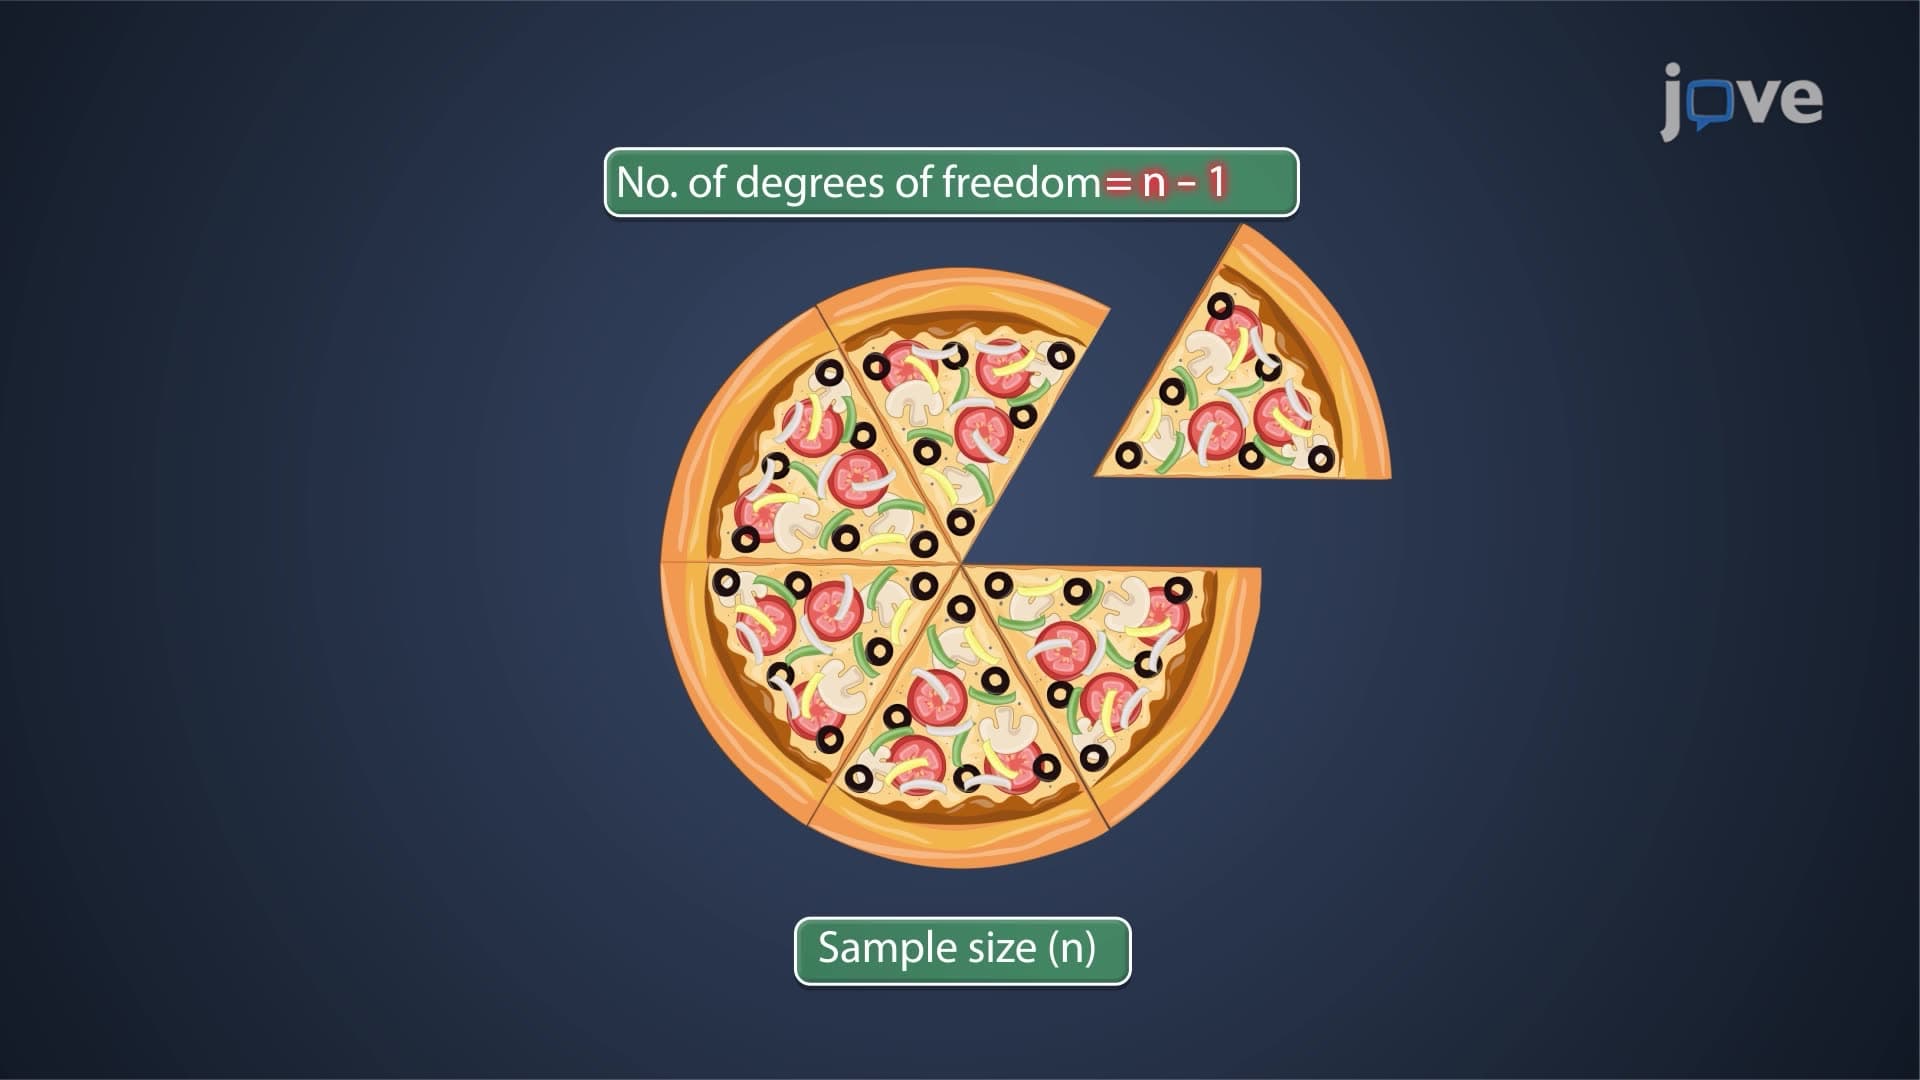
Degrees of Freedom
For example, suppose there are three unknown numbers whose mean is 10; although we can freely assign values to the first and second numbers, the value of the last number can not be arbitrarily...
 01:21
Friedman Two-way Analysis of Variance by Ranks
 01:19
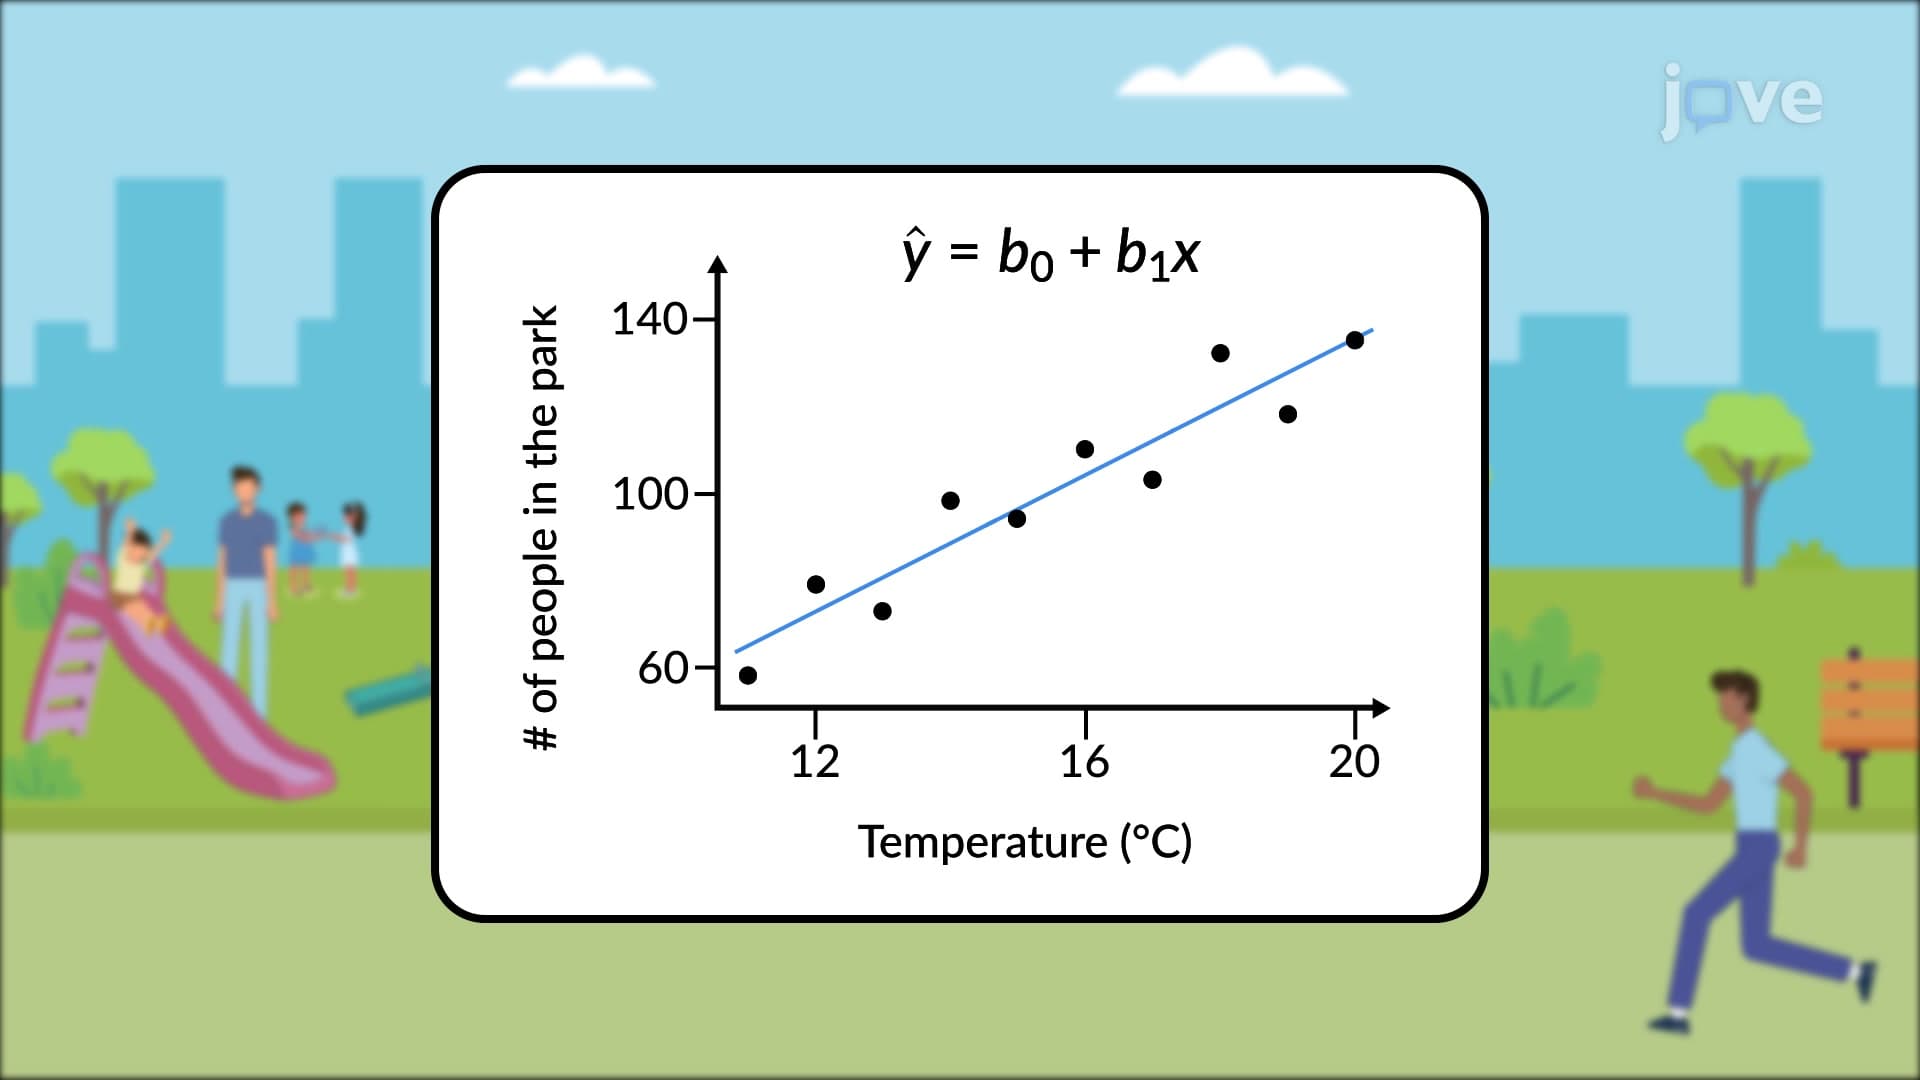
Variation
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
 01:25
Multiple Regression
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
On...