Related Experiment Video
Updated: Mar 27, 2026

Post-Movie Subliminal Measurement PMSM, for Investigating Implicit Social Bias
Published on: February 29, 2020
Empirical Study of User Preferences Based on Rating Data of Movies
1School of Economics and Management, Beijing Jiaotong University, Beijing, 100044, China.

Abstract:
User preference plays a prominent role in many fields, including electronic commerce, social opinion, and Internet search engines. Particularly in recommender systems, it directly influences the accuracy of the recommendation. Though many methods have been presented, most of these have only focused on how to improve the recommendation results. In this paper, we introduce an empirical study of user preferences based on a set of rating data about movies. We develop a simple statistical method to investigate the characteristics of user preferences. We find that the movies have potential characteristics of closure, which results in the formation of numerous cliques with a power-law size distribution. We also find that a user related to a small clique always has similar opinions on the movies in this clique. Then, we suggest a user preference model, which can eliminate the predictions that are considered to be impracticable. Numerical results show that the model can reflect user preference with remarkable accuracy when data elimination is allowed, and random factors in the rating data make prediction error inevitable. In further research, we will investigate many other rating data sets to examine the universality of our findings.
Related Concept Videos
 01:02
Ranks
 00:55
Ordinal Level of Measurement
Data measured using an ordinal scale are similar to nominal scale data, but there is one major difference. The ordinal scale data can be ordered. An example of ordinal scale data is a list of the top five national parks...
 01:10
Review and Preview
Percentiles are a type of fractile that partition data into...
 01:09
Empirical Method to Interpret Standard Deviation
This rule is used widely in statistics to calculate the proportion of data values...
 01:21
Friedman Two-way Analysis of Variance by Ranks
 01:16
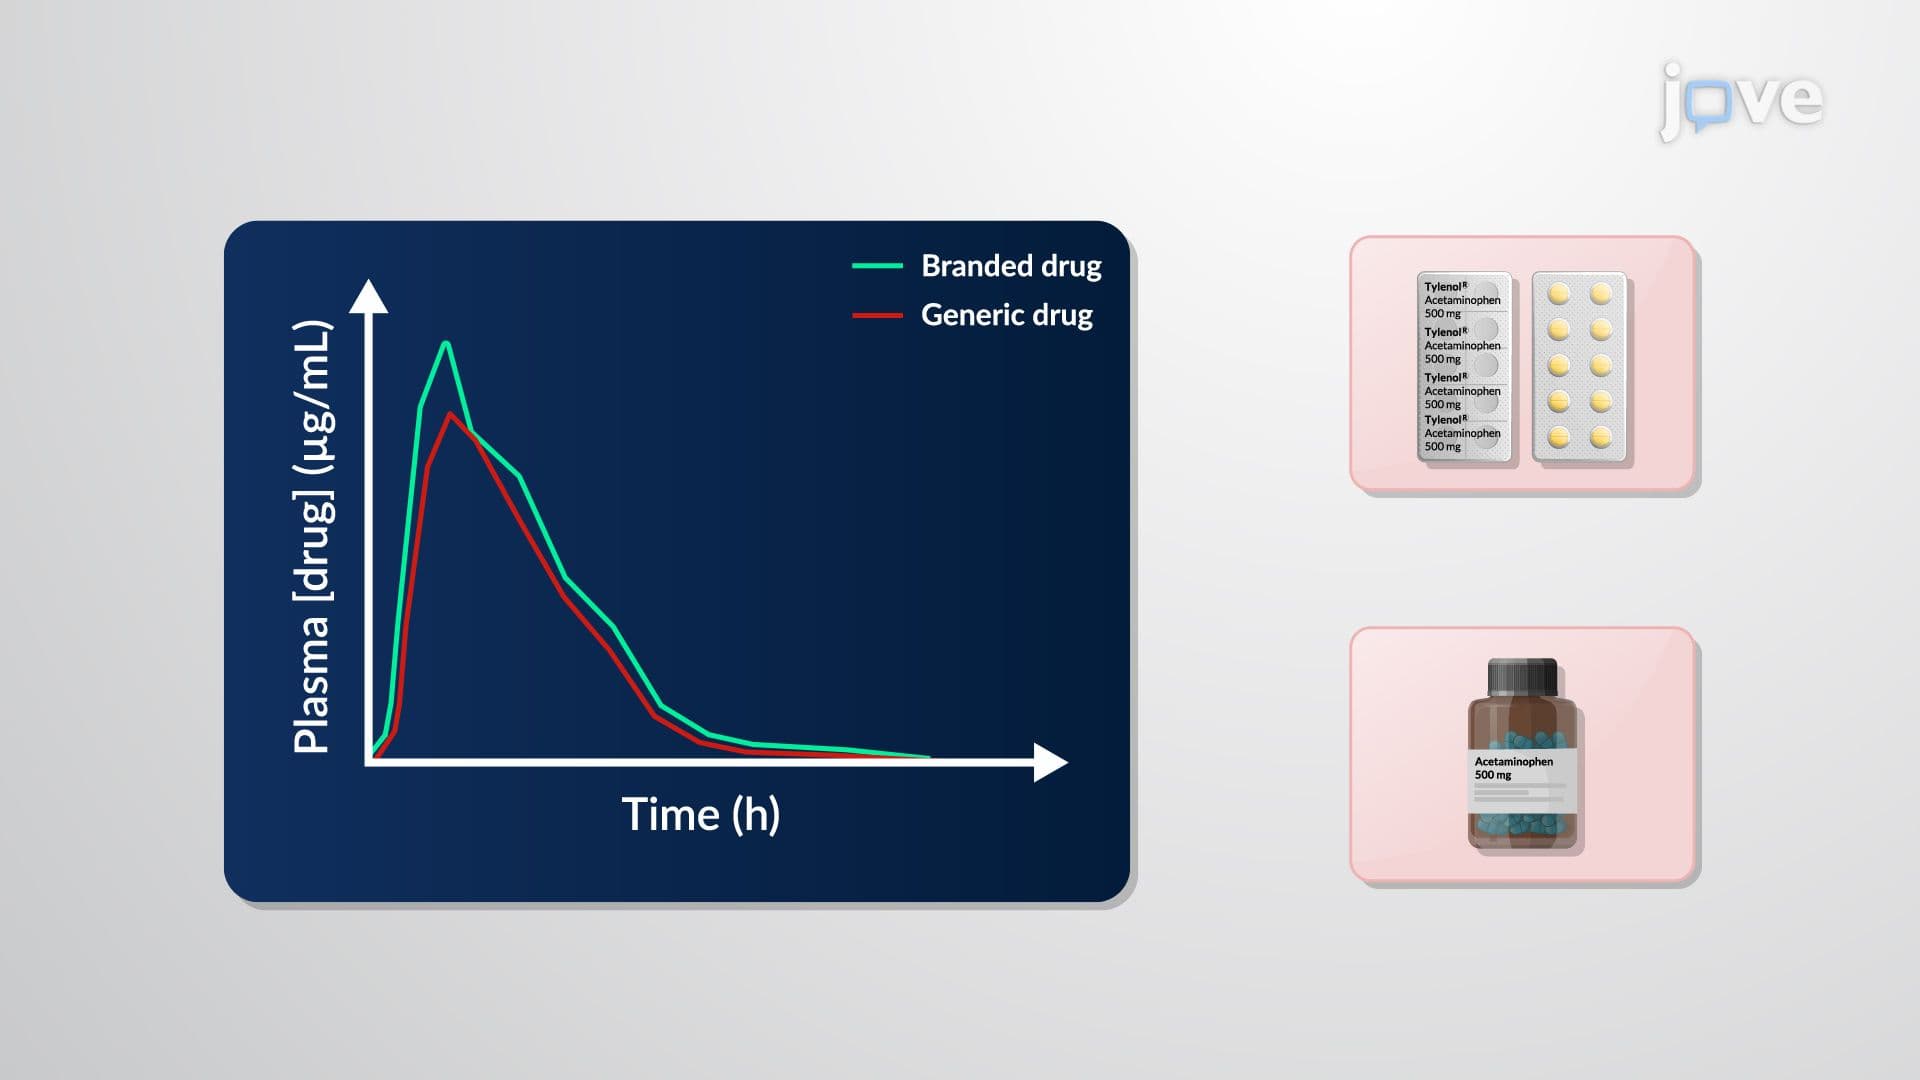
Bioequivalence Data: Statistical Interpretation