Related Experiment Video
Updated: Mar 26, 2026
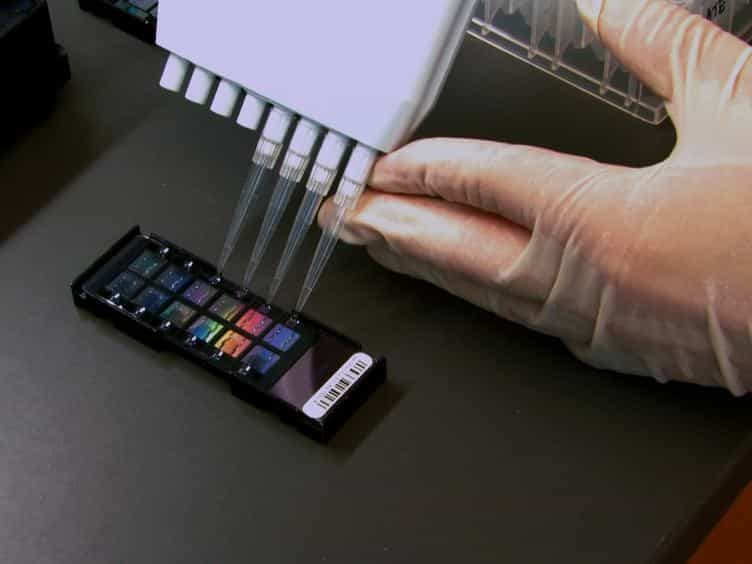

Infinium Assay for Large-scale SNP Genotyping Applications
Published on: November 19, 2013
Impact of imputation methods on the amount of genetic variation captured by a single-nucleotide polymorphism panel in
A Xavier1, William M Muir2, Katy M Rainey3
1Department of Agronomy, Purdue University, Lilly Hall of Life Sciences, 915 W. State St., West Lafayette, Indiana, 47907, USA. xaviera@purdue.edu.

Background:
Success in genome-wide association studies and marker-assisted selection depends on good phenotypic and genotypic data. The more complete this data is, the more powerful will be the results of analysis. Nevertheless, there are next-generation technologies that seek to provide genotypic information in spite of great proportions of missing data. The procedures these technologies use to impute genetic data, therefore, greatly affect downstream analyses. This study aims to (1) compare the genetic variance in a single-nucleotide polymorphism panel of soybean with missing data imputed using various methods, (2) evaluate the imputation accuracy and post-imputation quality associated with these methods, and (3) evaluate the impact of imputation method on heritability and the accuracy of genome-wide prediction of soybean traits. The imputation methods we evaluated were as follows: multivariate mixed model, hidden Markov model, logical algorithm, k-nearest neighbor, single value decomposition, and random forest. We used raw genotypes from the SoyNAM project and the following phenotypes: plant height, days to maturity, grain yield, and seed protein composition.
Results:
We propose an imputation method based on multivariate mixed models using pedigree information. Our methods comparison indicate that heritability of traits can be affected by the imputation method. Genotypes with missing values imputed with methods that make use of genealogic information can favor genetic analysis of highly polygenic traits, but not genome-wide prediction accuracy. The genotypic matrix captured the highest amount of genetic variance when missing loci were imputed by the method proposed in this paper.
Conclusions:
We concluded that hidden Markov models and random forest imputation are more suitable to studies that aim analyses of highly heritable traits while pedigree-based methods can be used to best analyze traits with low heritability. Despite the notable contribution to heritability, advantages in genomic prediction were not observed by changing the imputation method. We identified significant differences across imputation methods in a dataset missing 20 % of the genotypic values. It means that genotypic data from genotyping technologies that provide a high proportion of missing values, such as GBS, should be handled carefully because the imputation method will impact downstream analysis.

Related Concept Videos
 01:05
Single Nucleotide Polymorphisms-SNPs
 02:26
Comparing Copy Number Variations and SNPs
Copy number variations or CNVs are the structural variations that cover more than 1kb of DNA sequence. The single nucleotide polymorphism (SNP), on the other hand, is a single nucleotide change or a point mutation that is found in more than 1%...
 01:11
Genome-wide Association Studies-GWAS
GWAS does not require the identification of the target gene involved in...
 01:25
Genetic Variation
Genes exist in different versions called alleles,...
 01:27
Principles of Pharmacogenetics: Types of Genetic Variants
 01:18
Dihybrid Crosses