Related Experiment Video
Updated: Mar 25, 2026
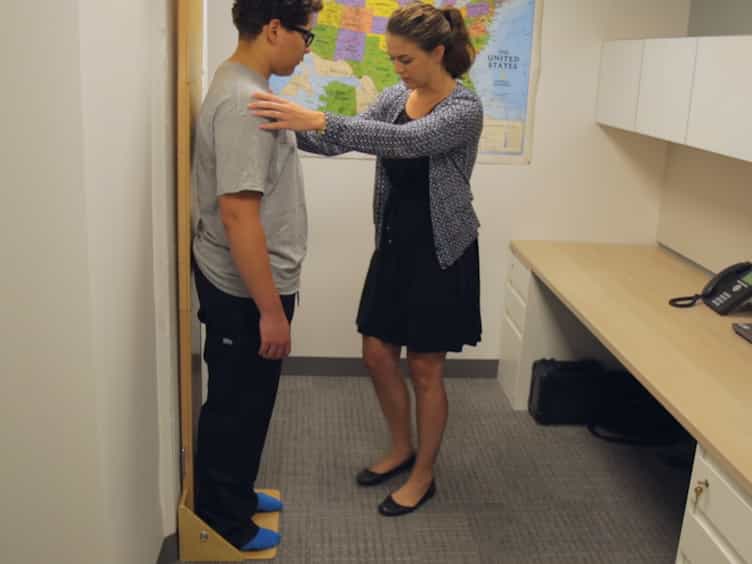

Assessment of Child Anthropometry in a Large Epidemiologic Study
Published on: February 2, 2017
Self-reported and measured weights and heights among adults in Seattle and King County
Wesley Tang1, Anju Aggarwal1, Anne Vernez Moudon2
1Center for Public Health Nutrition, University of Washington, Box 353410, Seattle, WA 98195 USA.

Background:
Self-reported weights and heights can be subject to gender, socio-economic, and other biases. On the other hand, obtaining measured anthropometric data can pose a significant respondent burden.
Methods:
Seattle Obesity Study II (SOS II) participants (n = 419) provided self-reported height, weight, and demographic data through an interviewer-assisted behavior survey. Participants were then weighed and measured by trained staff. The entire process was repeated 12 months later. At the follow up visit, participants were also asked to recall their weight from 12 months ago. The concordance between measured and self-reported data was assessed using Bland-Altman plots.
Results:
Some weight underreporting by obese individuals was observed. Gender or socio-economic status (SES) did not affect self-reports. Bland-Altman plots provided 95 % limits of agreement of -3.13 to 5.83 for weight (kg), and 1.21 to 2.52 for BMI (kg/m(2)). The concordance between measured and self-reported BMI categories was excellent (Kappa = 0.82 for men, and 0.86 for women). At the follow up visit, participants estimated their weight 12 months ago more accurately than their current weight.
Conclusions:
Self-reported heights and weights were highly correlated with objective measures at two points in time. No gender or SES biases were observed. Minor, yet statistically significant under-reporting (<1.5 kg) was observed for obese participants. Caution should be used when using self-reported data in obese populations.
More Related Videos
 06:48
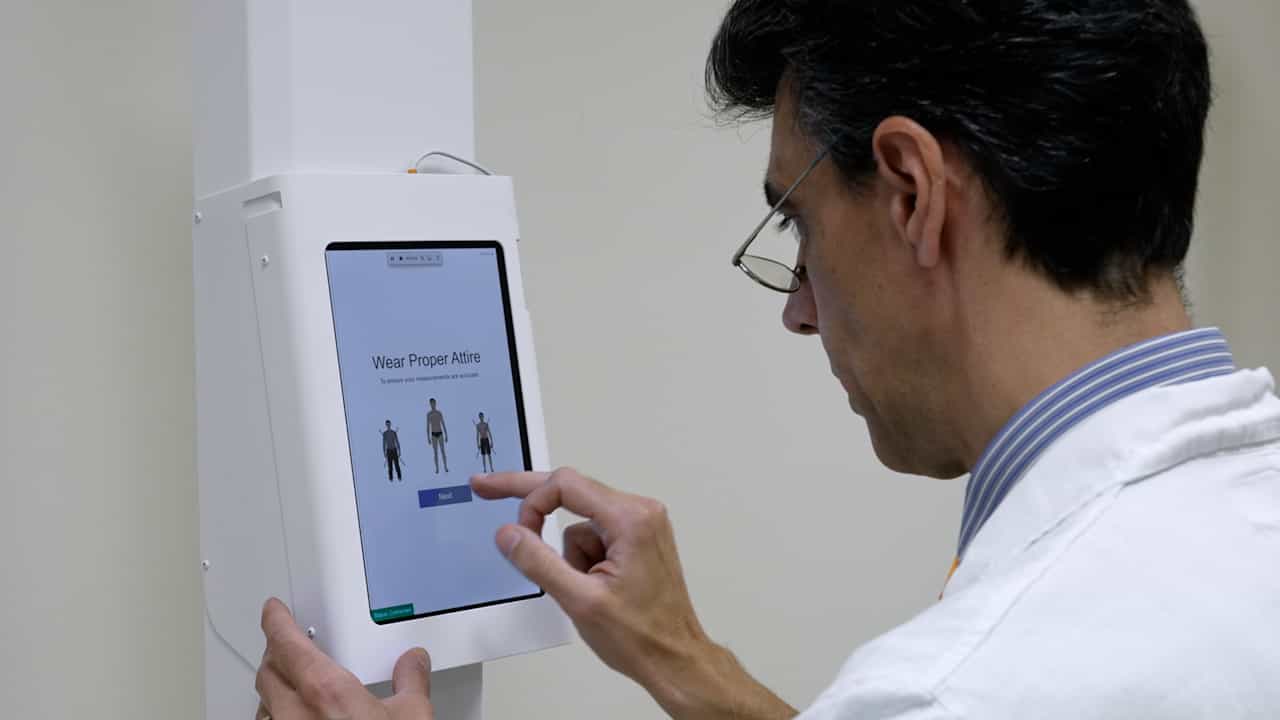
Author Spotlight: Advancements in 3D Optical Imaging for Comprehensive Body Composition Assessment in Modern Research
Published on: June 7, 2024
 05:59
Visualization of Intensity Levels to Reduce the Gap Between Self-Reported and Directly Measured Physical Activity
Published on: March 7, 2019
Related Concept Videos
 02:32
Variation: Normal Distribution, Range, and Standard Deviation
 01:06
What are Estimates?
The estimate for the mean of a sample is denoted by ͞x, whereas the mean of the population is designated as μ. Further, parameters such...
 01:15
One-Way ANOVA: Unequal Sample Sizes
 01:15
One-Way ANOVA: Equal Sample Sizes
Different sample means can result in different values for the variance estimate: variance between samples. This is because the variance between samples is calculated as the product of the sample size and the variance between the...
 02:16
Measures of Central Tendency
 01:12
Coefficient of Correlation
If you suspect a linear relationship between x and y, then r can measure how strong the linear relationship is.
What the VALUE of r tells us:
The value of r is always between –1 and +1: –1 ≤ r ≤ 1.
The size of the correlation r indicates the...