Related Experiment Video
Updated: Mar 23, 2026

Selecting Multiple Biomarker Subsets with Similarly Effective Binary Classification Performances
Published on: October 11, 2018
McTwo: a two-step feature selection algorithm based on maximal information coefficient
Ruiquan Ge1,2, Manli Zhou1,2, Youxi Luo1,3
1Shenzhen Institutes of Advanced Technology, and Key Lab for Health Informatics, Chinese Academy of Sciences, 1068 Xueyuan Avenue, Shenzhen University Town, Shenzhen, Guangdong, 518055, P.R. China.

Background:
High-throughput bio-OMIC technologies are producing high-dimension data from bio-samples at an ever increasing rate, whereas the training sample number in a traditional experiment remains small due to various difficulties. This "large p, small n" paradigm in the area of biomedical "big data" may be at least partly solved by feature selection algorithms, which select only features significantly associated with phenotypes. Feature selection is an NP-hard problem. Due to the exponentially increased time requirement for finding the globally optimal solution, all the existing feature selection algorithms employ heuristic rules to find locally optimal solutions, and their solutions achieve different performances on different datasets.
Results:
This work describes a feature selection algorithm based on a recently published correlation measurement, Maximal Information Coefficient (MIC). The proposed algorithm, McTwo, aims to select features associated with phenotypes, independently of each other, and achieving high classification performance of the nearest neighbor algorithm. Based on the comparative study of 17 datasets, McTwo performs about as well as or better than existing algorithms, with significantly reduced numbers of selected features. The features selected by McTwo also appear to have particular biomedical relevance to the phenotypes from the literature.
Conclusion:
McTwo selects a feature subset with very good classification performance, as well as a small feature number. So McTwo may represent a complementary feature selection algorithm for the high-dimensional biomedical datasets.
More Related Videos
Related Concept Videos
 01:14
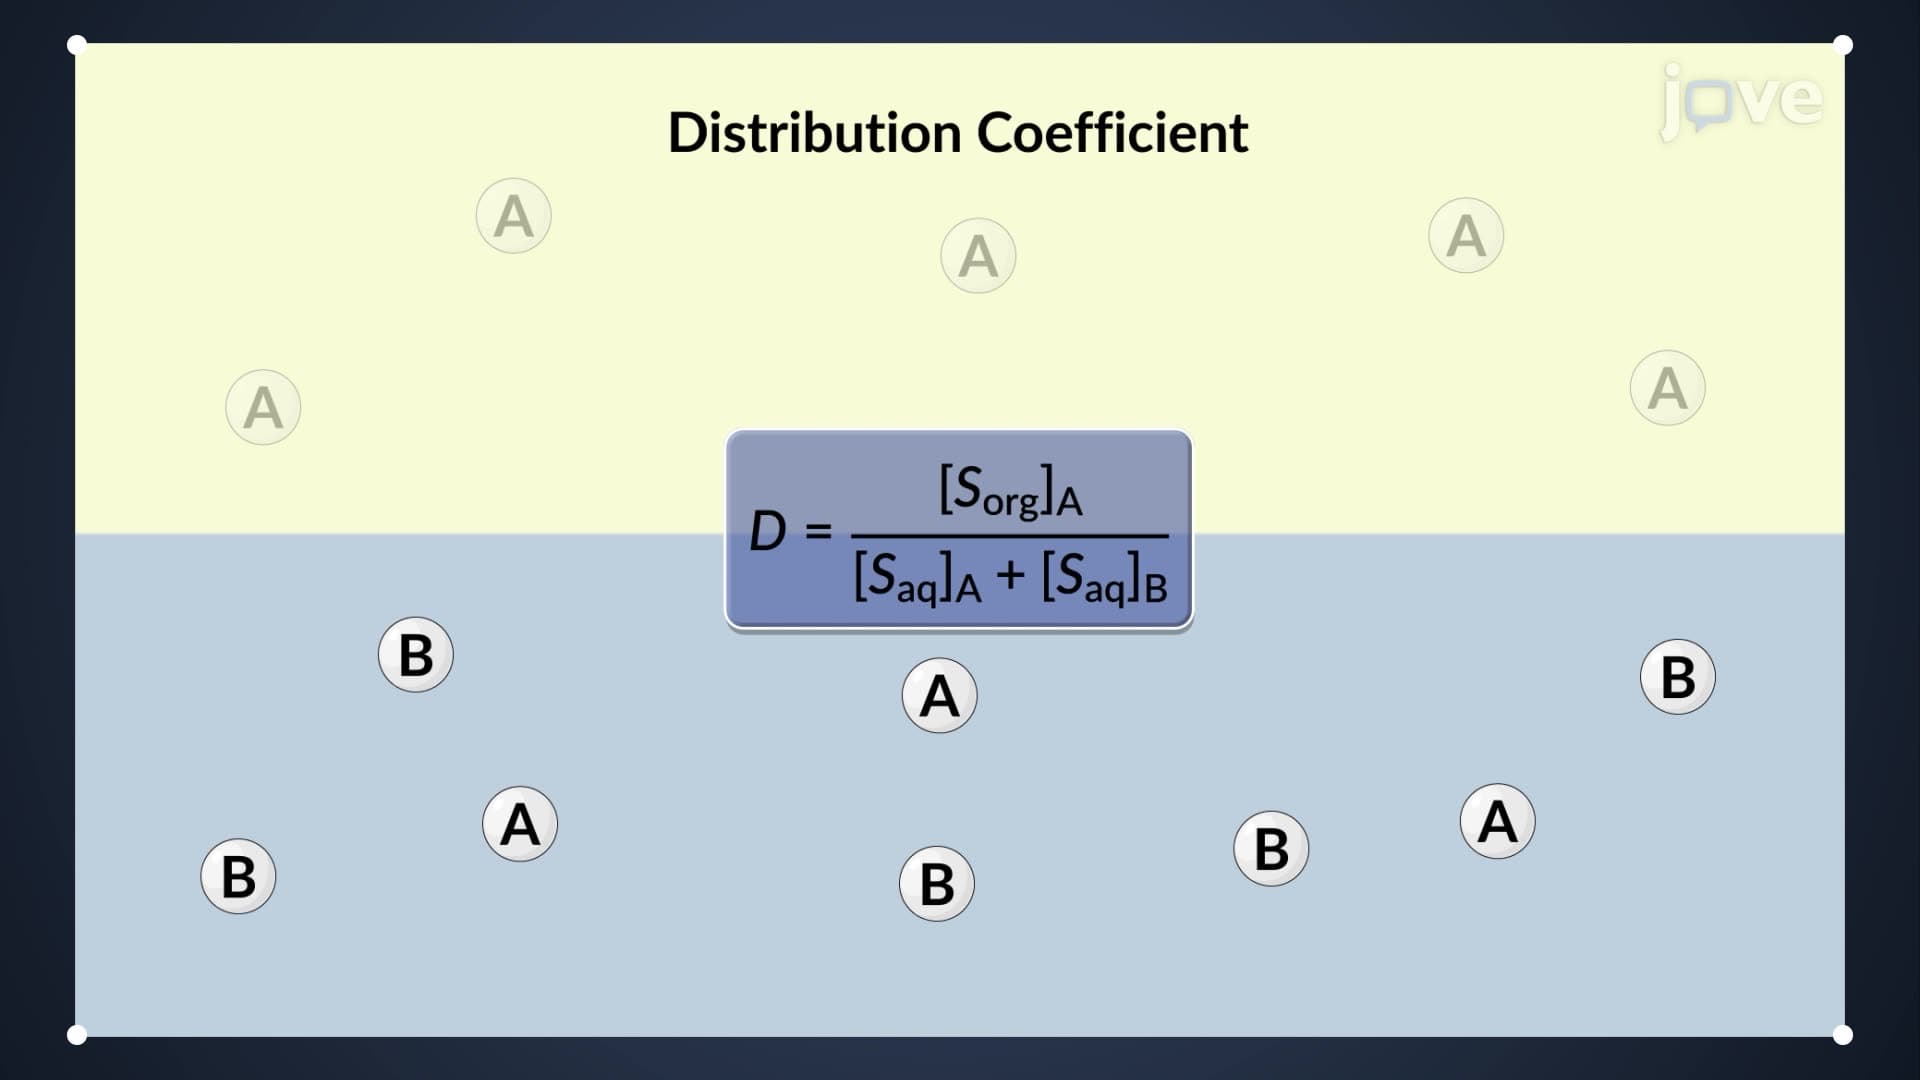
Extraction: Partition and Distribution Coefficients
For extracting a solute from an aqueous phase into an...
 01:28
Methods of Medium Optimization
 01:02
Quantifying and Rejecting Outliers: The Grubbs Test
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
On...
 01:13
Multiple Comparison Tests
It would be easy to compare two samples using a significance alpha level of 0.05. In other words, there is only one sample pair to be compared. However, it would be difficult to identify a significantly different sample if the number...
 01:08
Outliers and Influential Points