Bayesian Nonparametric Clustering for Positive Definite Matrices
Related Experiment Video
Updated: Mar 23, 2026

Large-scale Reconstructions and Independent, Unbiased Clustering Based on Morphological Metrics to Classify Neurons in Selective Populations
Published on: February 15, 2017

Abstract:
Symmetric Positive Definite (SPD) matrices emerge as data descriptors in several applications of computer vision such as object tracking, texture recognition, and diffusion tensor imaging. Clustering these data matrices forms an integral part of these applications, for which soft-clustering algorithms (K-Means, expectation maximization, etc.) are generally used. As is well-known, these algorithms need the number of clusters to be specified, which is difficult when the dataset scales. To address this issue, we resort to the classical nonparametric Bayesian framework by modeling the data as a mixture model using the Dirichlet process (DP) prior. Since these matrices do not conform to the Euclidean geometry, rather belongs to a curved Riemannian manifold,existing DP models cannot be directly applied. Thus, in this paper, we propose a novel DP mixture model framework for SPD matrices. Using the log-determinant divergence as the underlying dissimilarity measure to compare these matrices, and further using the connection between this measure and the Wishart distribution, we derive a novel DPM model based on the Wishart-Inverse-Wishart conjugate pair. We apply this model to several applications in computer vision. Our experiments demonstrate that our model is scalable to the dataset size and at the same time achieves superior accuracy compared to several state-of-the-art parametric and nonparametric clustering algorithms.


Related Concept Videos
 01:30
Gaussian Elimination: Problem Solving
 01:20
Cluster Sampling Method
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
 01:08
Vector Algebra: Method of Components
In many applications, the magnitudes and directions of...
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance,...
 01:19
Routh-Hurwitz Criterion II
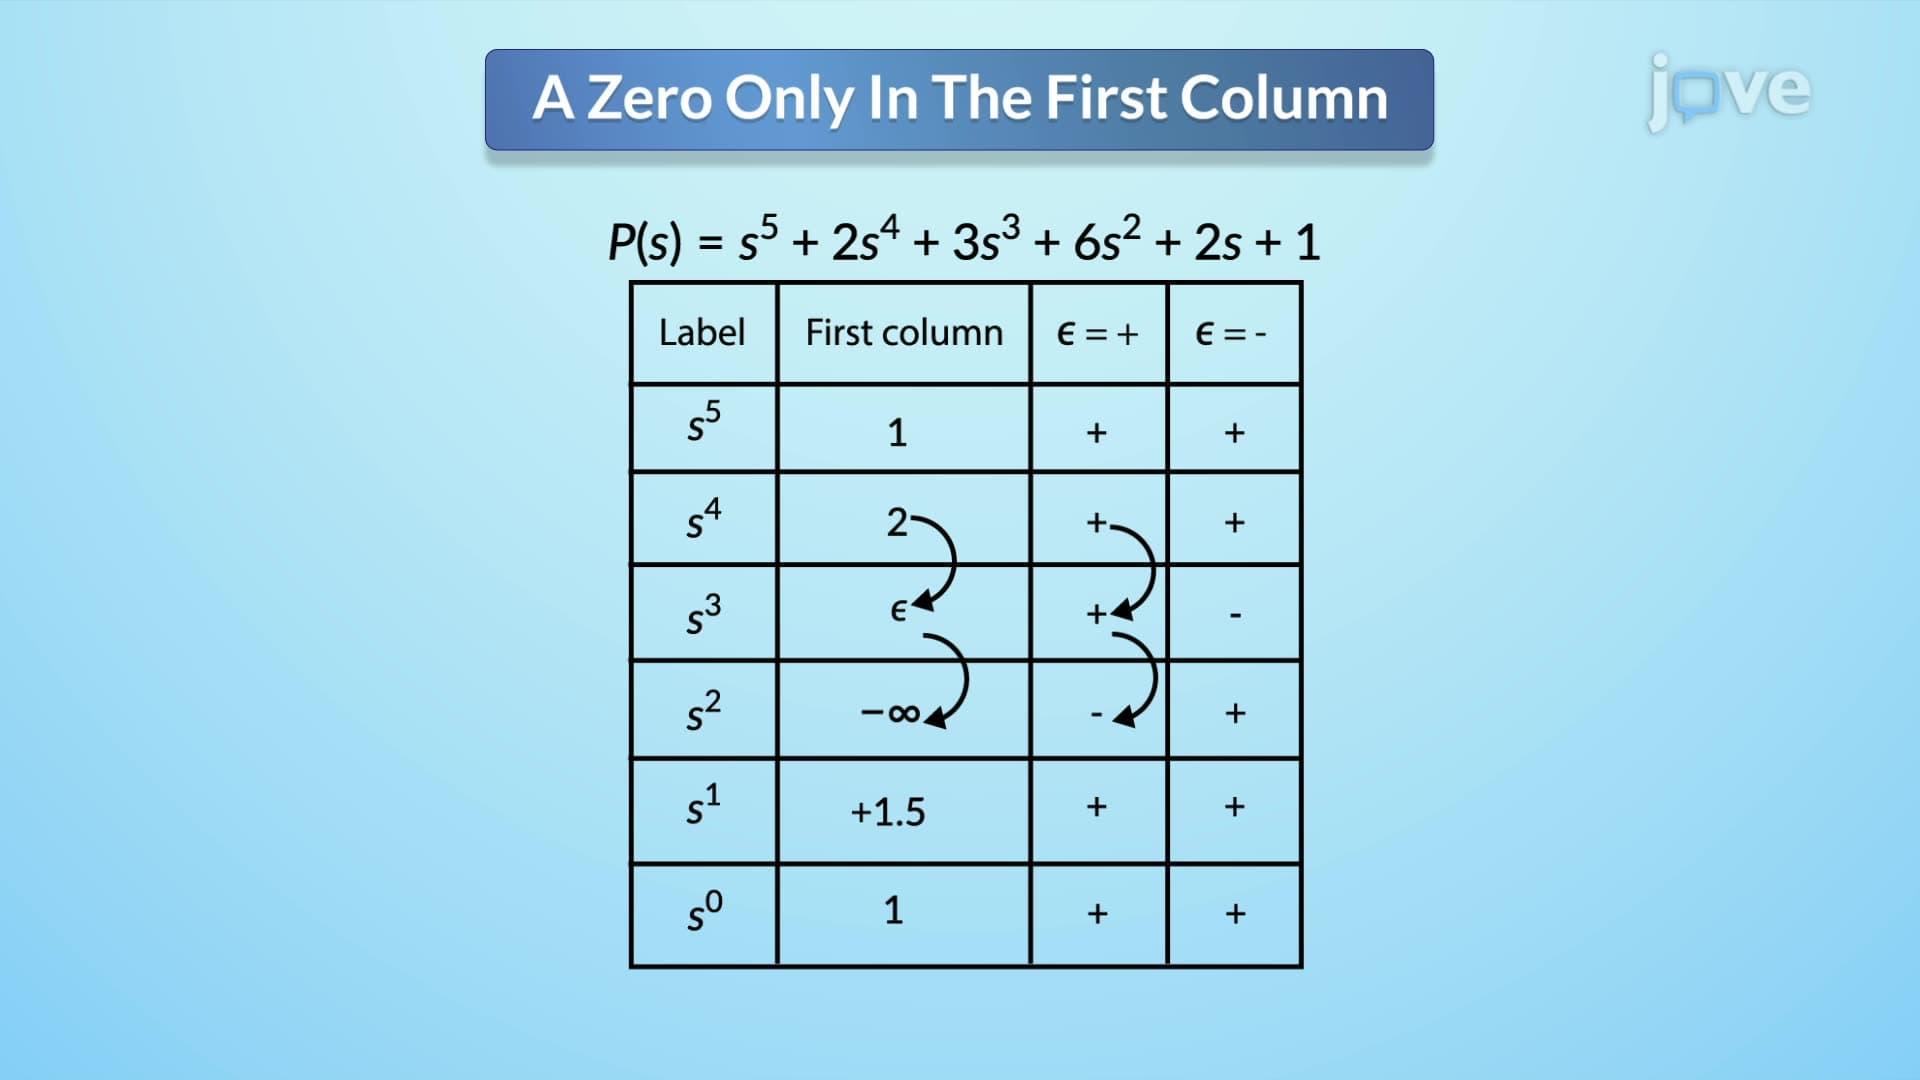
The first scenario occurs when a singular zero appears in the first column of the Routh table. This situation creates a division by zero issues. To resolve this, a small positive or negative number, denoted as epsilon (∈), is substituted for the zero. The stability analysis proceeds by assuming a sign for ∈. If ∈ is positive, any sign change in the first...
 01:15
Routh-Hurwitz Criterion I
To apply the Routh-Hurwitz criterion, a Routh table is constructed. The table's rows are labeled with powers of the complex frequency variable s, starting from the...