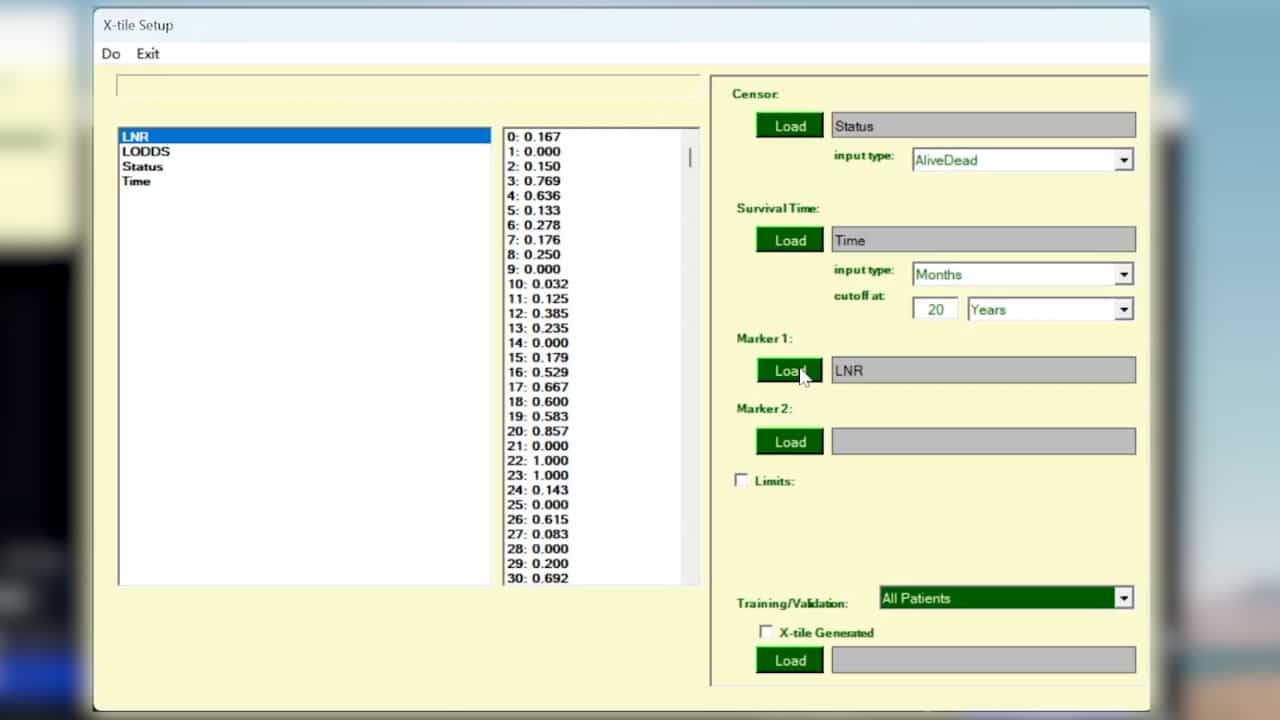

Stata Modules for Calculating Novel Predictive Performance Indices for Logistic Models
Mahnaz Barkhordari1, Mojgan Padyab2, Farzad Hadaegh3
1Department of Mathematics, Bandar Abbas Branch, Islamic Azad University, Bandar Abbas, IR Iran.

Background:
Prediction is a fundamental part of prevention of cardiovascular diseases (CVD). The development of prediction algorithms based on the multivariate regression models loomed several decades ago. Parallel with predictive models development, biomarker researches emerged in an impressively great scale. The key question is how best to assess and quantify the improvement in risk prediction offered by new biomarkers or more basically how to assess the performance of a risk prediction model. Discrimination, calibration, and added predictive value have been recently suggested to be used while comparing the predictive performances of the predictive models' with and without novel biomarkers.
Objectives:
Lack of user-friendly statistical software has restricted implementation of novel model assessment methods while examining novel biomarkers. We intended, thus, to develop a user-friendly software that could be used by researchers with few programming skills.
Materials And Methods:
We have written a Stata command that is intended to help researchers obtain cut point-free and cut point-based net reclassification improvement index and (NRI) and relative and absolute Integrated discriminatory improvement index (IDI) for logistic-based regression analyses.We applied the commands to a real data on women participating the Tehran lipid and glucose study (TLGS) to examine if information of a family history of premature CVD, waist circumference, and fasting plasma glucose can improve predictive performance of the Framingham's "general CVD risk" algorithm.
Results:
The command is addpred for logistic regression models.
Conclusions:
The Stata package provided herein can encourage the use of novel methods in examining predictive capacity of ever-emerging plethora of novel biomarkers.

Related Concept Videos
 01:11
Regression Analysis
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
 01:09
Statistical Methods to Analyze Parametric Data: Student t-Test and Goodness-of-Fit Test
The Student's t-test is a statistical test that examines if there is a statistically significant difference between the means of two groups. This test is instrumental when dealing with...
 01:11
Statistical Analysis: Overview
One of the most commonly used statistical quantifiers is the mean, which is the ratio between the sum of the numerical values of all results and the...
 01:14
Statistical Analysis System (SAS)
Applications: SAS finds applications in numerous fields, including healthcare for clinical trial analysis, finance for risk assessment, marketing for customer data analysis, and...
 01:16
Goodness-of-Fit Test
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.